

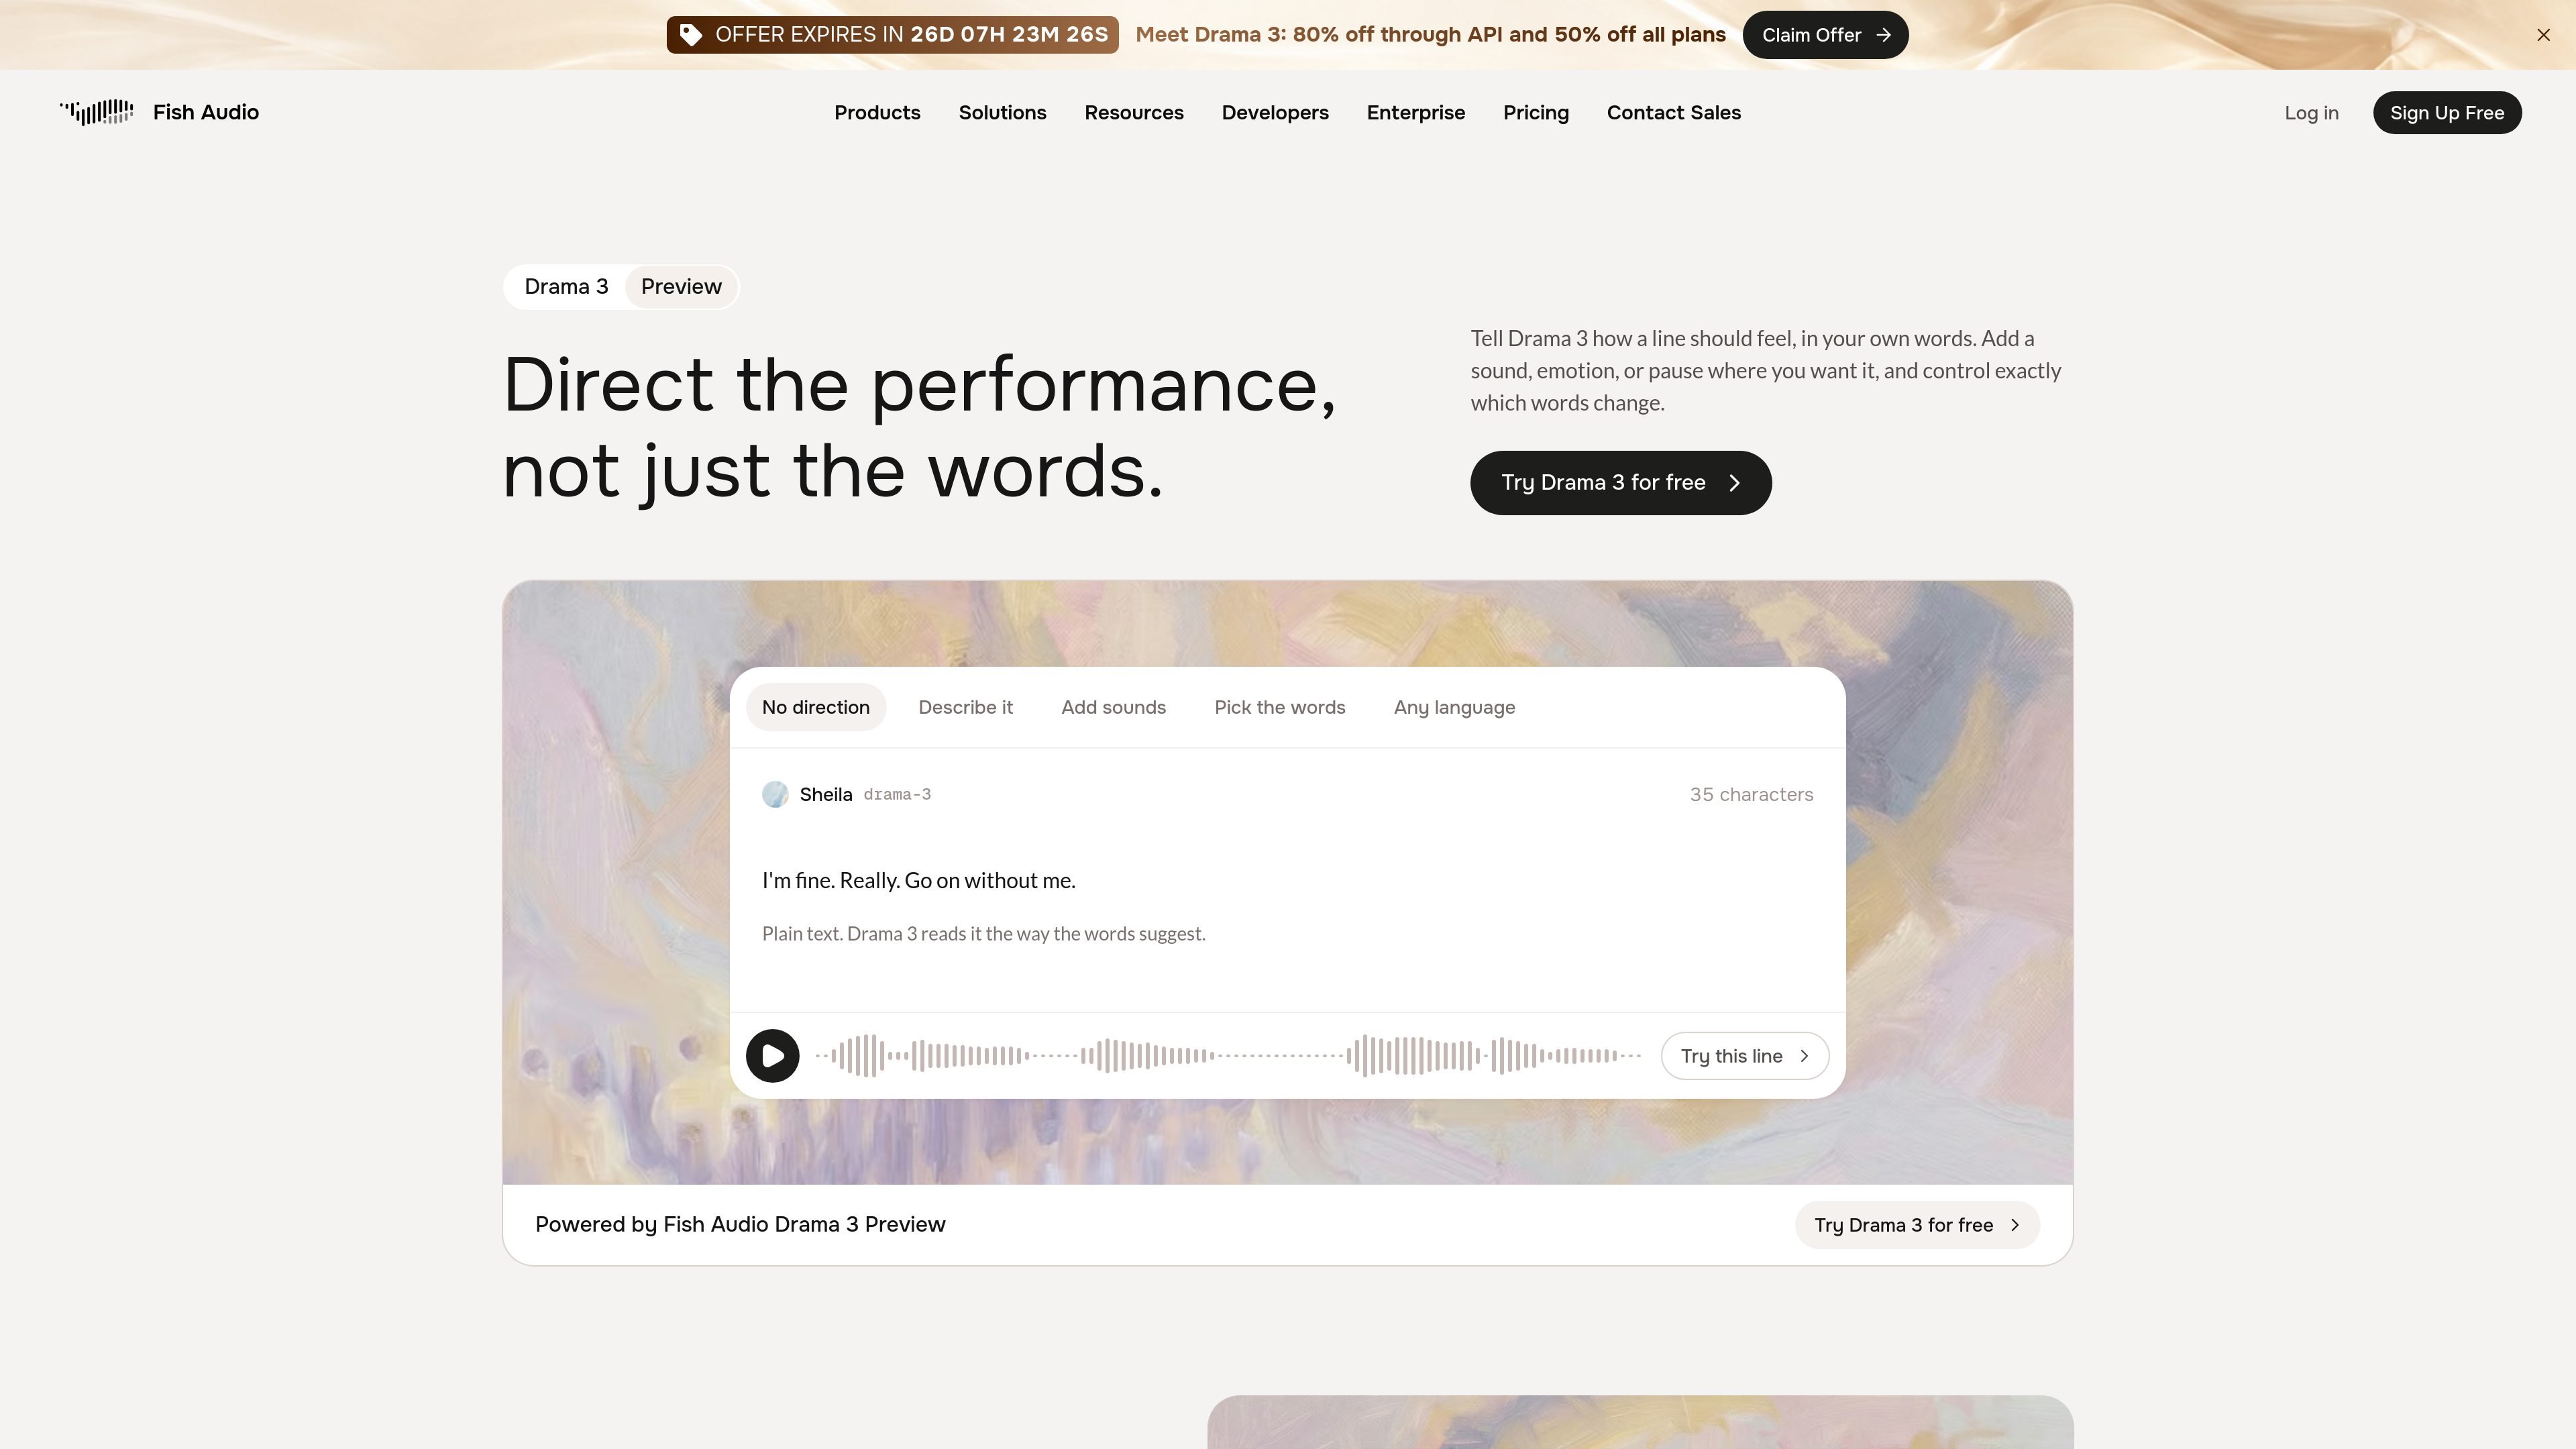
Describe the performance
Add natural-language notes about emotion, intent, pacing, or the relationship between speakers directly alongside the script.
Drama 3 is Fish Audio’s directable text-to-speech model. It generates speech from a script while also interpreting written directions about how lines should be performed, rather than treating the input as plain text alone.
The workflow supports inline performance notes, sounds, pauses, and word-level controls. It is available in the Fish Audio Text to Speech editor and can also be called through the API with the drama-3 model identifier. The product page describes the model as being in preview, so results can vary between takes and users may need to generate several versions.
Add natural-language notes about emotion, intent, pacing, or the relationship between speakers directly alongside the script.
Insert sounds, emotions, breaths, laughs, sighs, or pauses at specific points in a line using inline directions.
Apply scoped tags such as Whisper, Emphasis, Soft, Faster, Slower, or Forceful to only the words that need a different delivery.
Write directions and tags in English or another language while keeping the directions within the script workflow.
Use Auto Tag to add starting directions to a script, then edit or replace them before generating.
Add multiple speakers, assign voices, and generate a complete dialogue scene in one pass.
Write dialogue with speaker names and scene context, assign voices, and generate a complete exchange together instead of producing every line separately.
Add delivery notes such as warmth, hesitation, skepticism, or a near-whisper to shape character performances for scripted scenes.
Place pauses, breaths, laughs, or other inline sounds at exact points in narration and dialogue when timing and texture matter.
Send directed scripts to the Text to Speech API for applications or production workflows that need generated audio from reusable text templates.
Drama 3 is a Fish Audio text-to-speech model designed for directing vocal performance alongside the script. You can describe delivery, add sounds or pauses, and apply effects to selected words.
Place a direction or sound in square brackets where it should occur, such as [sigh] or [barely holding it together]. For selected-word effects, use a scoped tag that wraps only the chosen words.
Yes. Directions and tags can be written in English or in the language you use for the script.
Yes. In the Text to Speech editor, you can add speakers, assign each one a voice, and generate the dialogue together in one pass.
Yes. Use the Text to Speech API with the model header set to drama-3. The page shows scripts with directions, sounds, and paired tags being sent in the request.
Fylom is an AI podcast generator that turns a topic or question into a researched narrated episode. It supports typed or spoken prompts, voice selection, and recurring show-style listening.

Gemini 3.8 Text-to-Speech is Google’s pair of expressive audio models for turning scripts into customizable spoken audio. Creators, developers and enterprises can design voices, direct delivery line by line, and generate dialogue for content, dubbing and voice-agent applications.

Kugel 3.5 is KugelAudio’s text-to-speech model for voice agents and phone conversations, with controls for short replies, IPA pronunciation, timed pauses and character-by-character codes. It retains Kugel 3’s documented voices, languages, dictionaries and API while charging €0.0525 per audio minute excluding VAT, billed per second.

Gemini 3.1 Flash TTS is Google’s preview text-to-speech model for generating expressive AI speech with fine-grained control over style and delivery. It is available across the Gemini API, Google AI Studio, Vertex AI, and Google Vids.

蓝藻AI是一款在线AI配音与语音合成产品,可将文字转成语音,并支持自助声音克隆。页面信息显示它面向短视频、有声书等需要配音的内容场景。
Ondoku 是一款基于浏览器的文字转语音软件,可将文本转换为可下载的 .mp3 语音,并提供免费额度与付费方案。它支持多语言朗读、图片朗读以及按规则商用。