
Managed OpenAI-compatible API
Use managed GPUs and production inference APIs through Netra Cloud, without operating the underlying GPU infrastructure.

Netra Runtime is an AI inference engine for production workloads, available through Netra Cloud's OpenAI-compatible API or as a private deployment on customer-controlled AMD or NVIDIA GPU infrastructure. It helps teams optimize model serving, monitor workloads, and retain control over their data and infrastructure.
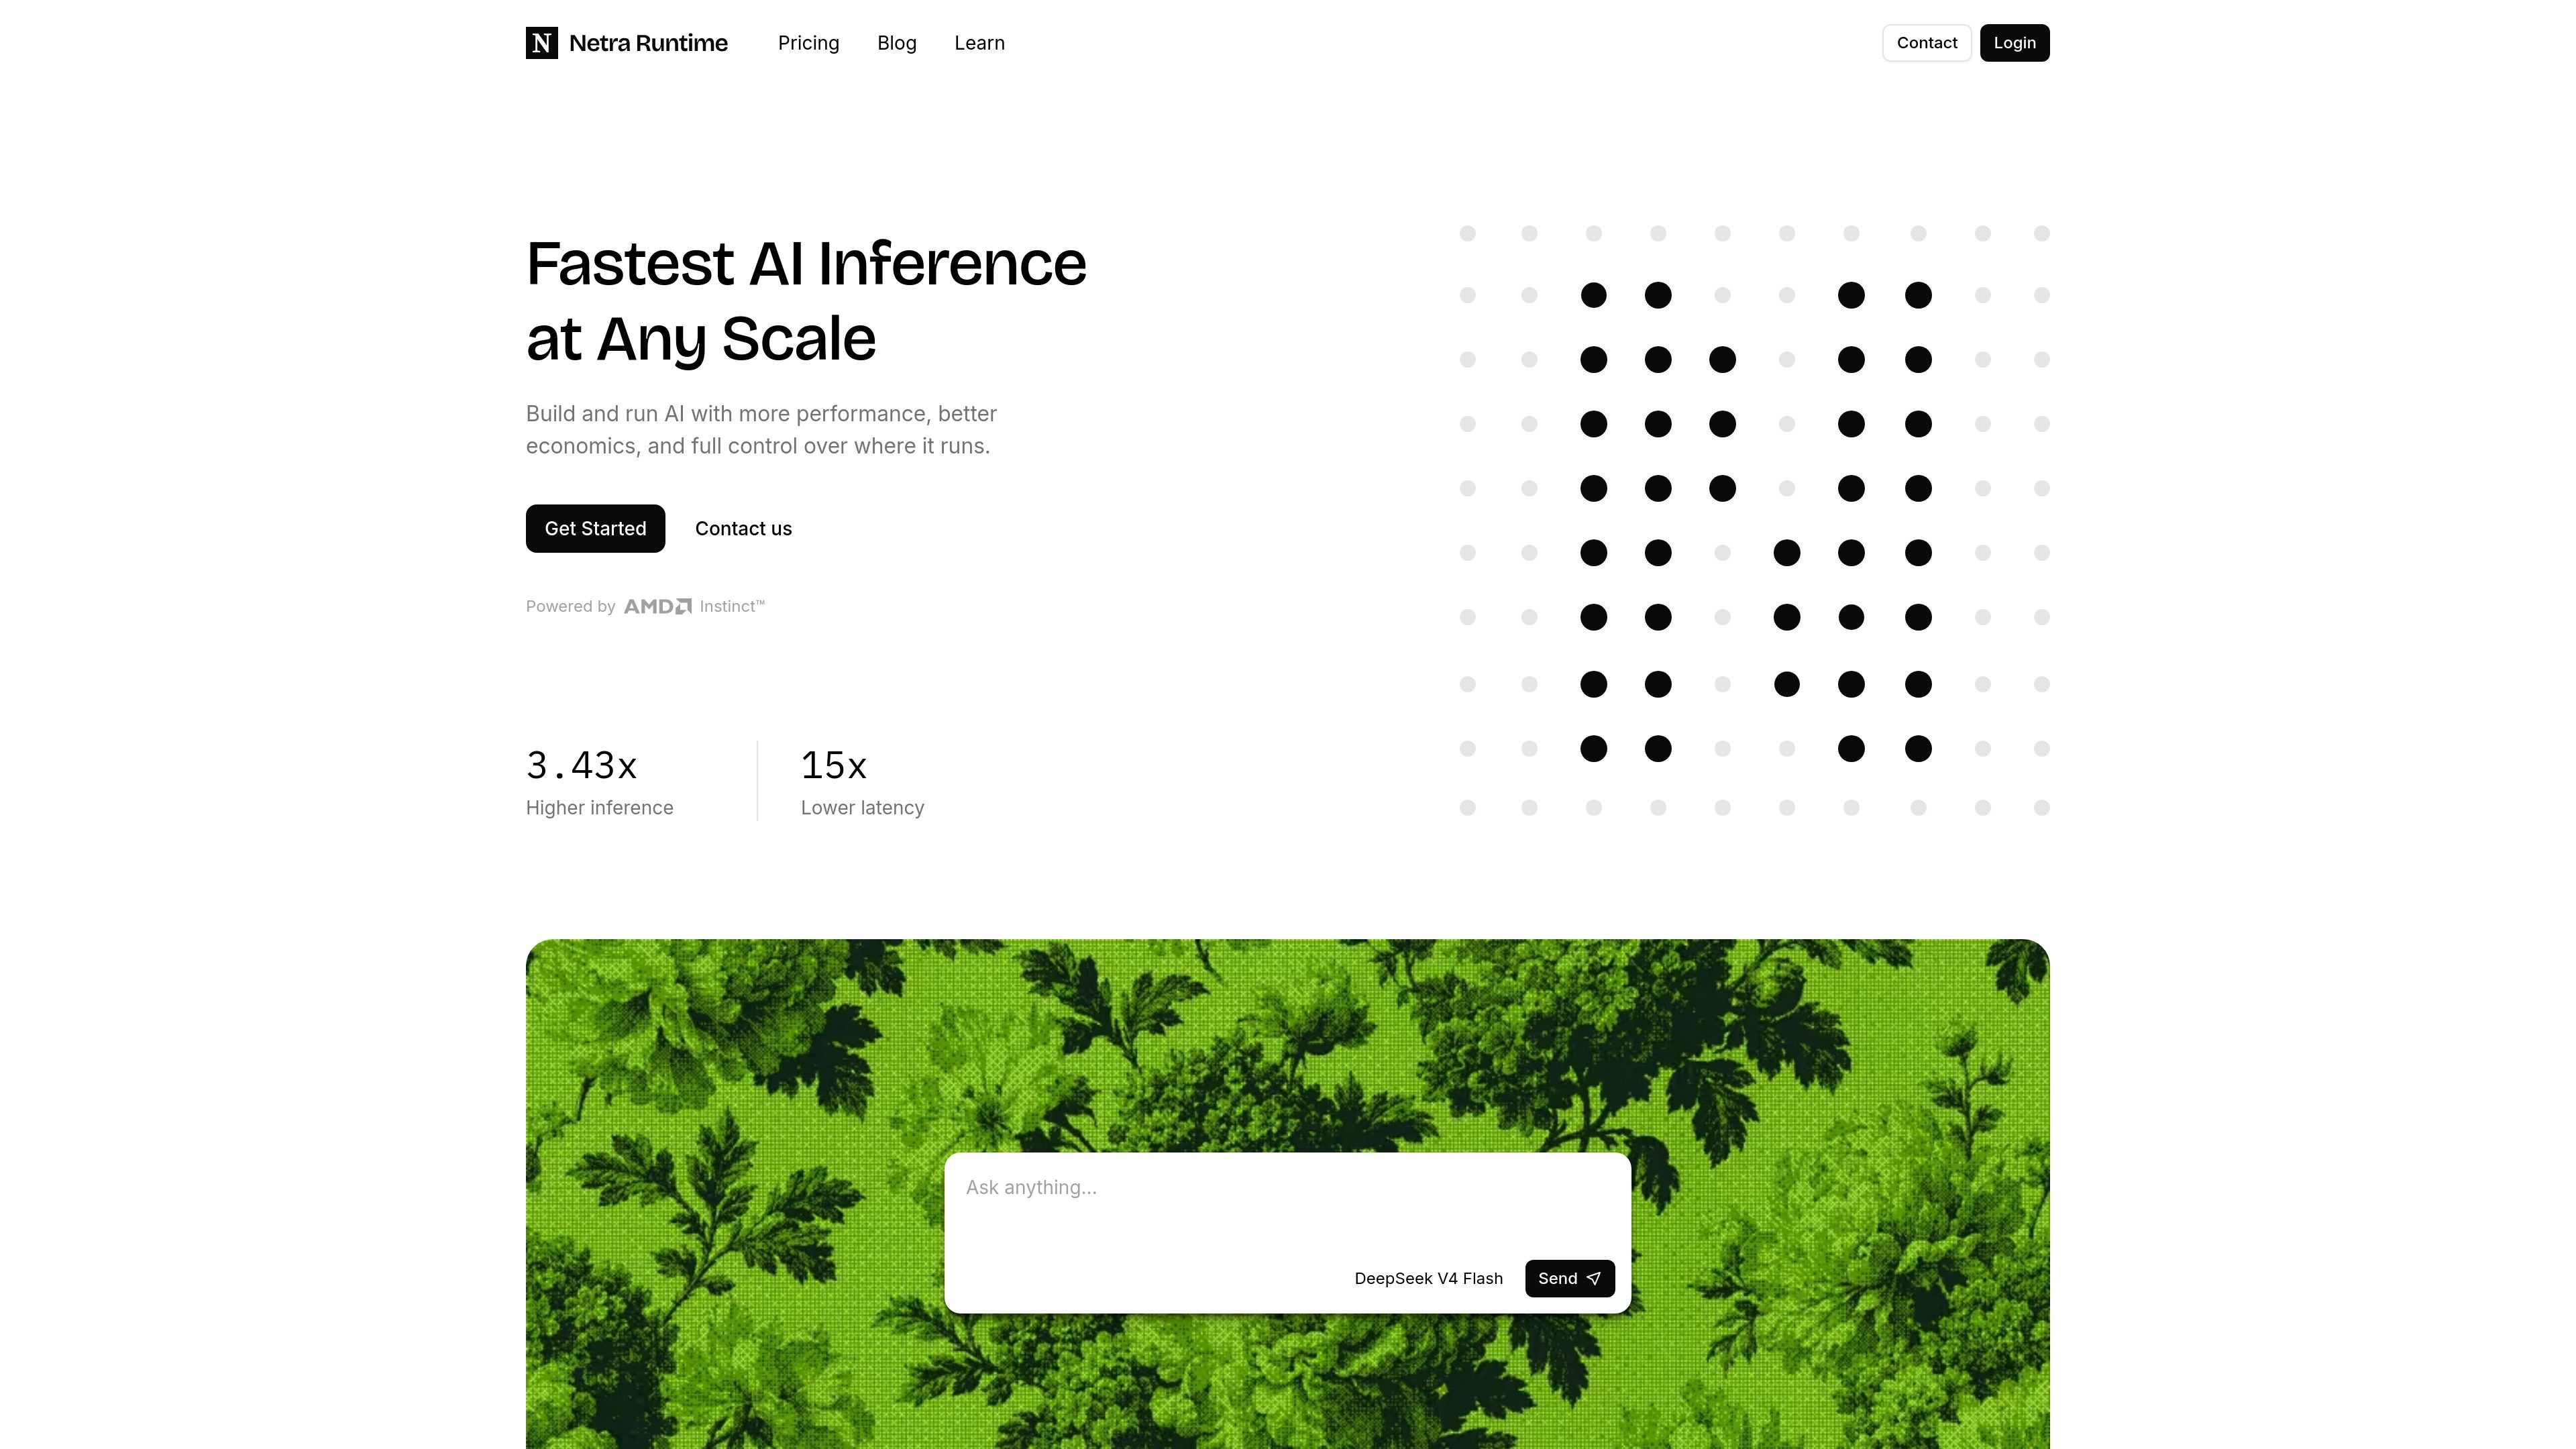
Netra Runtime is a high-performance AI inference engine for teams running models in production. It sits between an AI application and GPU infrastructure, optimizing model execution to target lower latency, higher throughput, and more consistent performance at scale.
The product is available in two deployment models: Netra Cloud provides managed GPU inference through an OpenAI-compatible API, while private deployment brings Netra Runtime into an organization's own GPU environment. The site also describes support for open-model serving, private fine-tuning workflows, monitoring, and enterprise deployments supported by Forward Deployed Engineers.
Use managed GPUs and production inference APIs through Netra Cloud, without operating the underlying GPU infrastructure.
Deploy the inference runtime directly on private GPU infrastructure so models and data remain within the organization's environment.
The platform is built to improve inference throughput and latency, helping existing GPUs process more AI workloads and potentially reducing infrastructure cost per token.
Track latency, throughput, reliability, and usage as inference workloads scale, providing operational visibility into production serving.
Serve open models on managed GPUs and run models tuned or fine-tuned on private data while keeping datasets and checkpoints private.
The published Netra Kernel repository provides MIT-licensed, target-specific AMDGPU kernels, validation harnesses, runtime bridges, and SGLang serving integration for supported contracts.
Teams can call open models through Netra Cloud's OpenAI-compatible API and start serving through managed GPUs without building their own GPU operations layer.
Organizations with existing AMD or NVIDIA capacity can deploy Netra Runtime alongside their infrastructure to improve serving performance while retaining control of models and data.
Model teams can fine-tune models on private datasets while keeping datasets and checkpoints within their controlled workflow, then serve the resulting models in production.
Engineering and operations teams can monitor latency, throughput, reliability, and usage to evaluate and manage AI workloads as demand increases.
Netra Runtime is a high-performance inference engine that sits between an AI application and GPU infrastructure. It optimizes model execution for production serving, with a focus on throughput, latency, and GPU utilization.
Yes. Netra Cloud provides managed inference through an OpenAI-compatible API, so teams can use Netra's inference service without operating their own GPUs.
Yes. Netra Runtime can be deployed on an organization's own GPU infrastructure, keeping models and data within that environment. Enterprise or private deployment support includes assistance from Forward Deployed Engineers.
Netra is designed for AMD and NVIDIA GPU infrastructure. Published benchmarks include AMD Instinct MI350X and NVIDIA H200, but support for a specific GPU and model configuration should be confirmed with Netra.
Netra Cloud uses prepaid credits. The pricing page provides model input and output usage costs so teams can estimate spending before adding credits; payments are processed through Doku.
AakarDev AI helps teams manage AI provider access, project-level setups, logs, and analytics from one dashboard. It supports BYOK workflows and lists providers including OpenAI, Google Gemini, Anthropic, Groq, Mistral AI, and Perplexity AI.
ByteAsk is a terminal-first AI coding agent for C and C++ that edits repositories and verifies changes with the real compiler, debugger, sanitizers, and tests before showing a diff. It offers a free tier plus paid plans, with editor connectors and zero-retention handling described in the source.

CreateOS Sandbox is an isolated compute environment for running code and agent workloads inside Firecracker micro-VMs. It is designed for workflows that need machine-level isolation, private networking between sandboxes, and programmatic control through SDK, CLI, or MCP.

GitBot is a local browser-based workspace for creating reusable coding bots powered by Claude Code, Codex, or OpenCode. It helps developers run those agents across repository folders with persistent threads and configurable permissions.

hob is an independent workspace for coding agents that keeps agent sessions, terminals, history, and follow-up work organized around the tools and providers you already use. It is aimed at developers who want local control over routing, history, and workspace structure rather than a bundled model stack.

Ably Chat is a chat API platform for building custom realtime chat applications. It supports room-based messaging, typing indicators, presence, reactions, and message updates, with usage-based pricing options for different deployment stages.