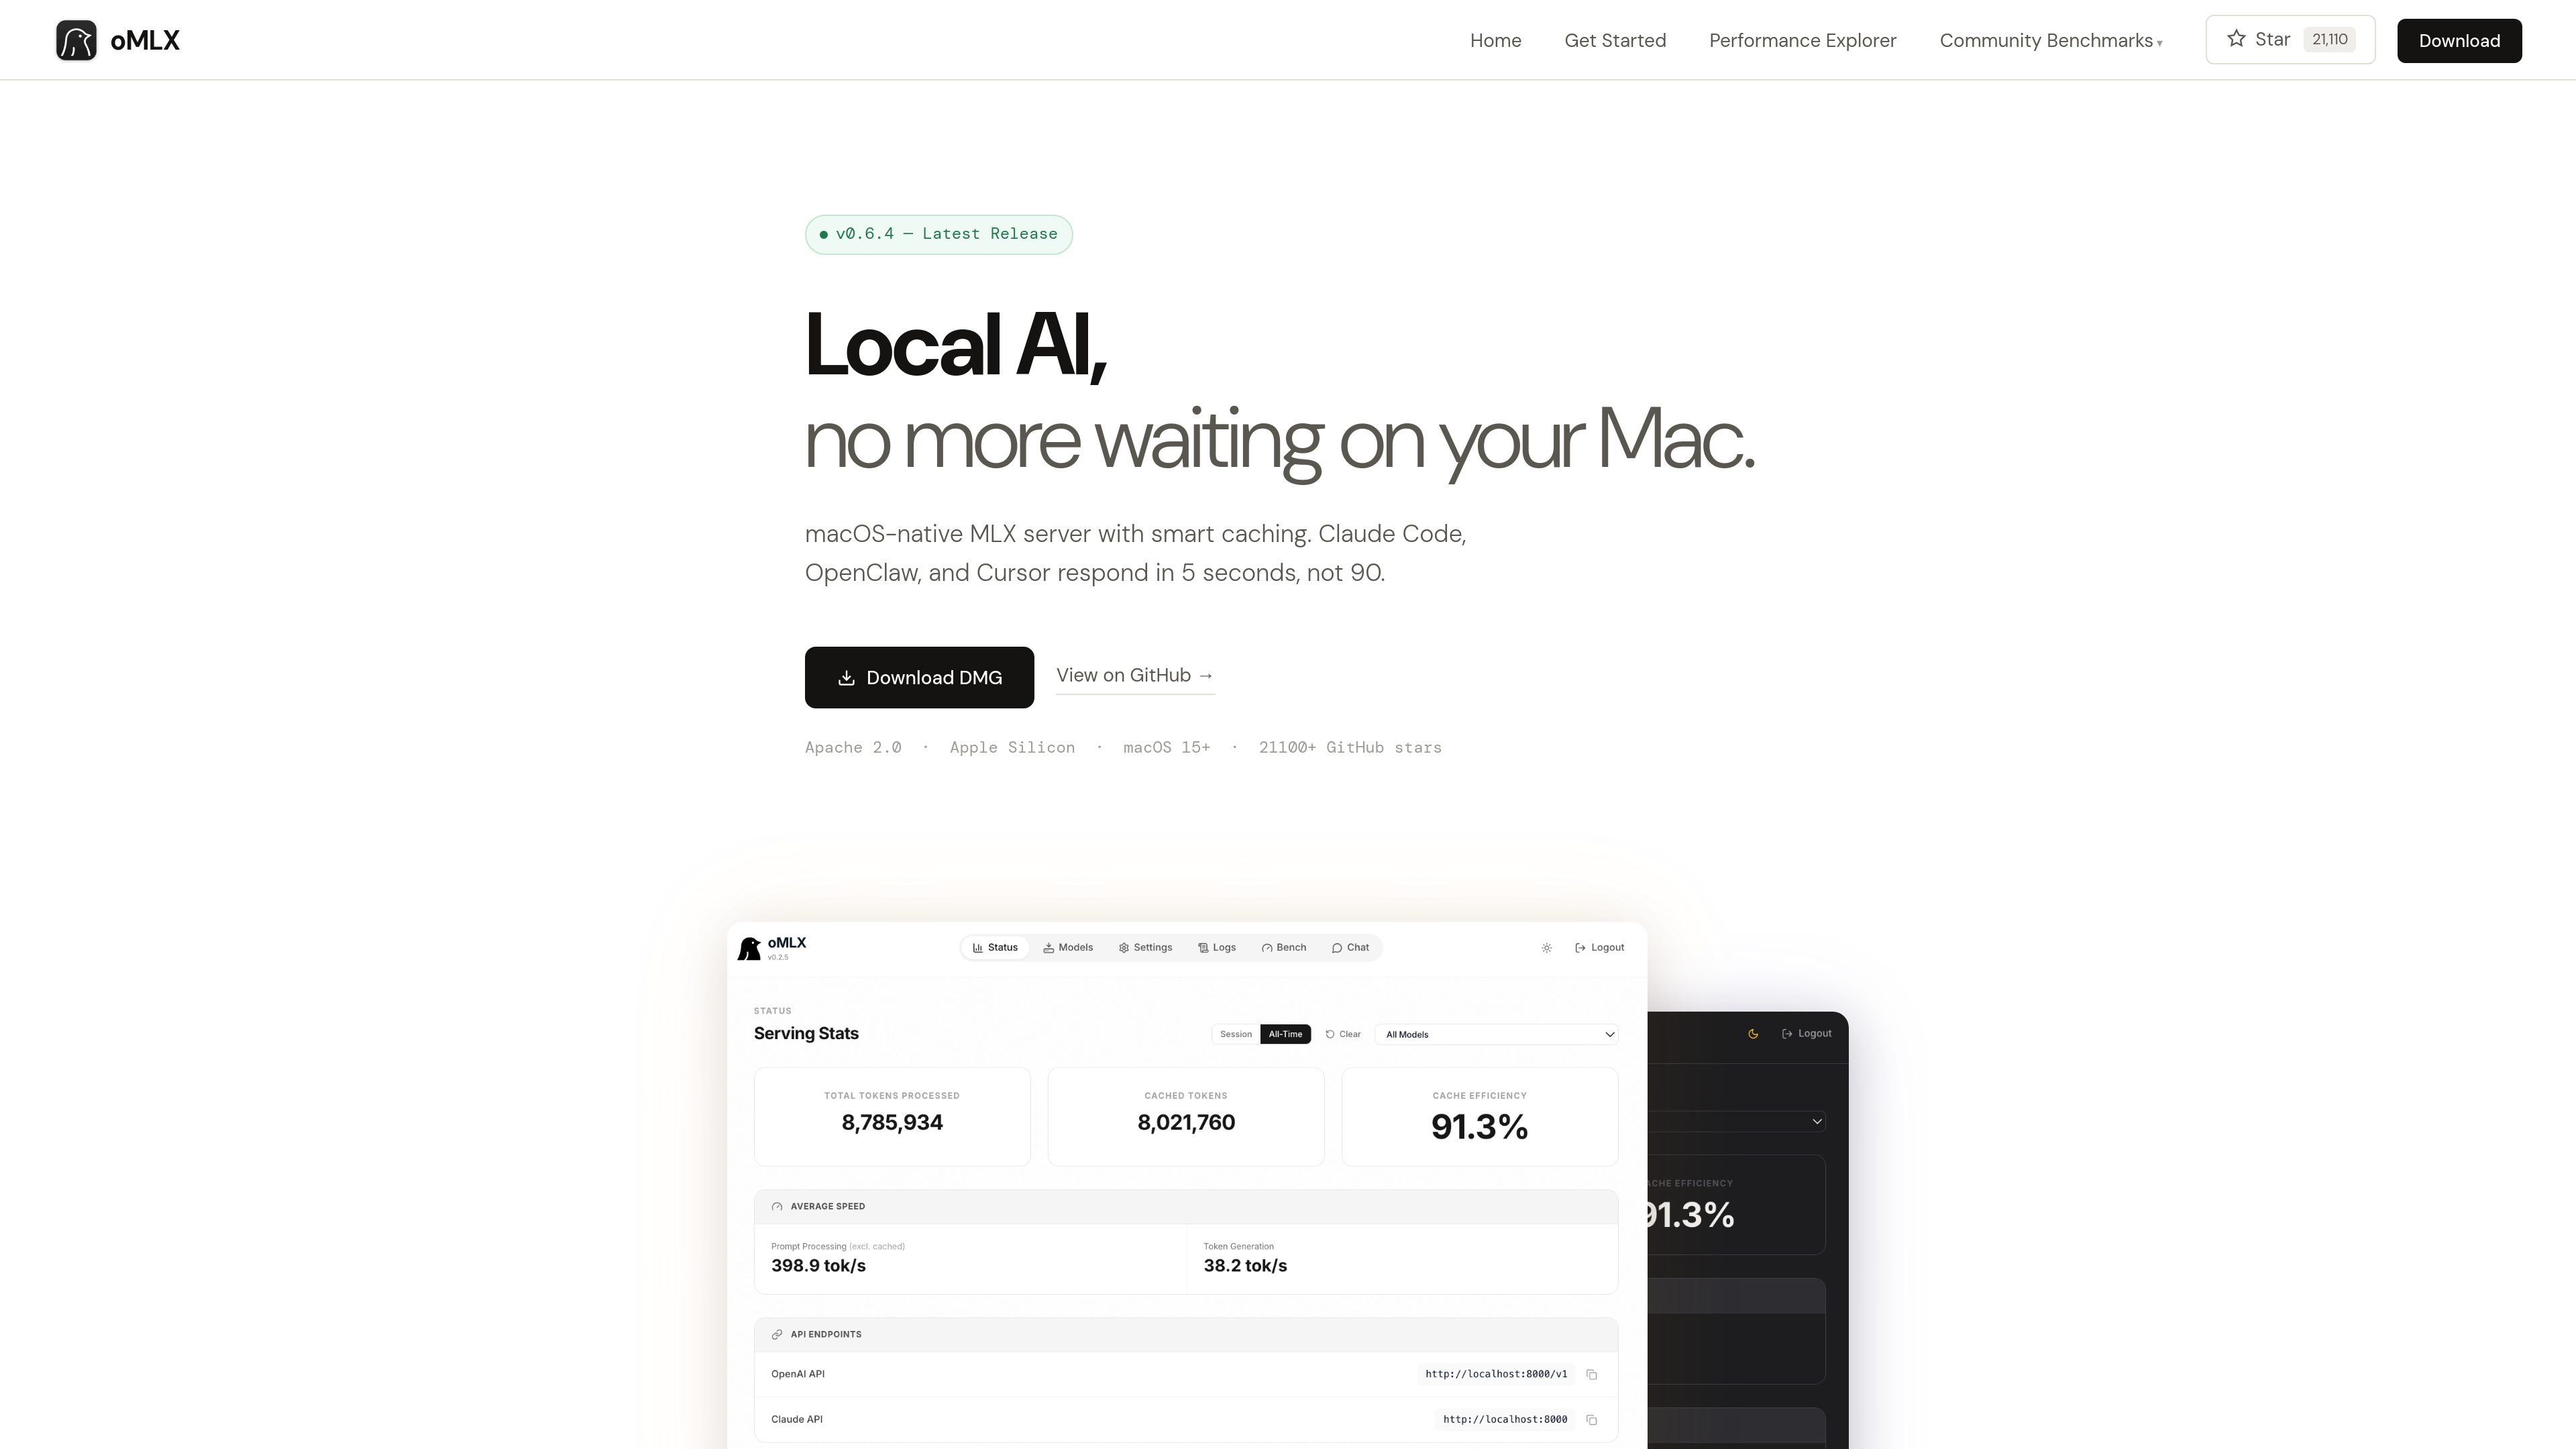
oMLX is a native macOS inference server for local LLM use on Apple Silicon Macs. It is built on MLX and is designed to reduce the repeated recomputation that happens when coding agents invalidate context during a session.
Its main differentiator is paged SSD KV caching, which persists cache blocks to disk so previously used prefixes can be restored quickly across requests and even after server restarts. The product also adds continuous batching, multi-model serving, and OpenAI- and Anthropic-compatible APIs for local tools and clients.