
Loading...

Drama 3 is Fish Audio’s directable text-to-speech model for creators and developers who need control over vocal performance, including emotion, pacing, sounds, pauses, and selected-word effects. It is available in the Fish Audio editor and through the API.

Kugel 3.5 is KugelAudio’s text-to-speech model for voice agents and phone conversations, with controls for short replies, IPA pronunciation, timed pauses and character-by-character codes. It retains Kugel 3’s documented voices, languages, dictionaries and API while charging €0.0525 per audio minute excluding VAT, billed per second.

Onepin is an AI voice production agent that turns scripts into text-to-speech audio through text normalization, pronunciation handling, multi-model routing, validation, and corrective generation. It supports creators and production teams making e-learning, advertising, games, narration, and other scripted audio.

Eleven v4 and Eleven v4 Turbo are expressive AI text-to-speech models for narration, dialogue, multilingual voice content, and real-time voice agents. They help creators and developers control emotion, speaker context, pauses, and audio events, with Turbo optimized for streaming conversations.

Vitra Universe is an AI-powered platform for creating, translating, personalizing, reviewing, and publishing video, image, document, website, and app content. It is designed for teams managing multilingual content workflows across connected design, document, CMS, commerce, developer, video, and social tools.
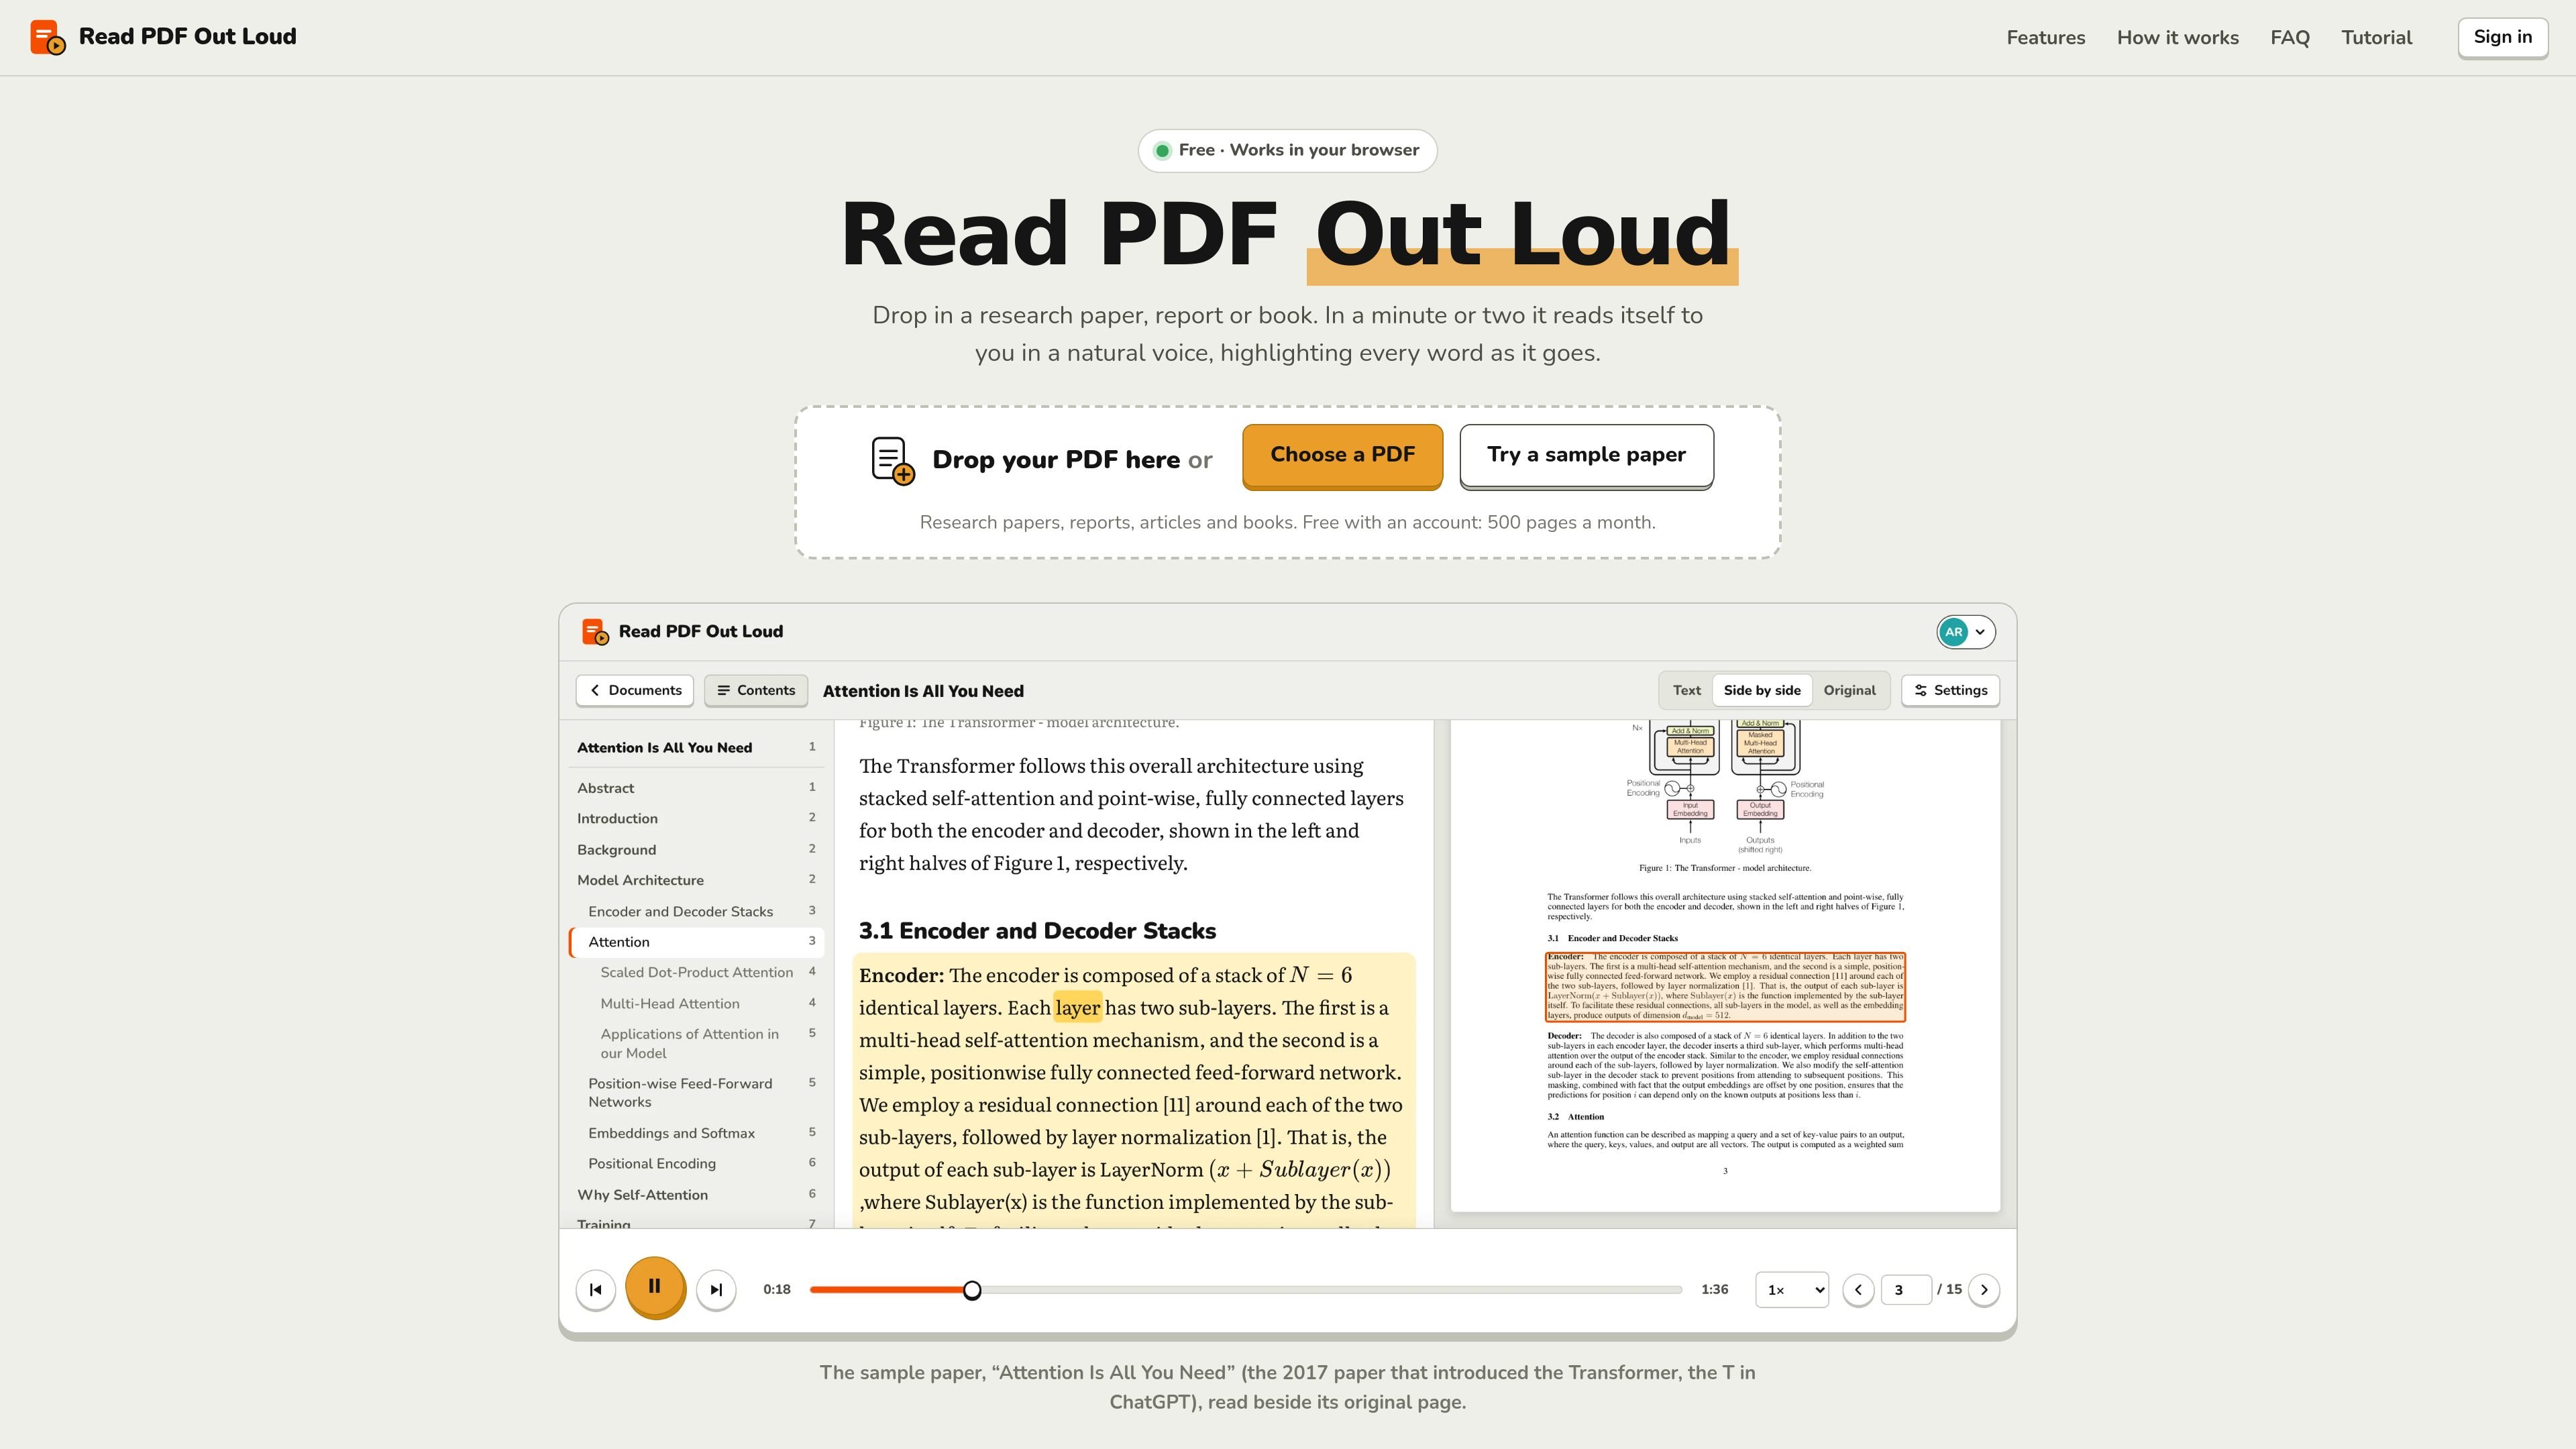

Read PDF Out Loud is a browser-based reader that converts PDFs into natural-sounding spoken audio while highlighting each word. It helps students, researchers, professionals, and people who prefer audio or accessible reading tools work through papers, reports, books, and other documents.

Gemini 3.8 Text-to-Speech is Google’s pair of expressive audio models for turning scripts into customizable spoken audio. Creators, developers and enterprises can design voices, direct delivery line by line, and generate dialogue for content, dubbing and voice-agent applications.

Speechka is an AI voice translation app that converts live speech into another language while preserving the speaker’s personal voice. It is designed for multilingual meetings, calls, presentations, conferences, and livestreams.
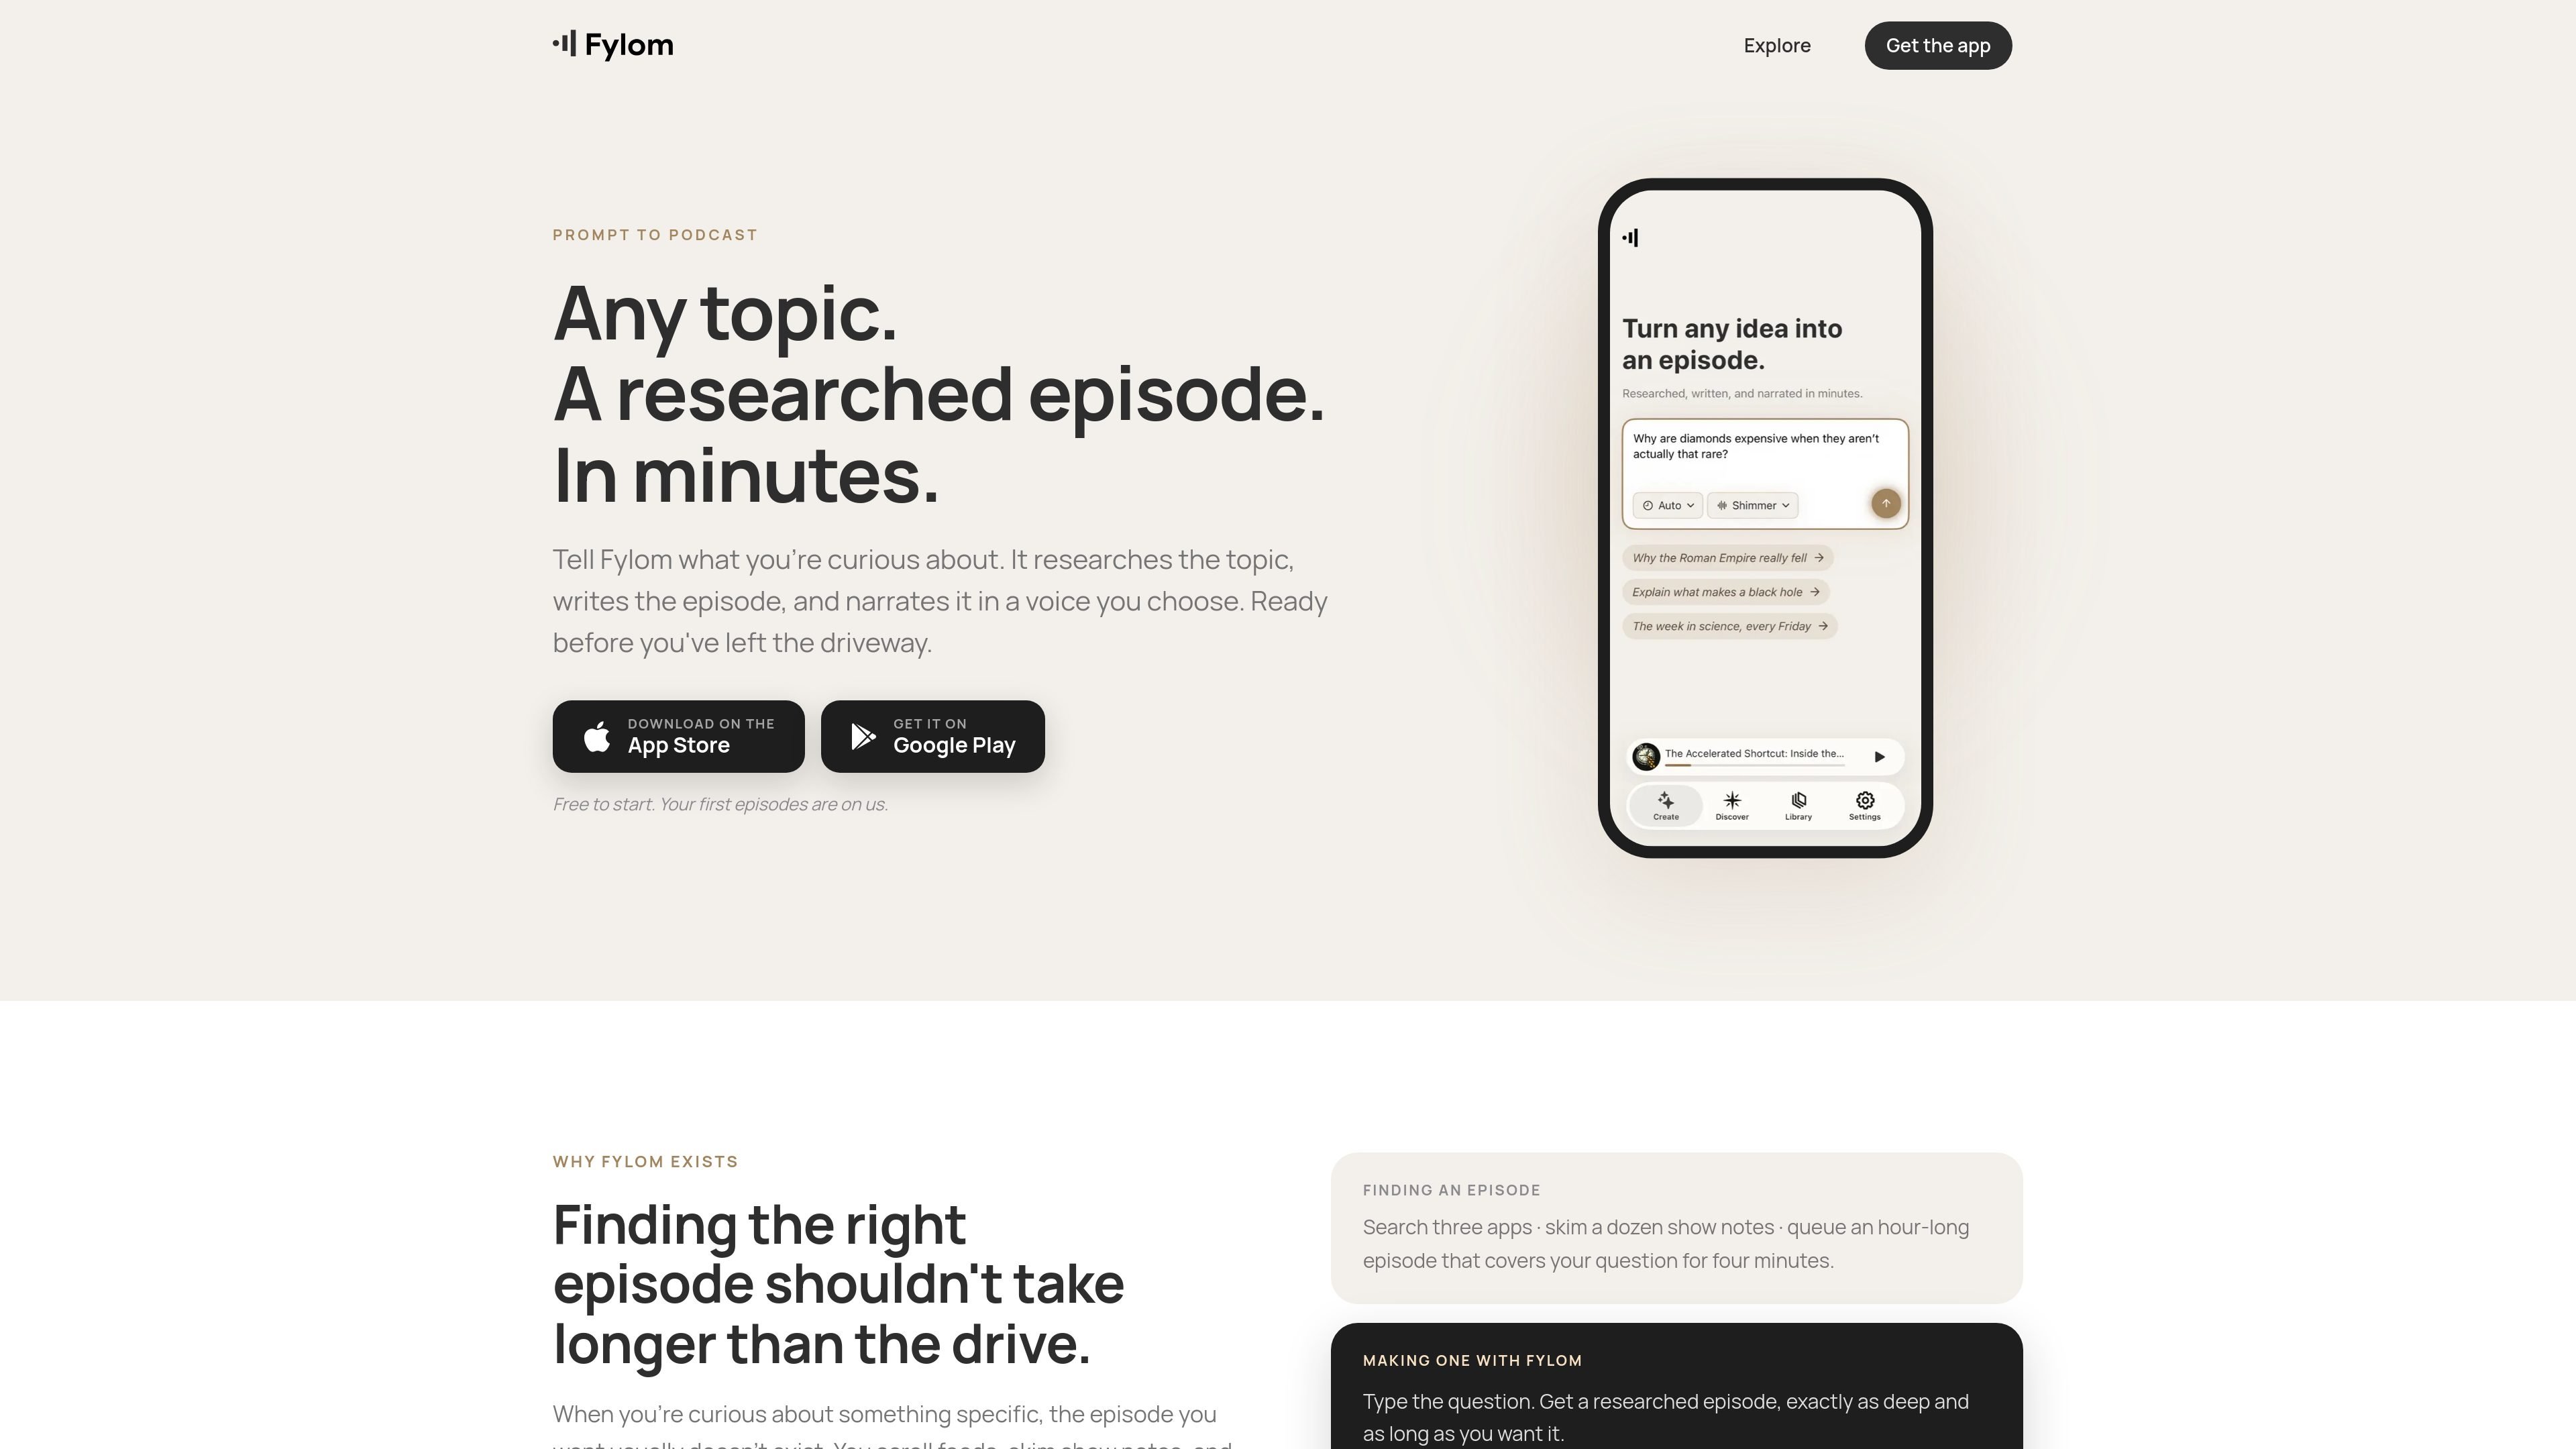
Fylom is an AI podcast generator that turns a topic or question into a researched narrated episode. It supports typed or spoken prompts, voice selection, and recurring show-style listening.
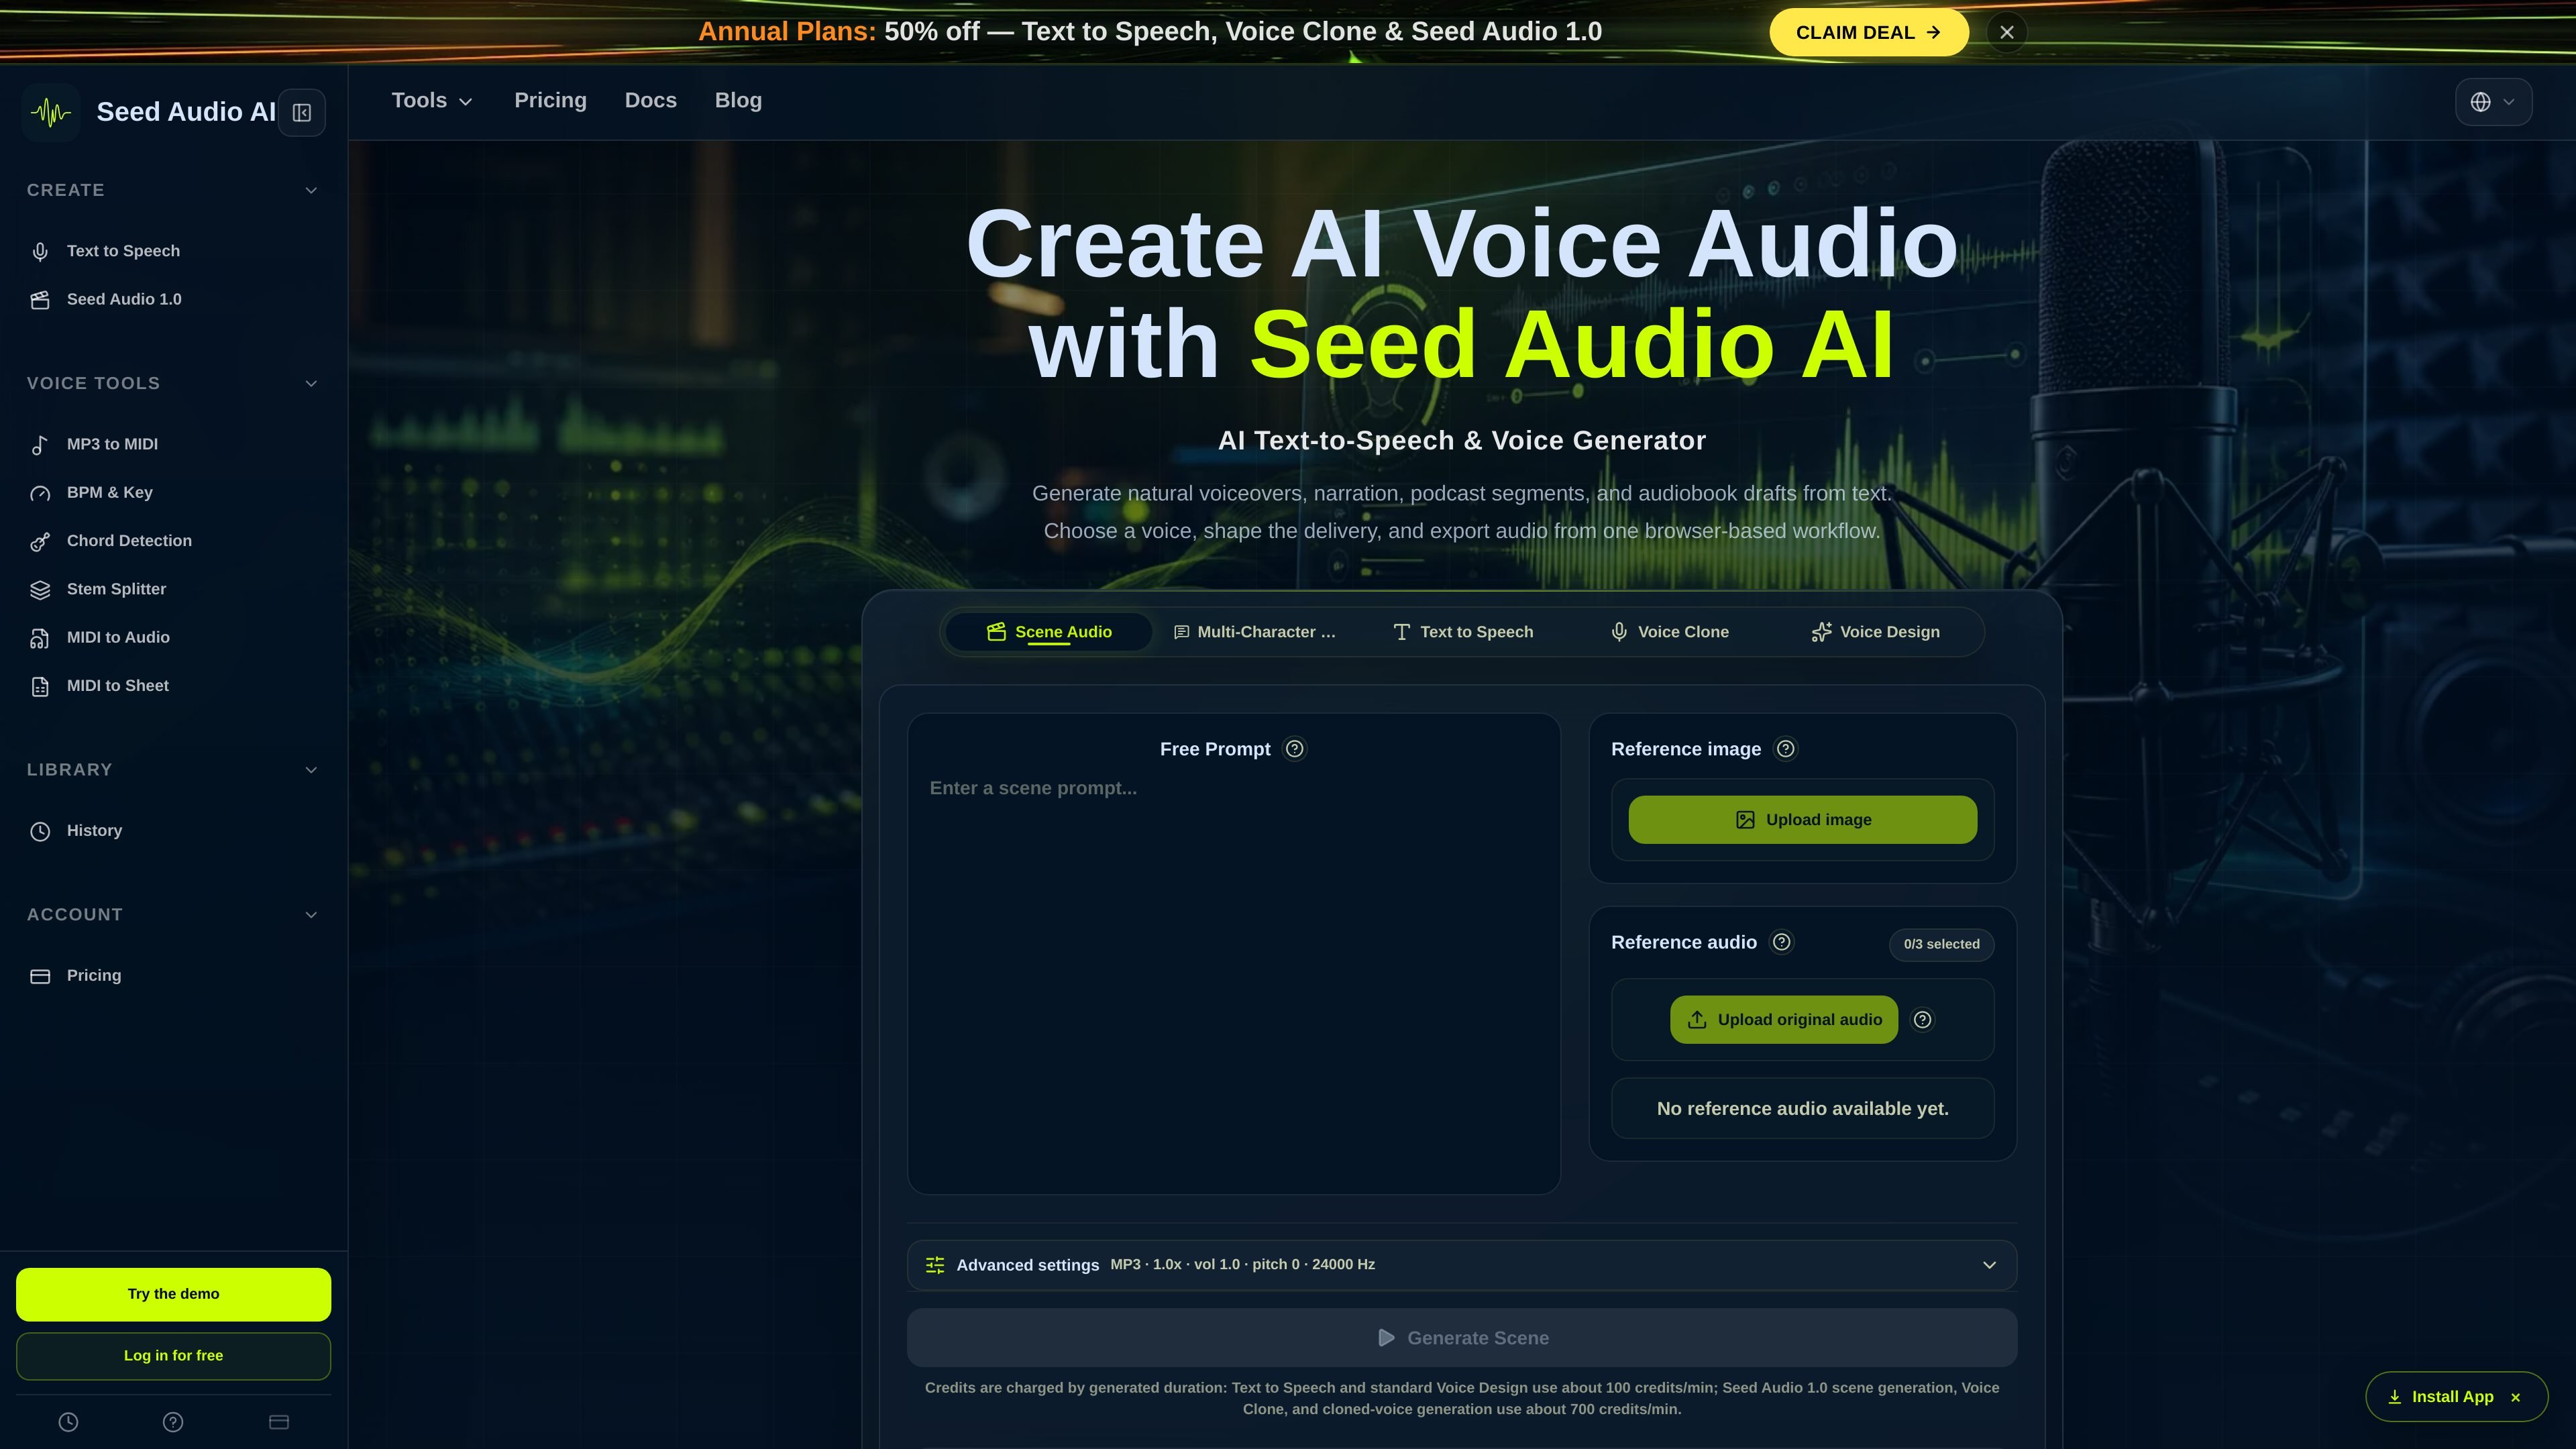

Seed Audio AI is a browser-based text-to-speech and voice cloning tool for turning scripts into reviewable voice audio. It is aimed at creators and teams that need drafts for voiceovers, narration, podcasts, lessons, and ads.
Vois is a local AI voice generator studio for Mac and Windows that handles speech generation, editing, mastering, and export on your own machine. It includes voice cloning, platform export presets, and paid plans with unlimited generation.
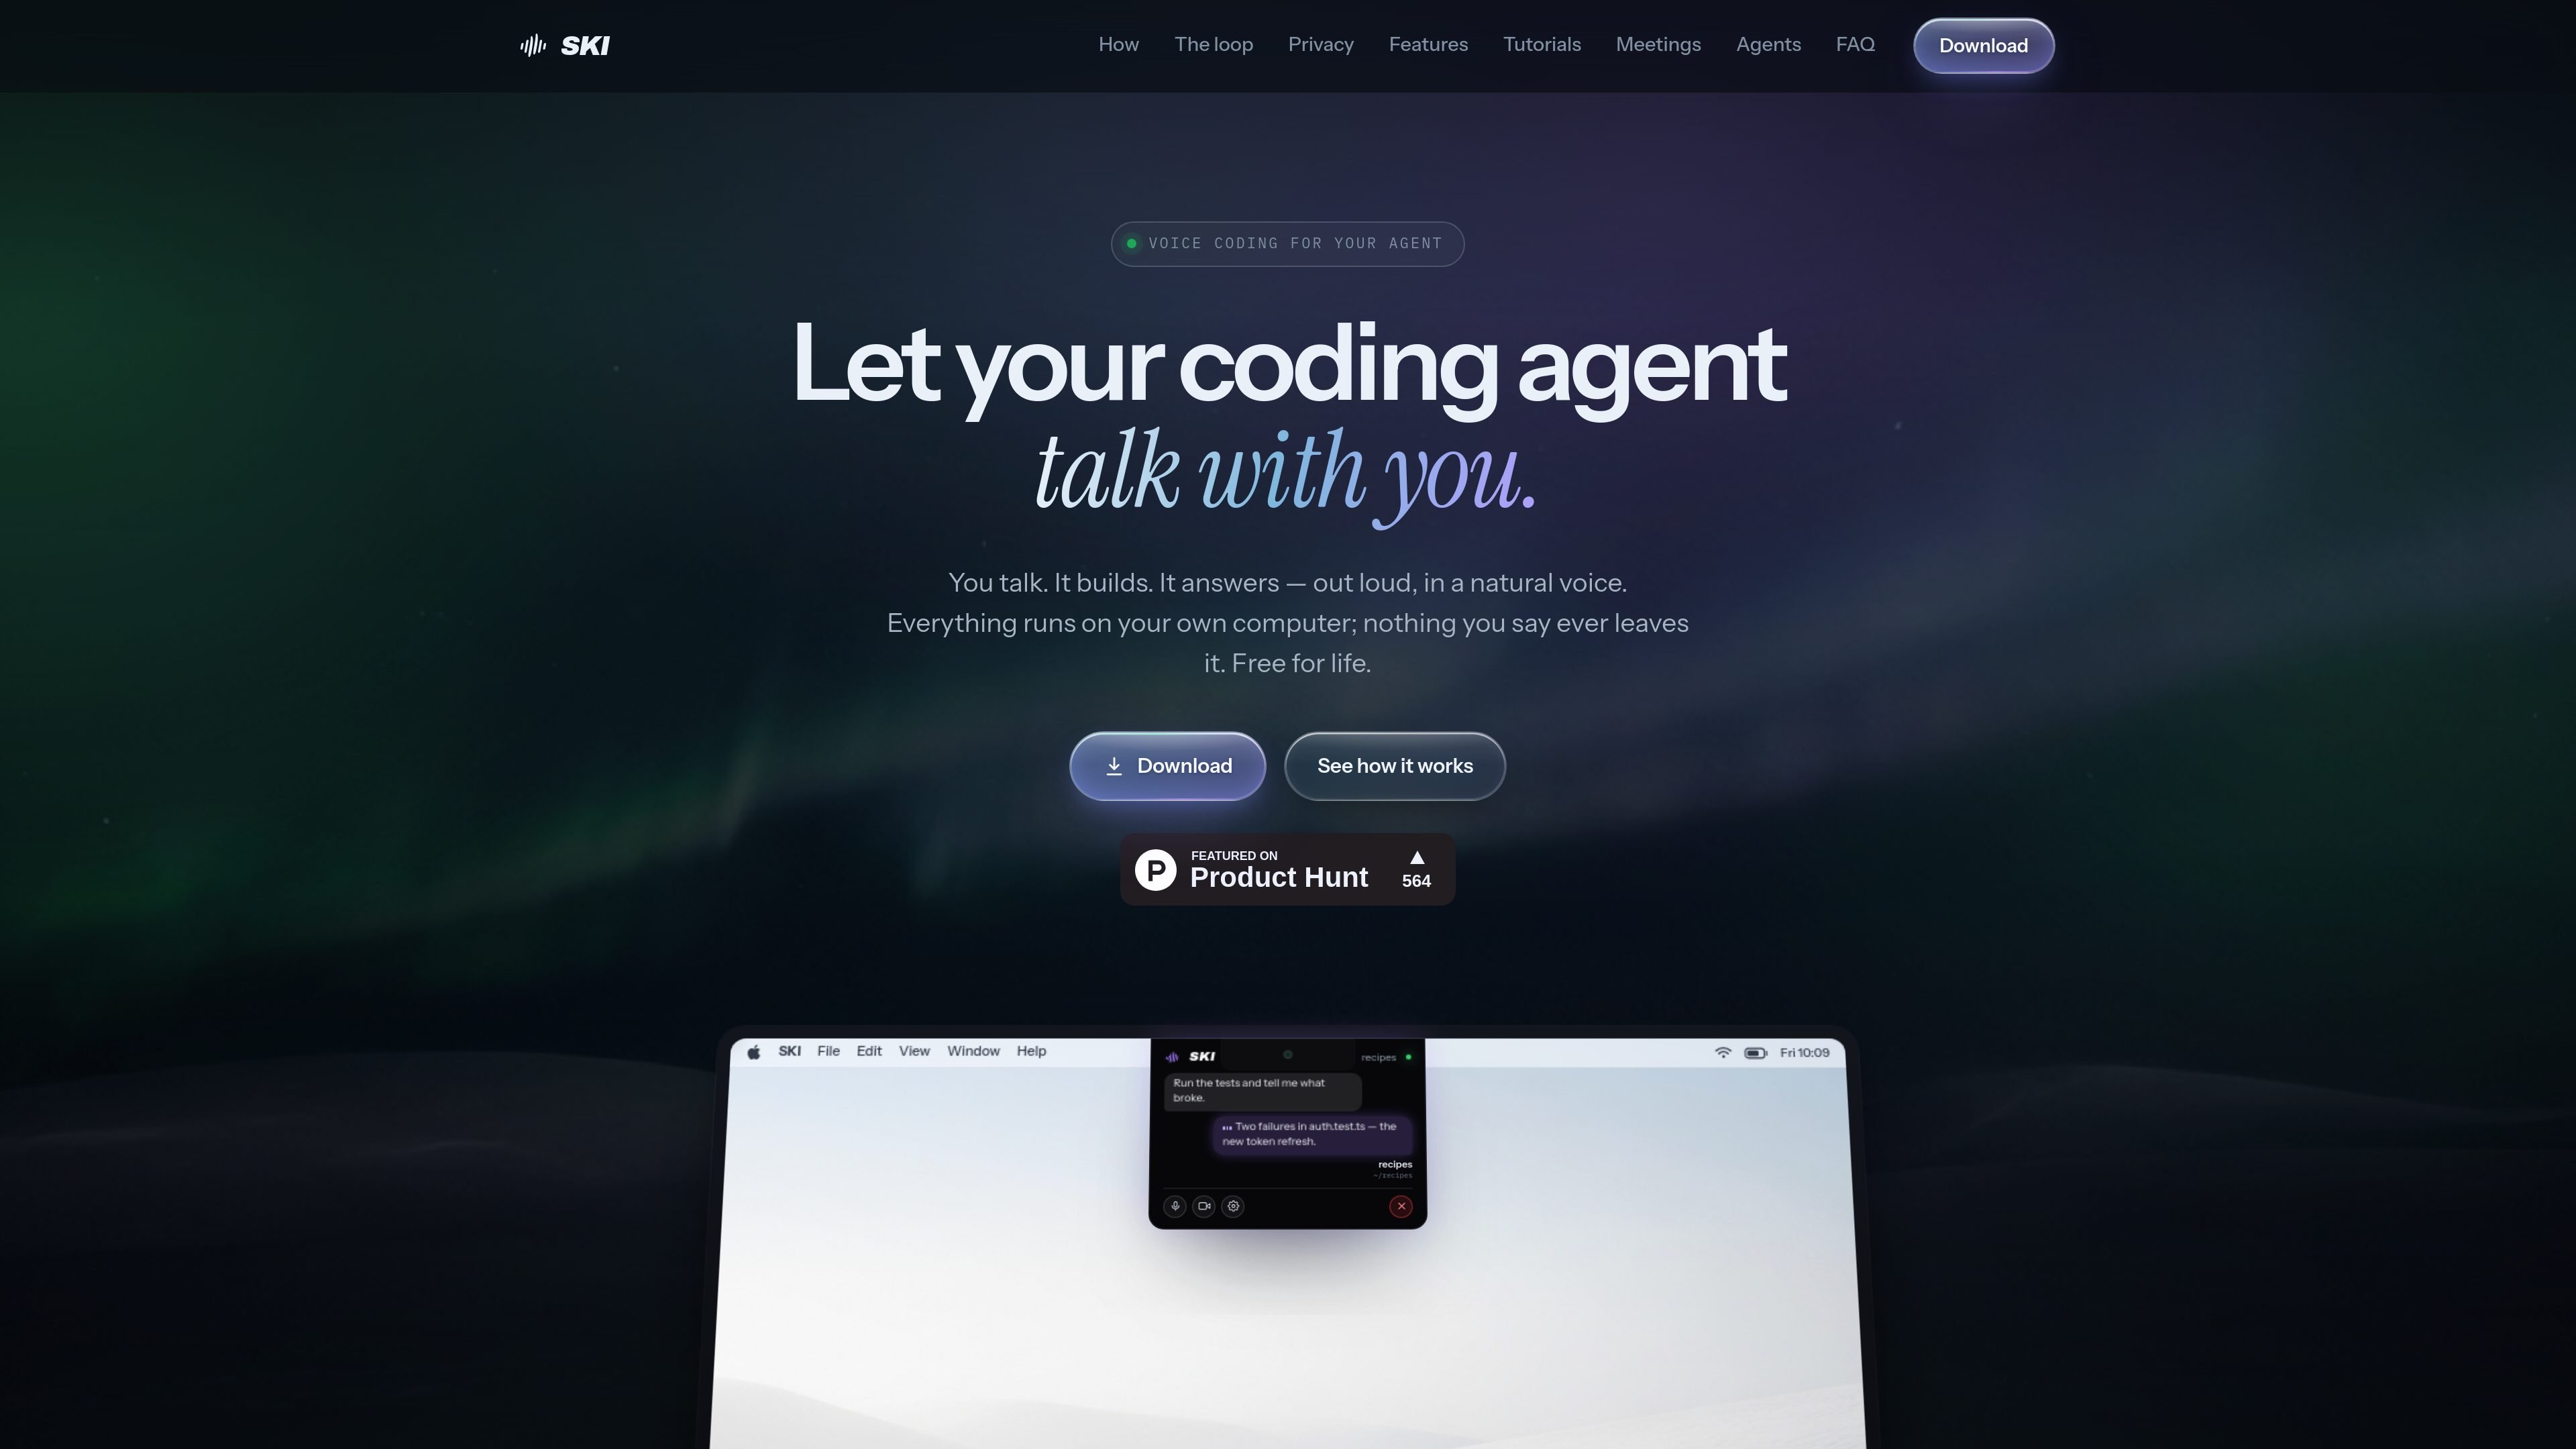
SKI is a desktop app for Mac and Windows that lets developers talk to AI coding agents and hear responses aloud. It keeps the main voice loop local and offline, with optional meeting transcription and agent-assisted call features.
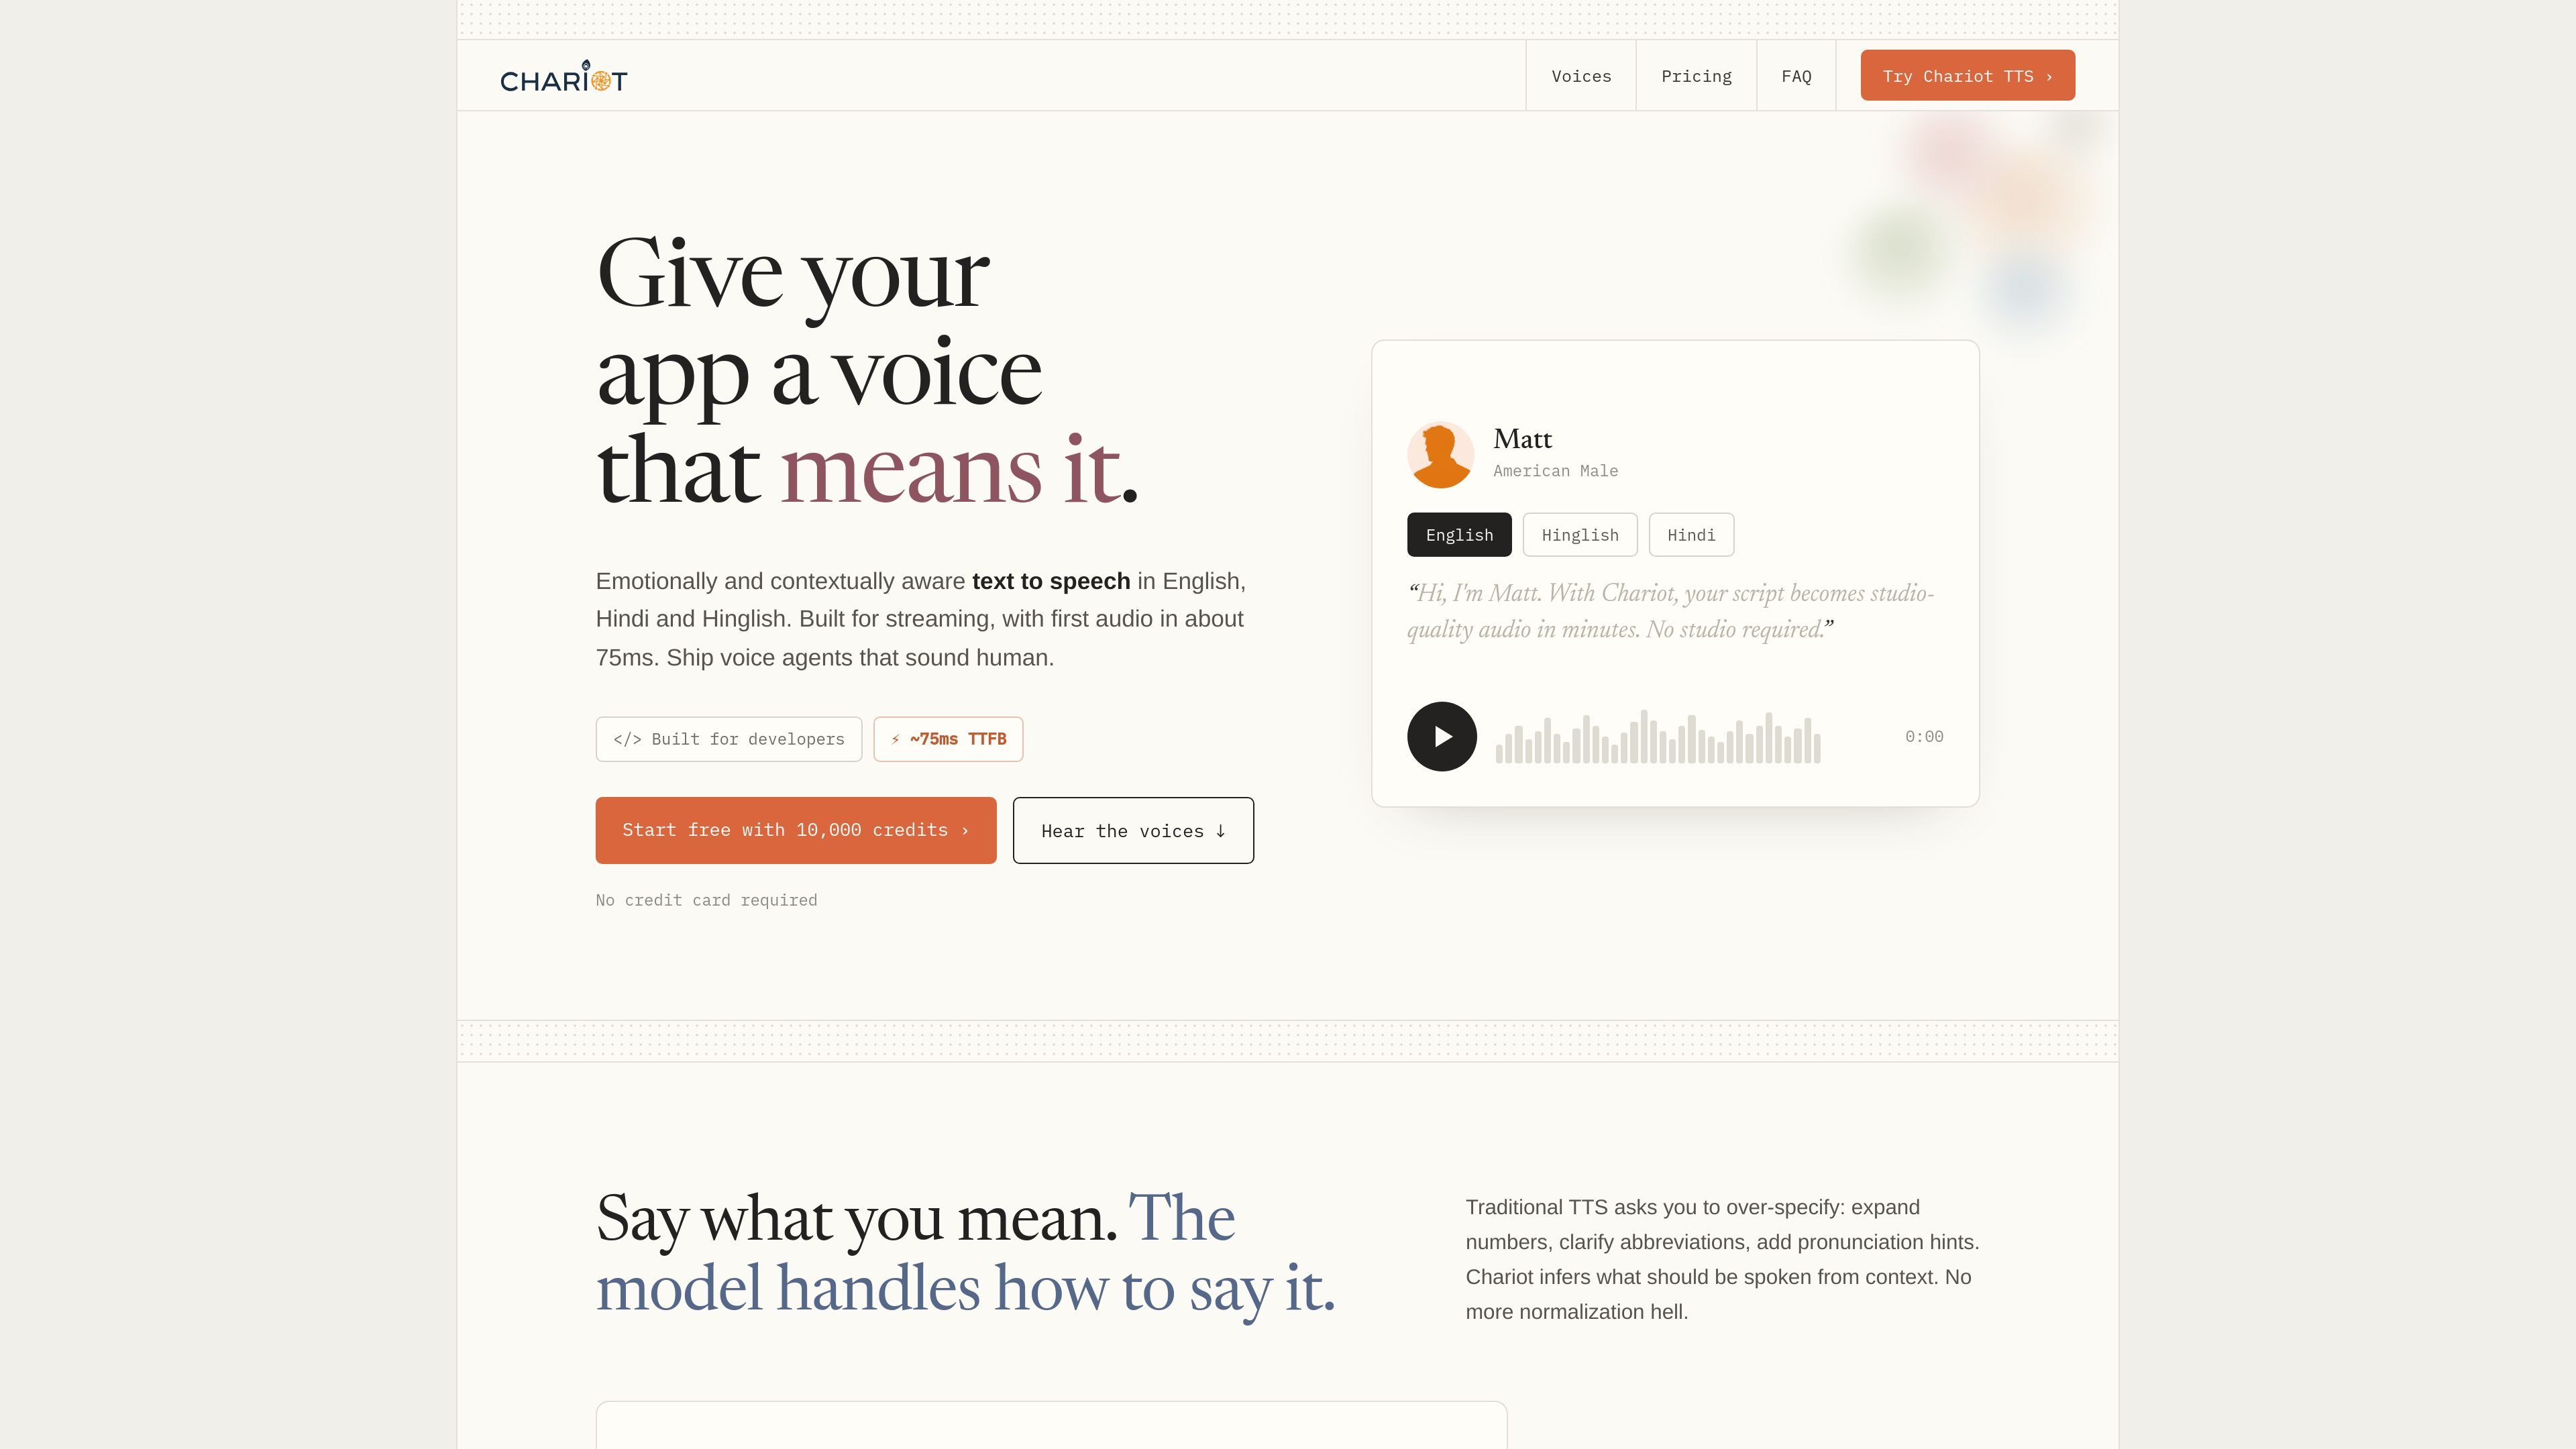

Chariot is an AI text-to-speech product for generating English, Hindi, and Hinglish speech from text, with low-latency streaming and API access for developers. It is aimed at voice agents, app audio, and other production workflows that need natural-sounding speech.
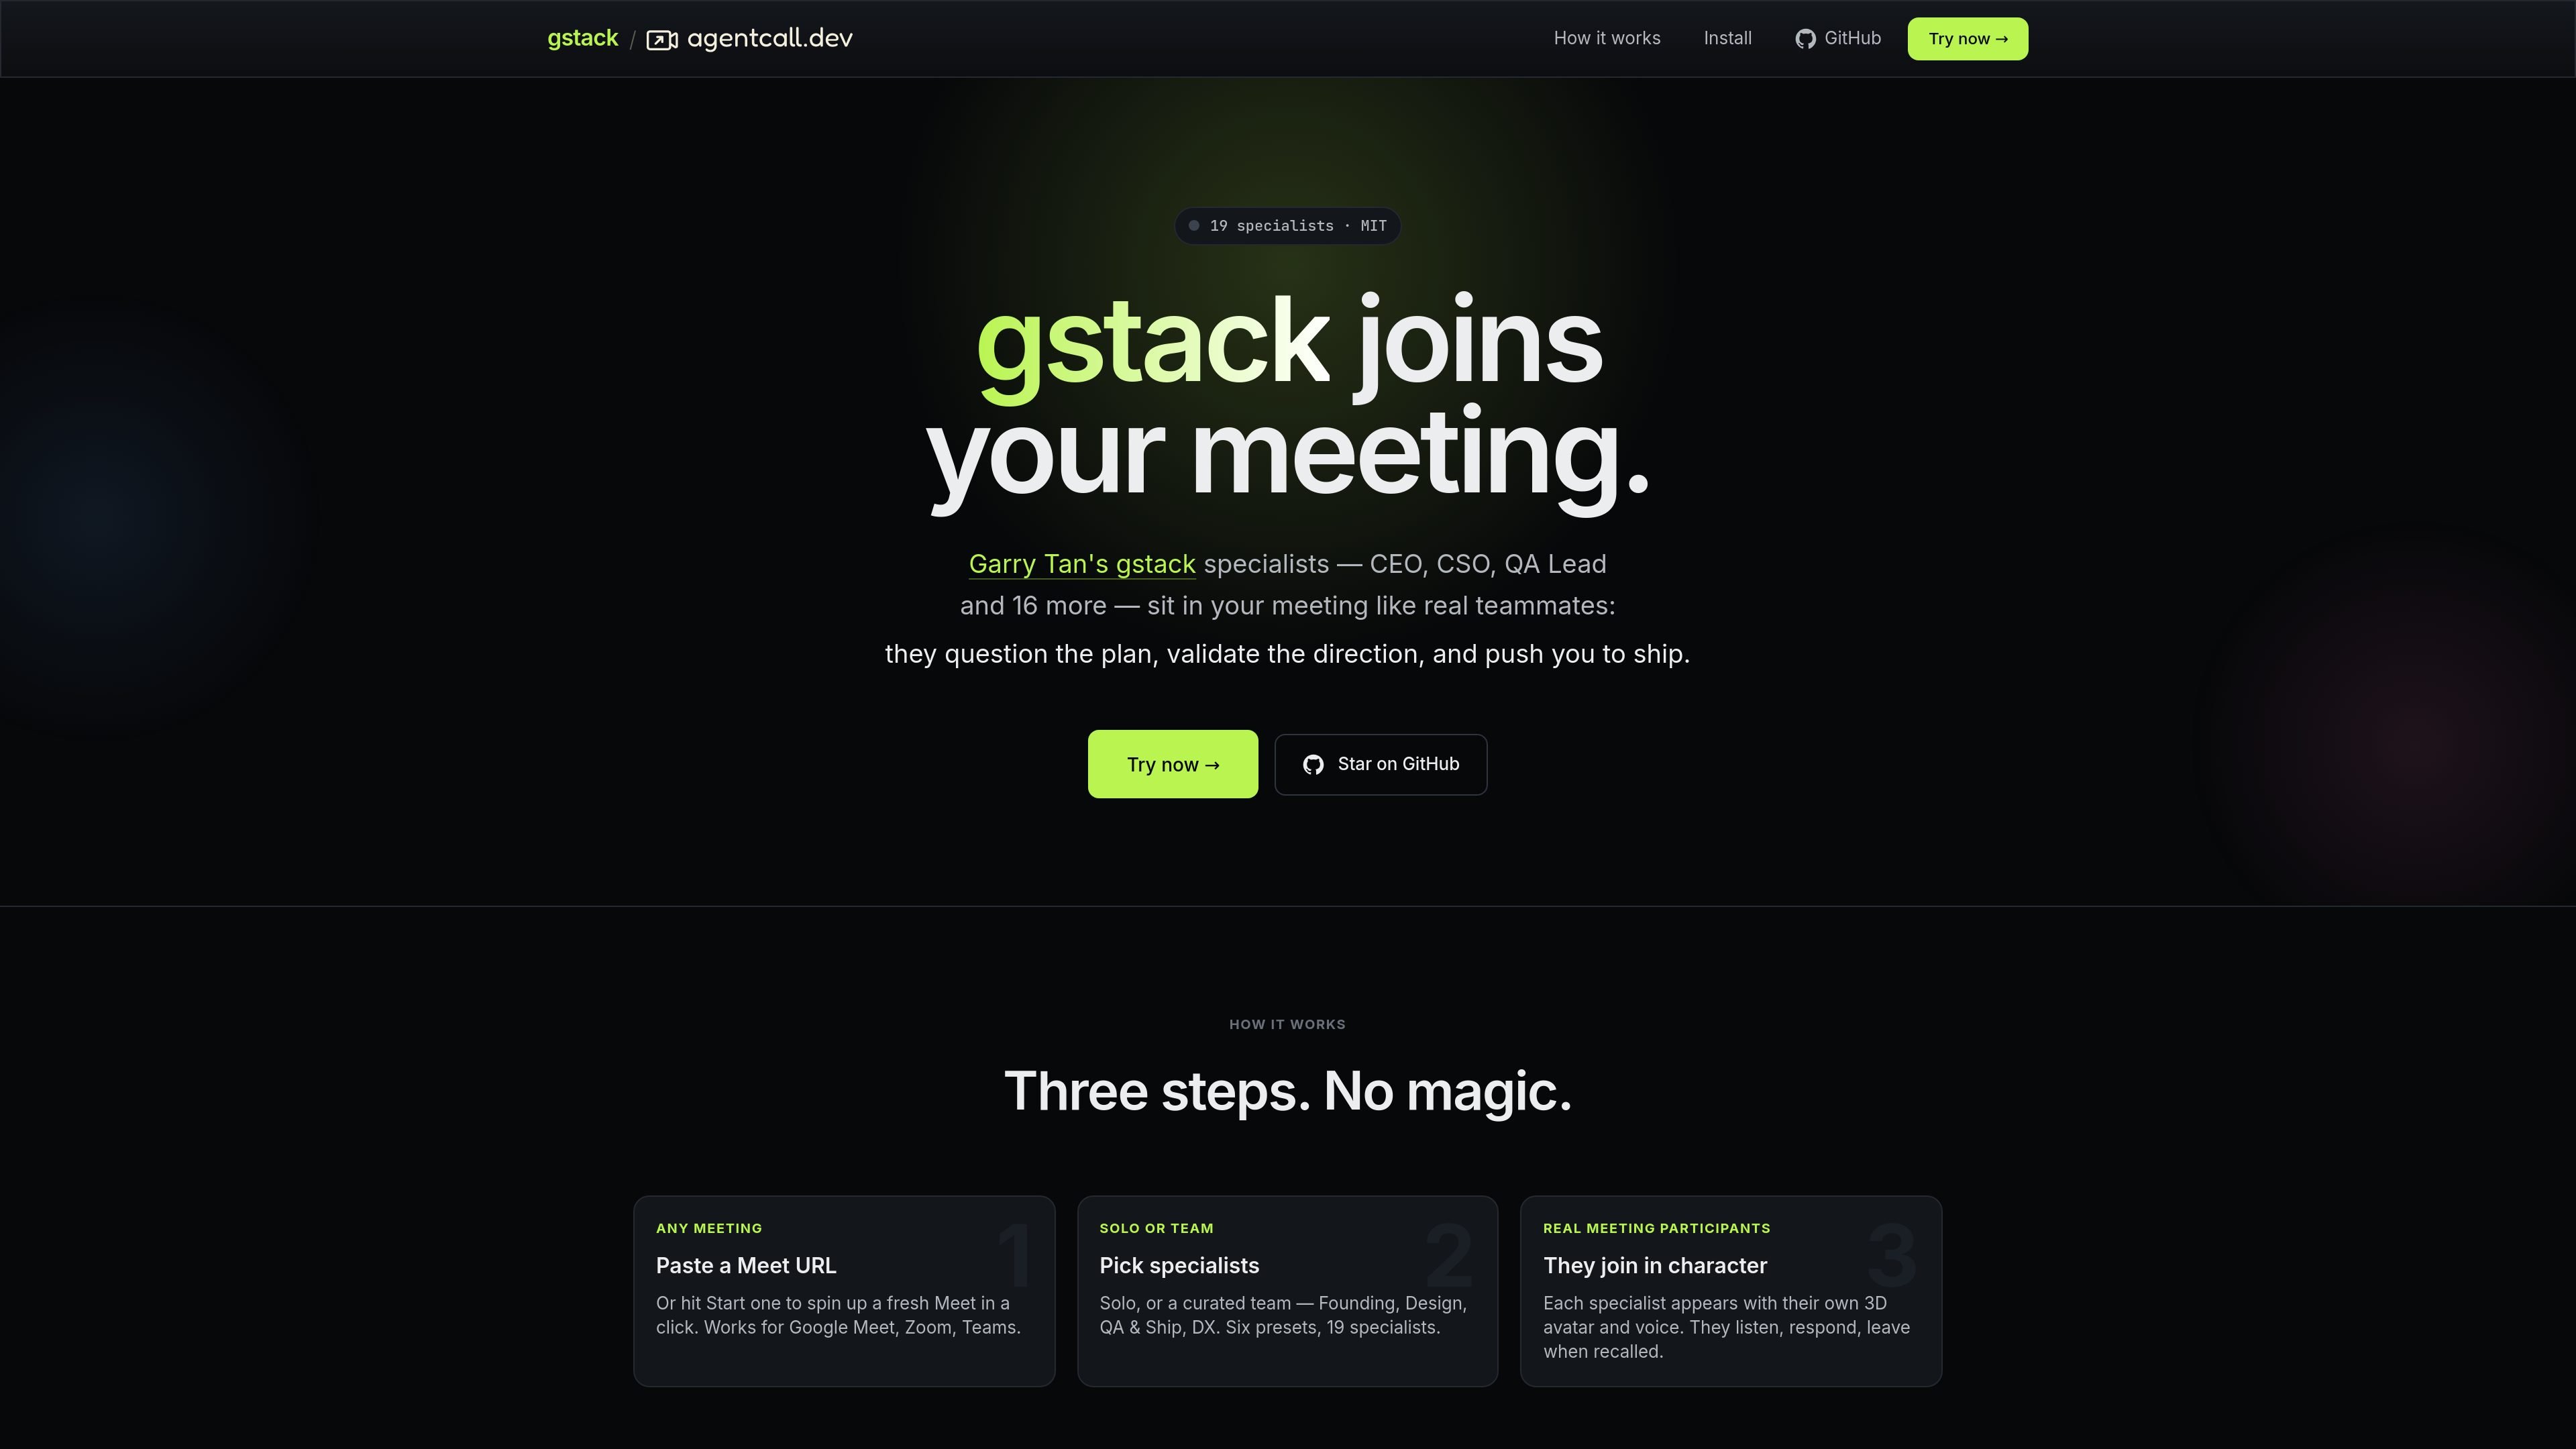

gstack adds Garry Tan’s open-source specialist personas to live meetings as voice bots. It supports Google Meet, with support also mentioned for Zoom and Teams, and runs through a bring-your-own-brain workflow using a local coding-agent session.
PodcastorAI is an AI podcast studio that turns content into podcast scripts, audio episodes, and video podcasts. It helps creators produce publish-ready shows from topics, documents, URLs, notes, or recordings without a traditional studio setup.
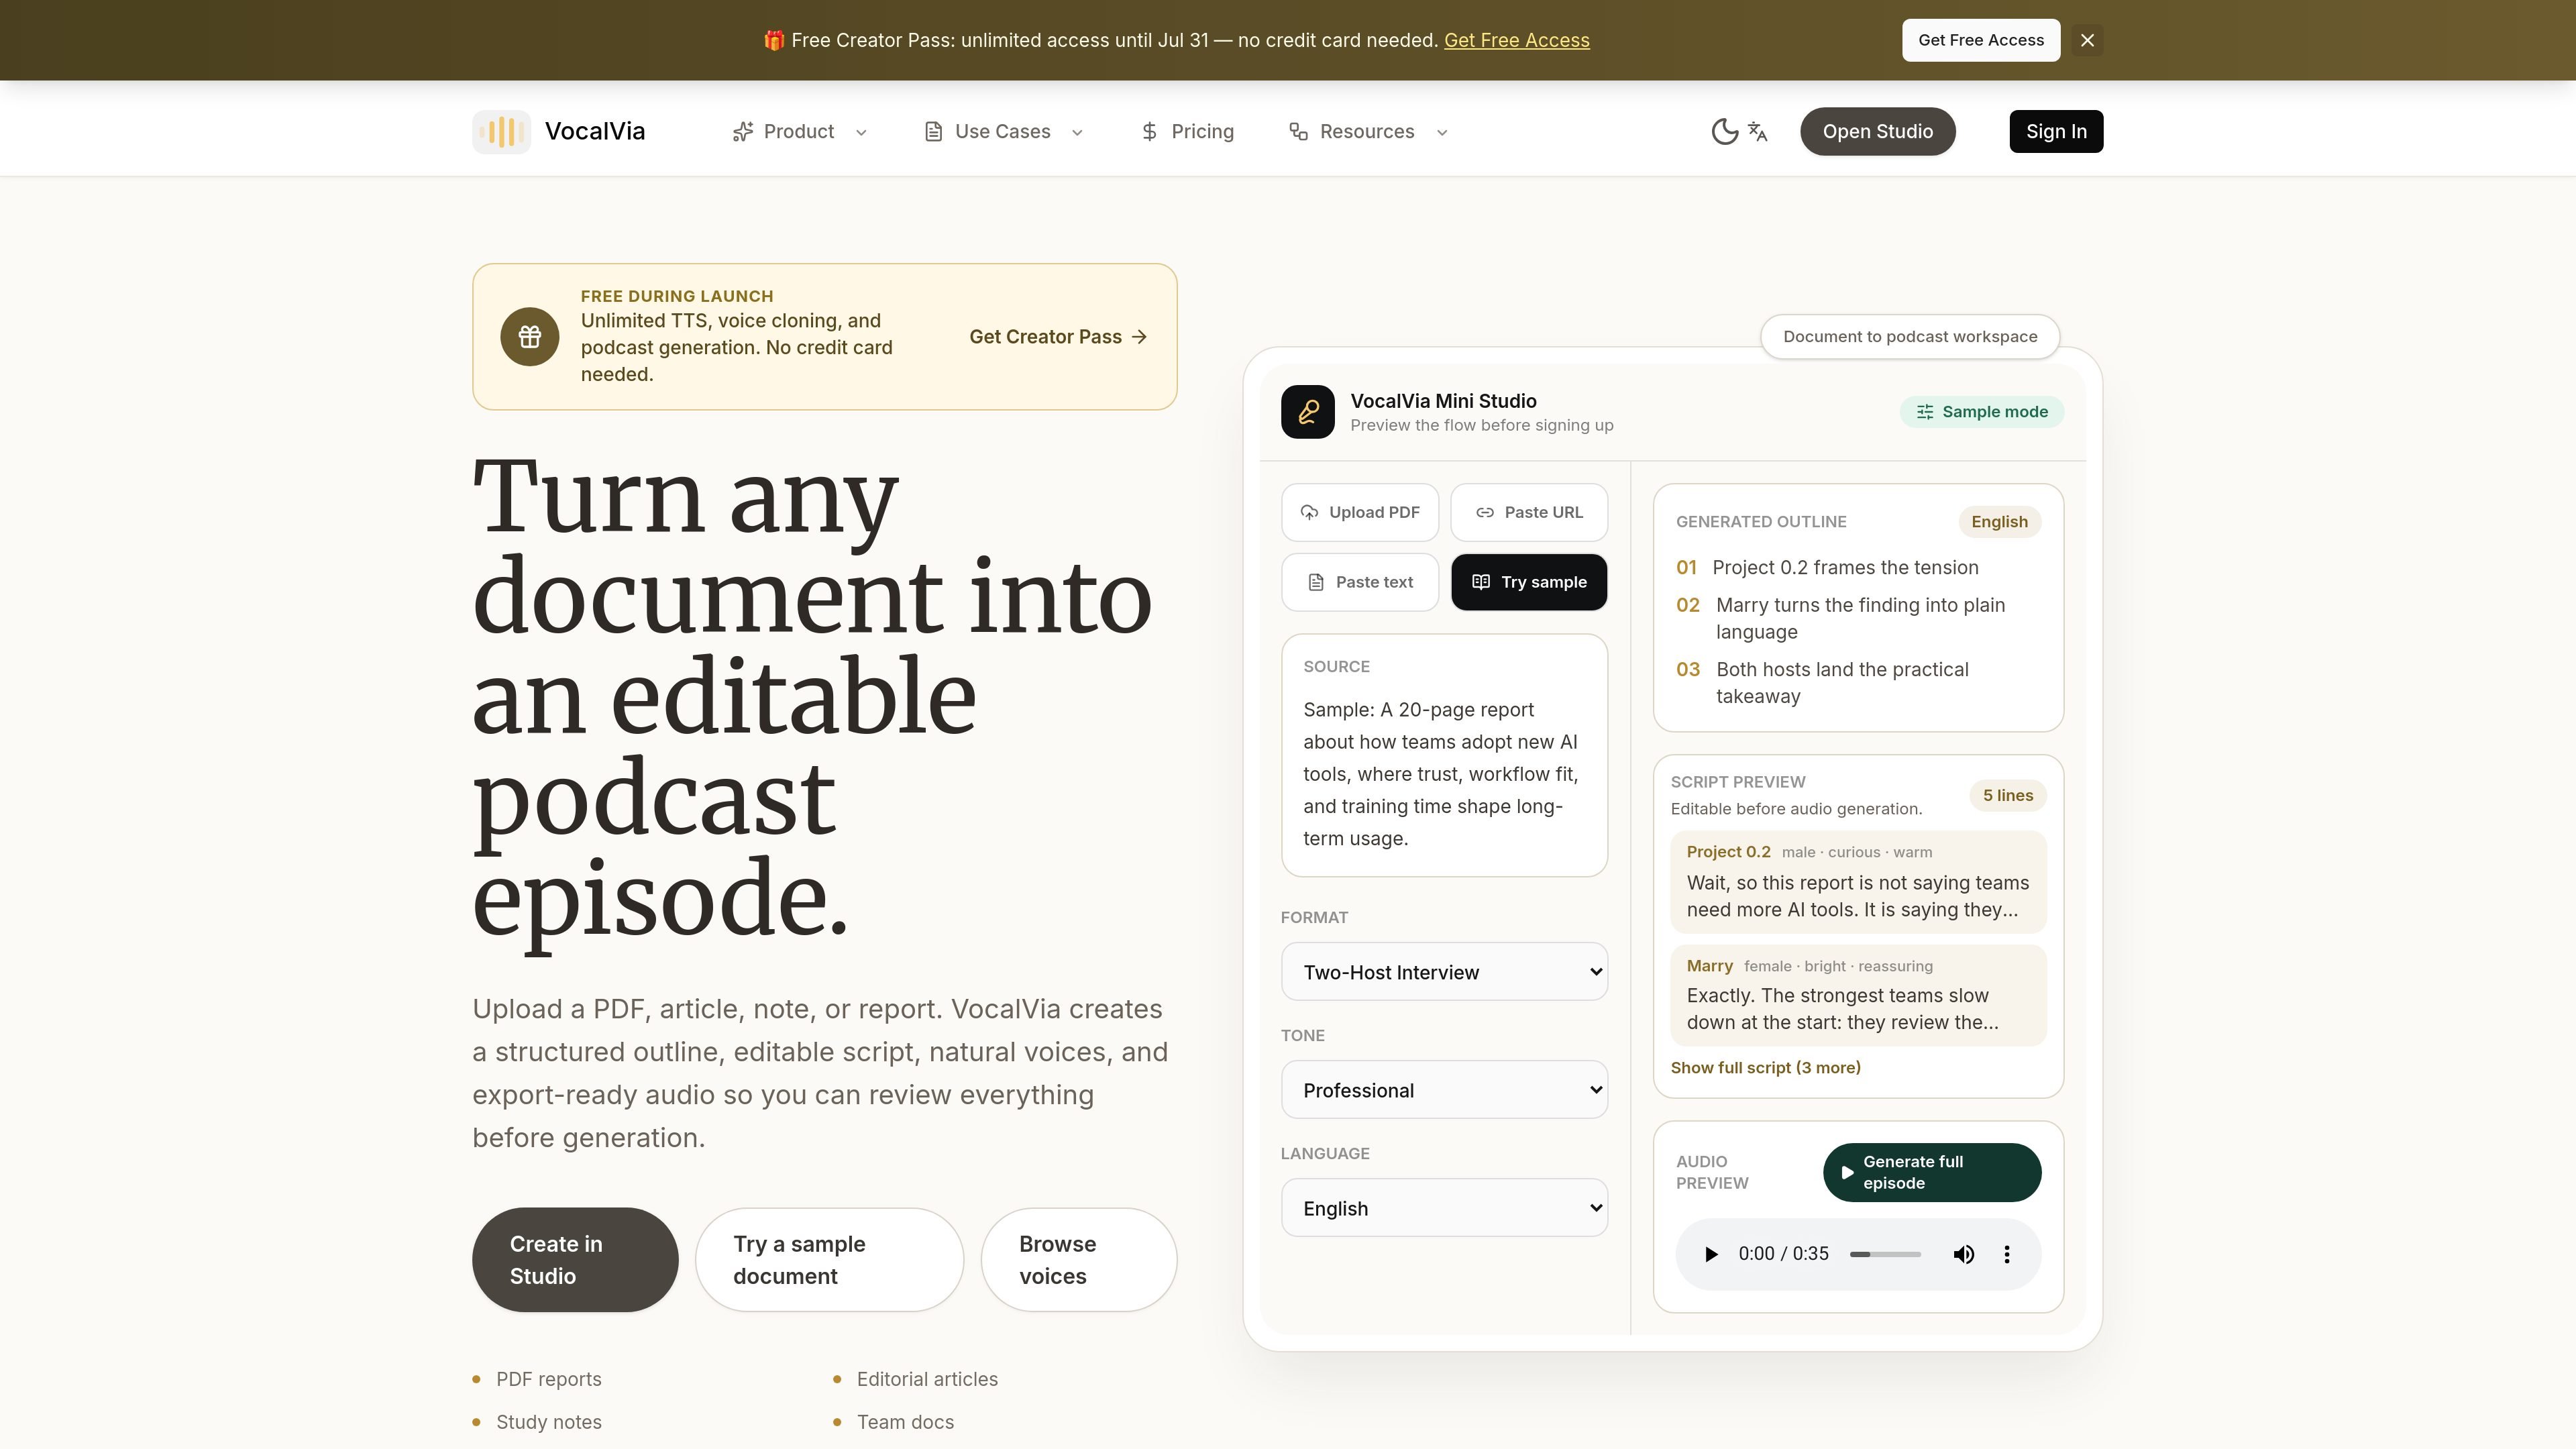

VocalVia is a document-to-podcast tool that converts PDFs, articles, notes, Markdown, and web sources into editable podcast drafts and audio. It is aimed at people who want to review the outline and script before generating the final file.
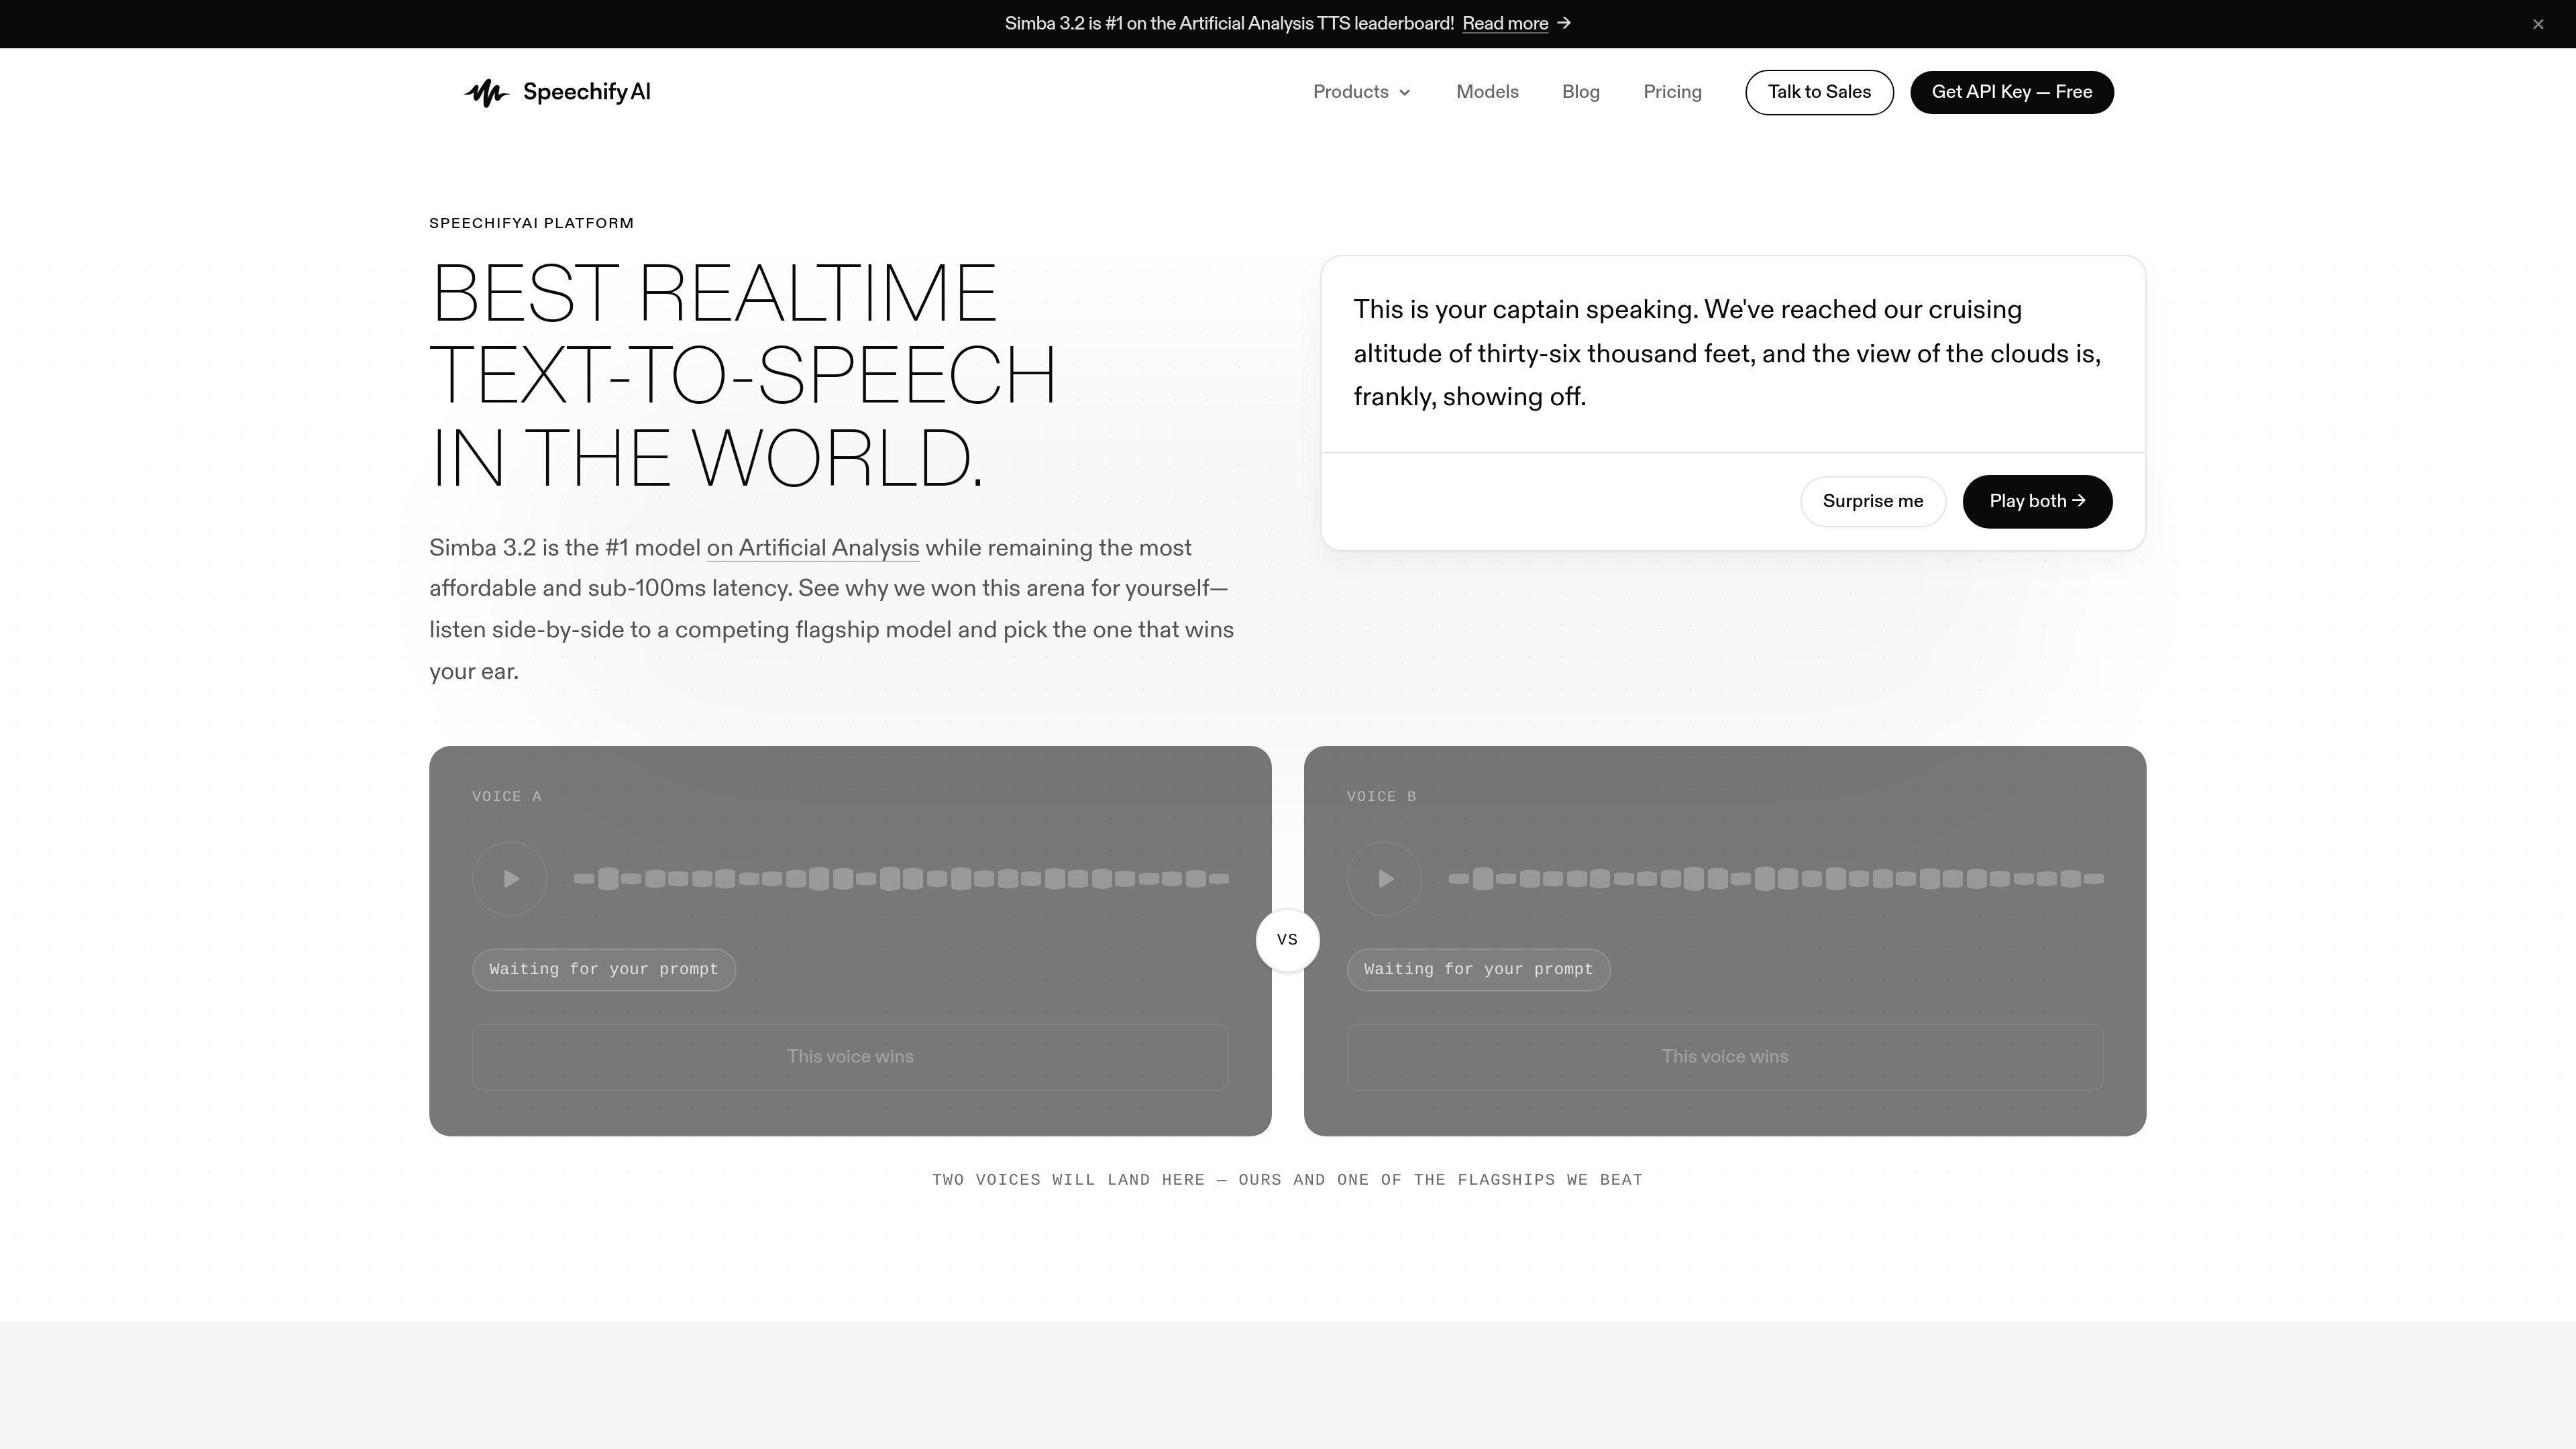

SpeechifyAI is a voice AI platform for generating speech, cloning voices, and building voice agents. It serves developers who need text-to-speech, multilingual audio, and calling workflows through a single API.
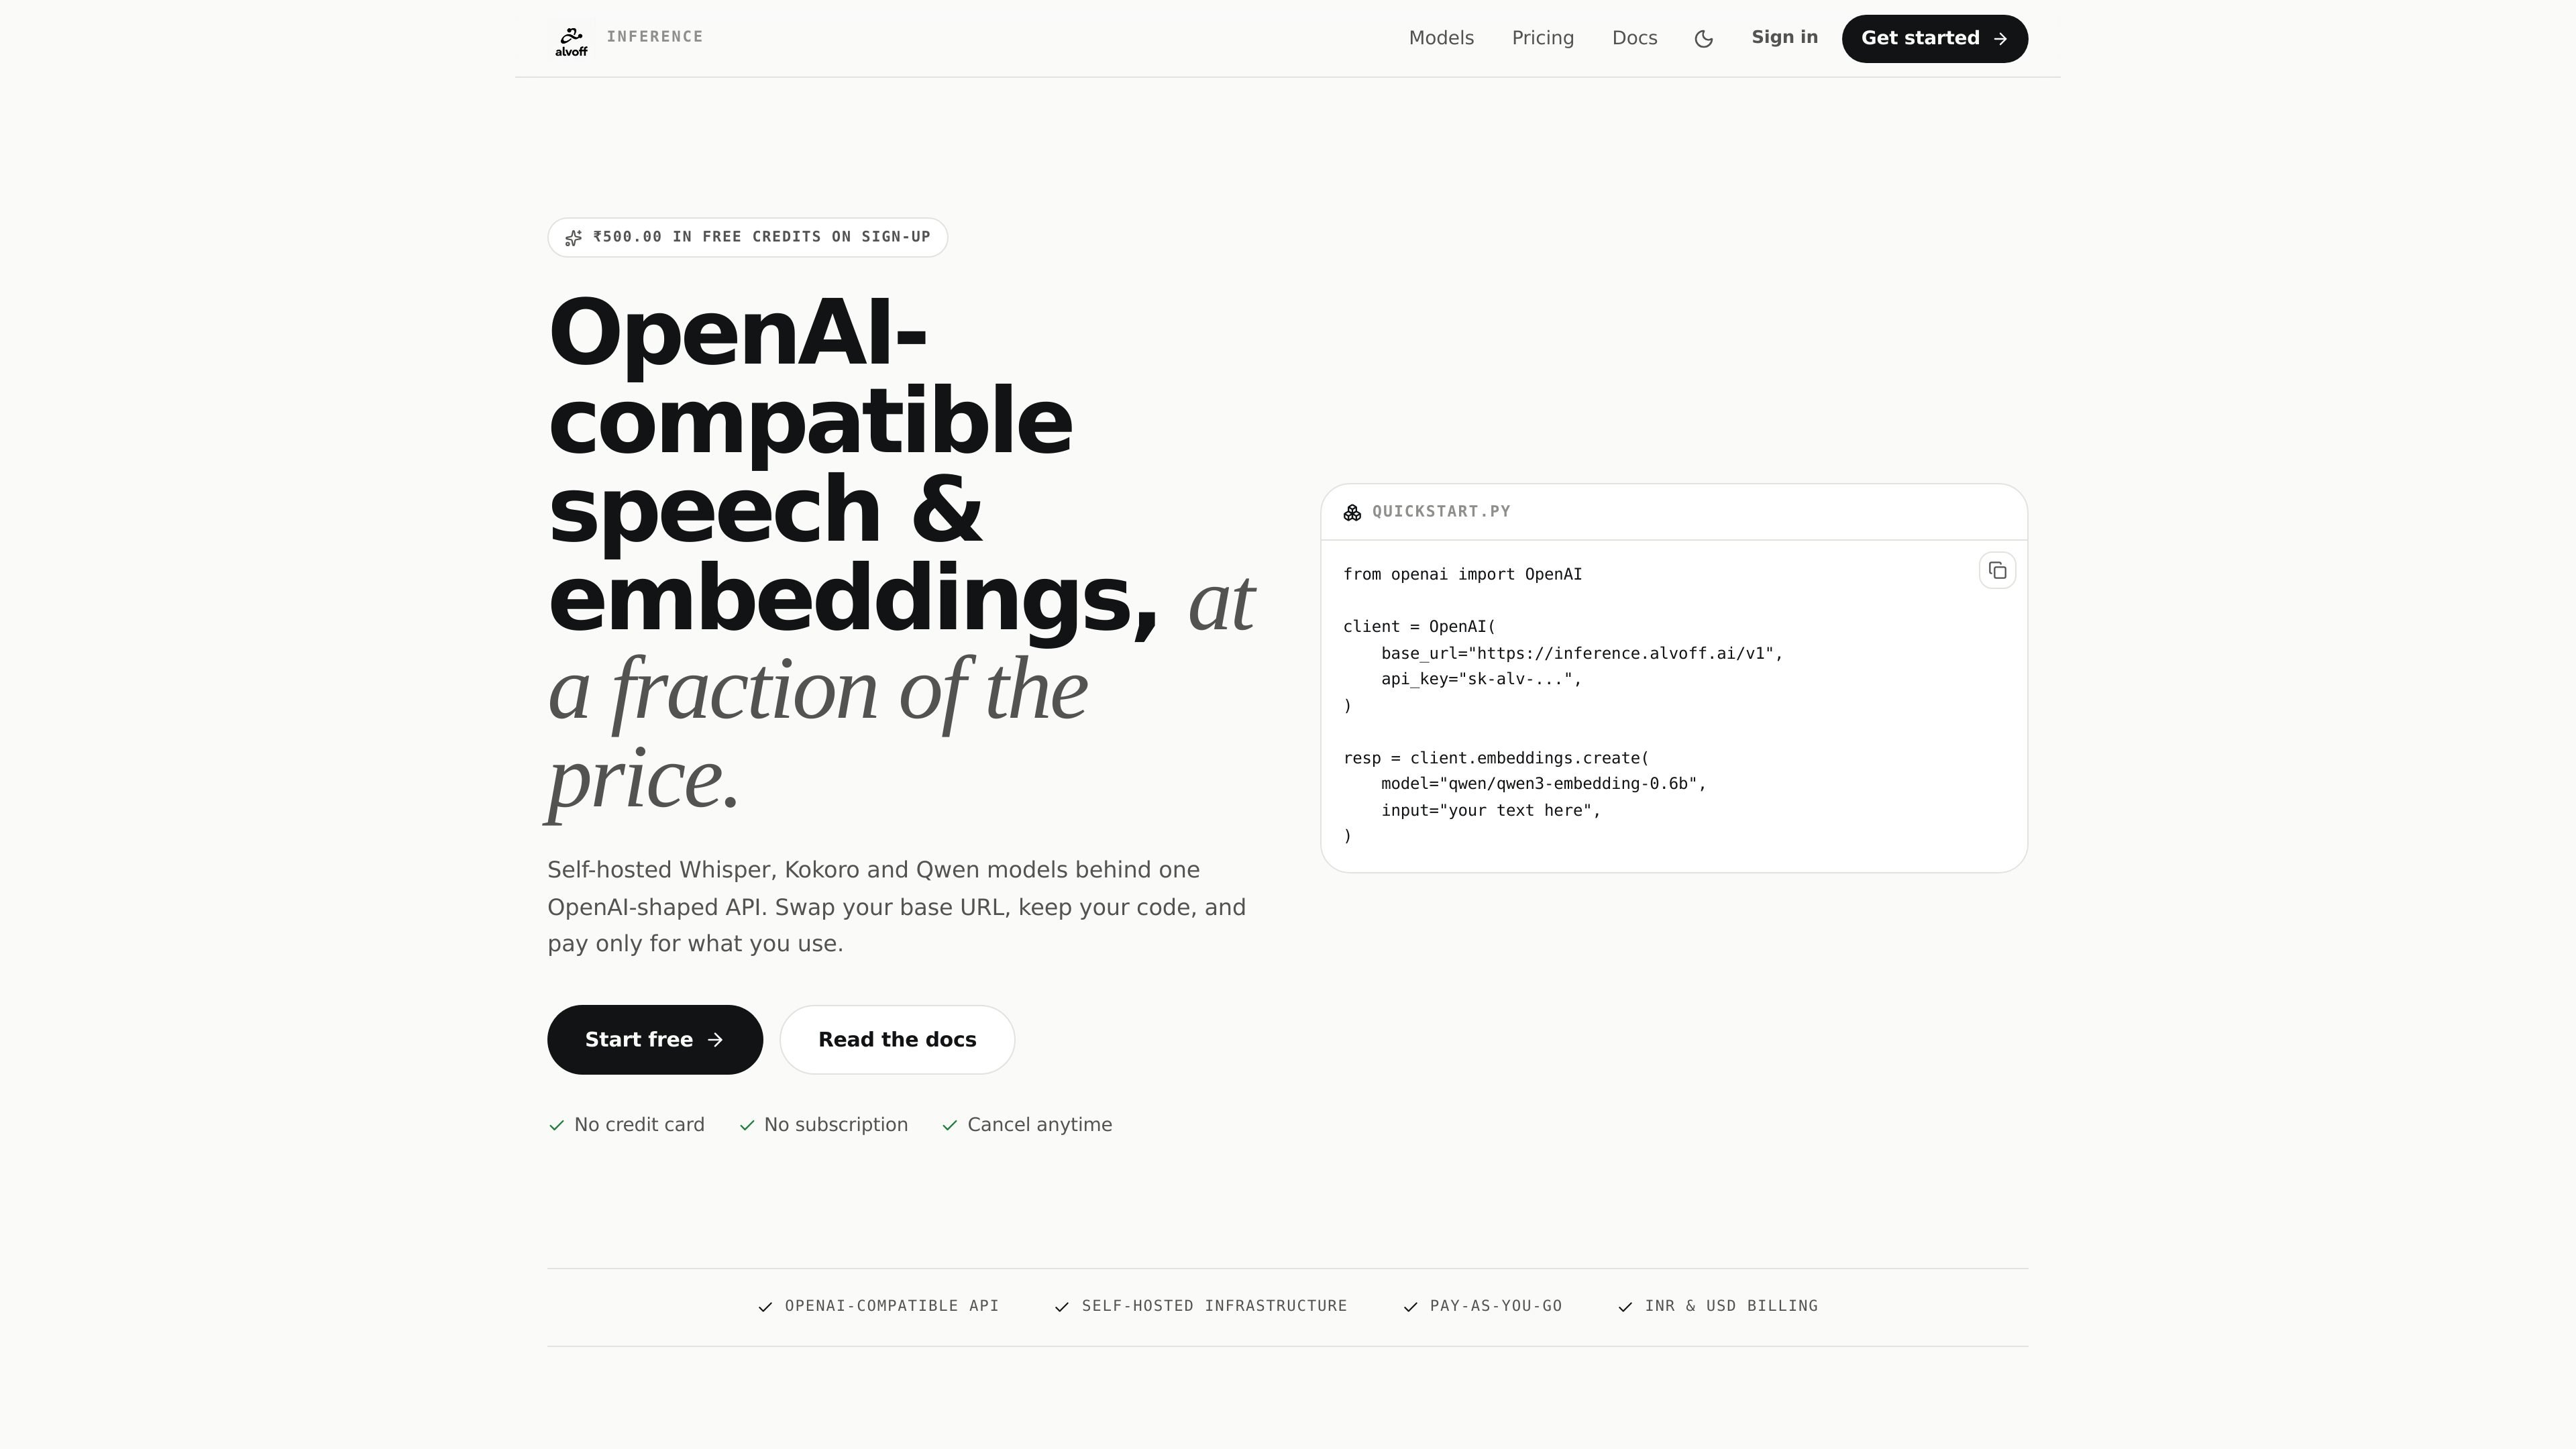

Alvoff Inference is an OpenAI-compatible API for speech-to-text, text-to-speech, embeddings, and chat/code generation. It is built for developers who want to swap in a different base URL, use familiar SDKs, and pay per request.
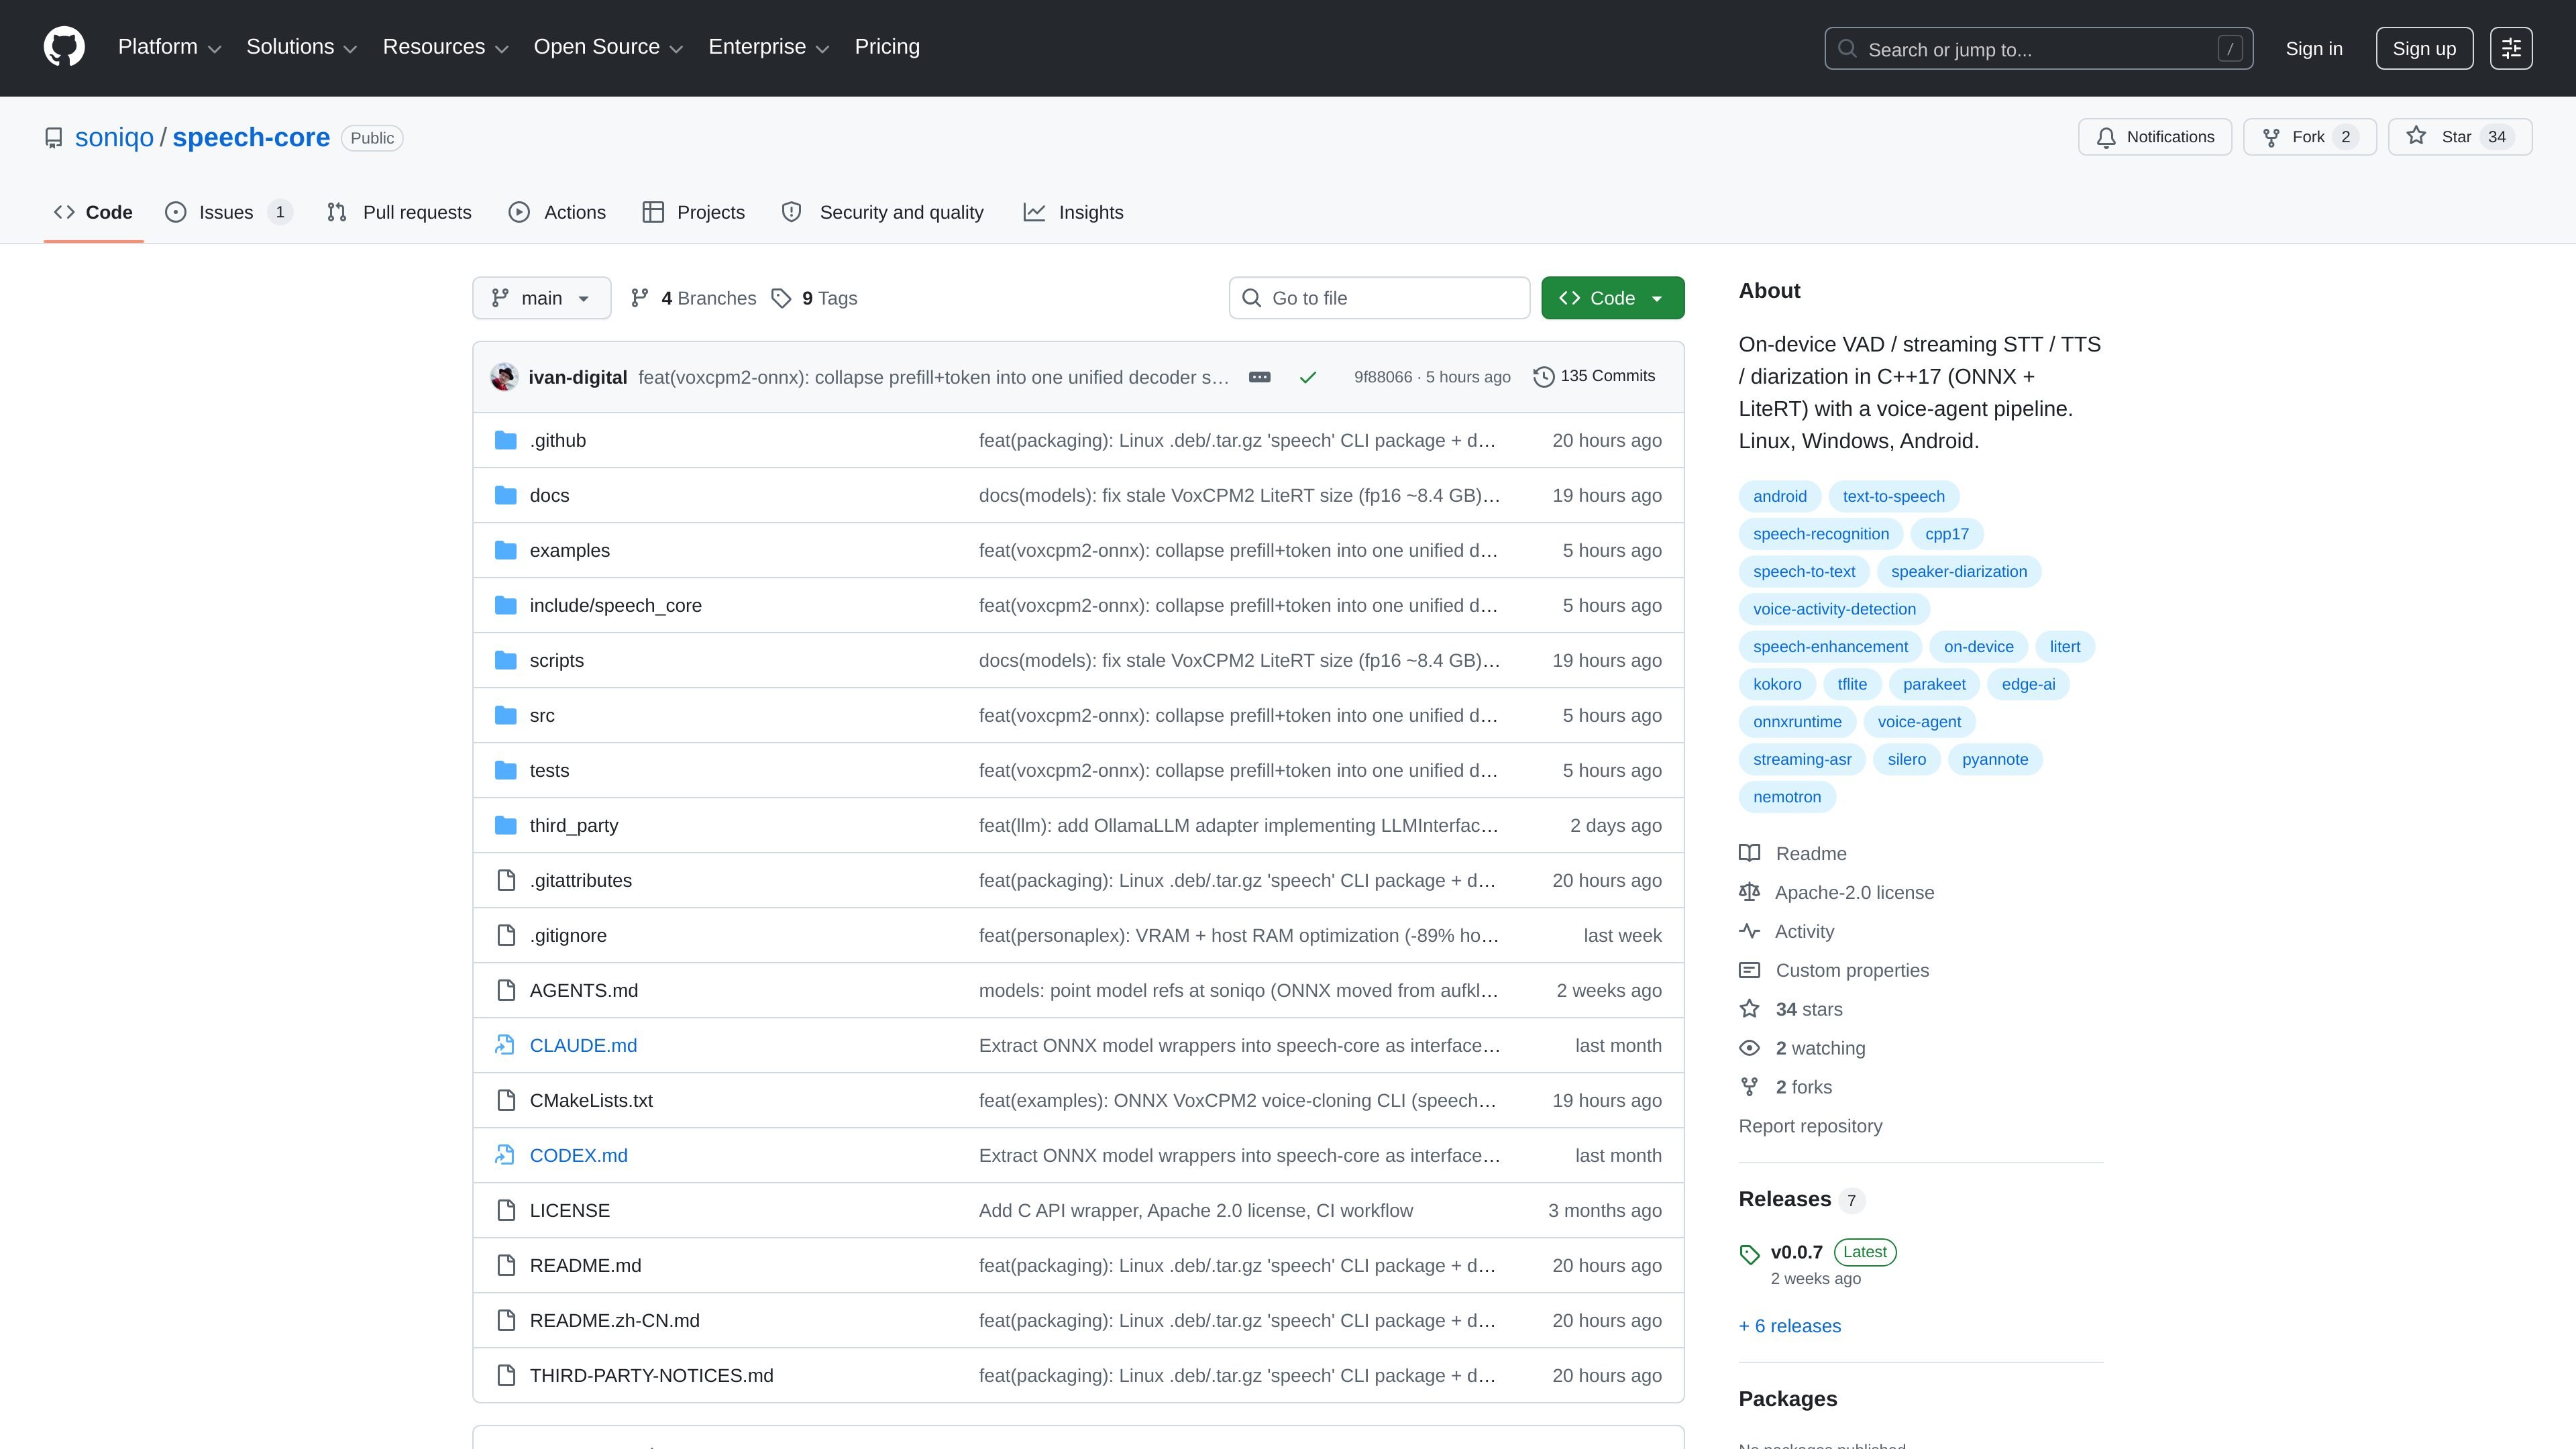

speech-core is a C++17 library for on-device speech orchestration, including VAD, streaming and batch STT, diarization, TTS, and a voice-agent pipeline. It runs locally and uses optional ONNX Runtime or LiteRT backends for model inference.

Voiser AI Voiceover turns text into spoken audio for voiceovers, with multilingual voice options and style controls for different narration needs. It supports a web studio workflow and shows free, paid, and enterprise paths on the site.