
Loading...

Gemini 3.8 Flash and Gemini 3.8 Flash Cyber are Google Gemini models for agentic coding, multi-step reasoning, and cybersecurity defense. 3.8 Flash is the general workhorse model, while 3.8 Flash Cyber is available to trusted defenders through the Fairwind Program.

Anthropic’s Claude Fable 5.1 is a generally available AI model for coding, knowledge work, and long-running problem-solving, while Claude Mythos 5.1 is a higher-safeguard version limited to trusted access programs. The release also adds new enterprise safeguards and lower estimated token-billed pricing for typical workloads.
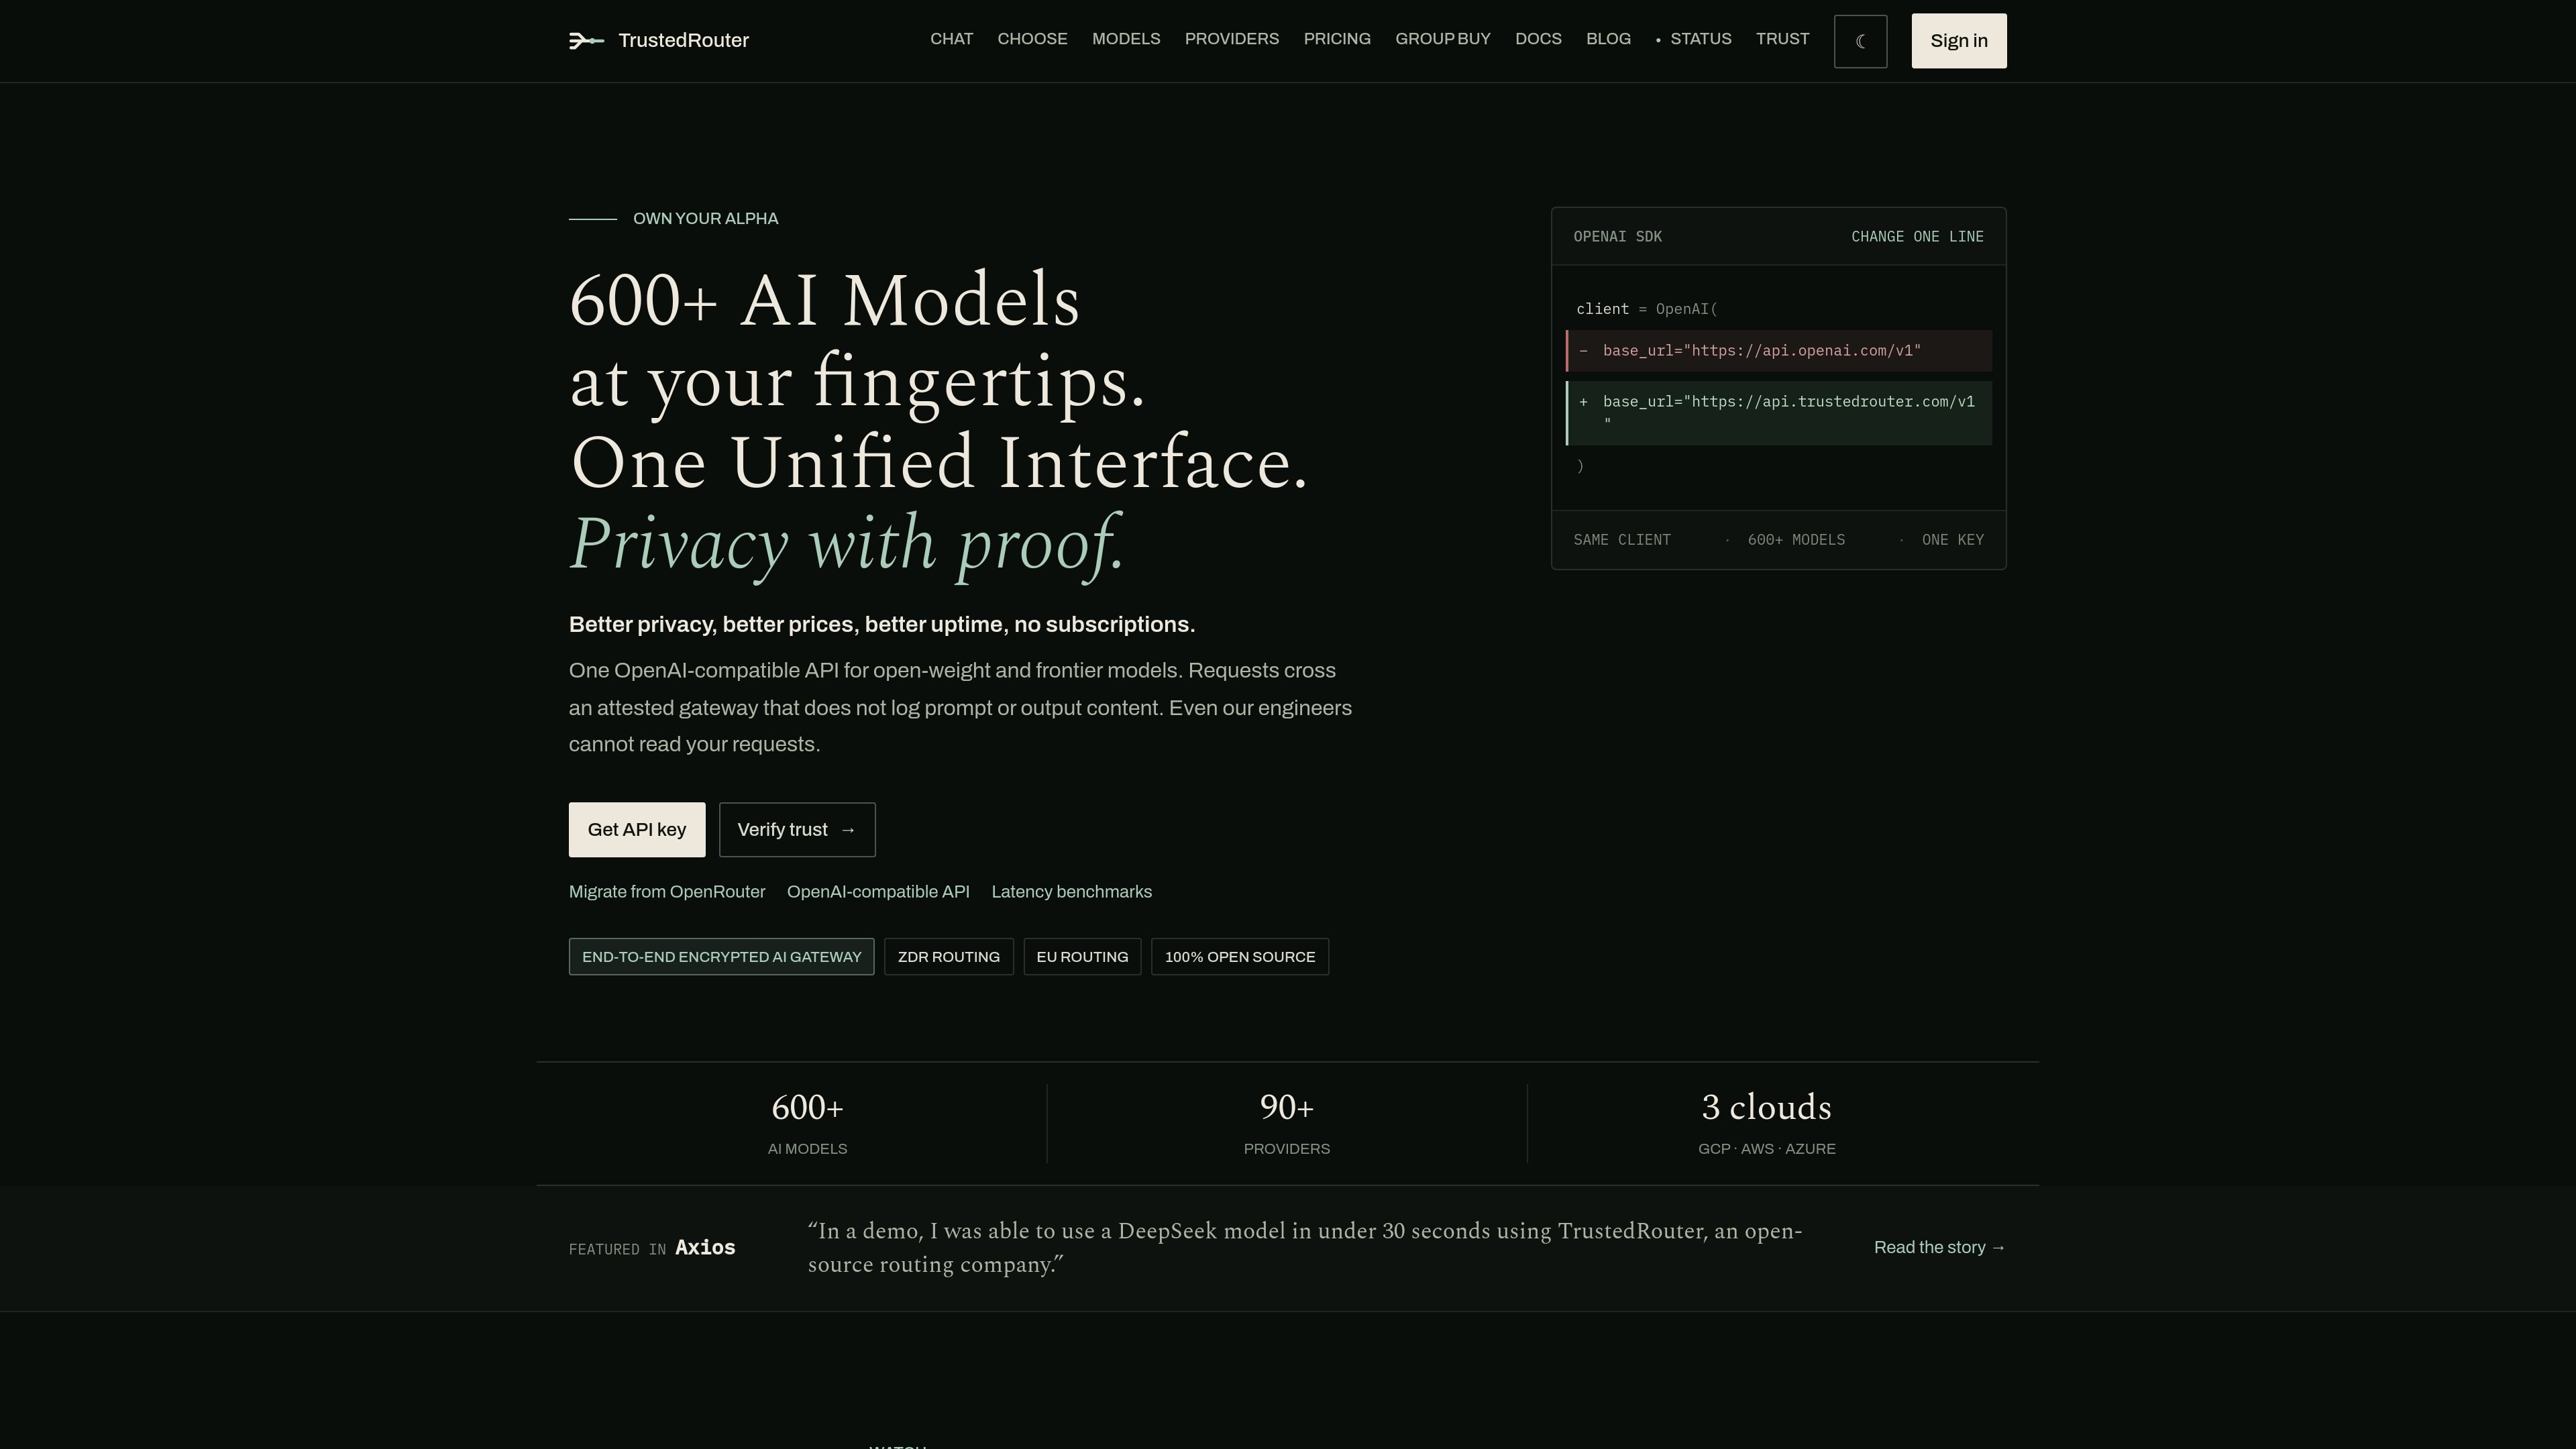

TrustedRouter is an OpenAI-compatible AI router for accessing hundreds of models through one API with verifiable privacy, provider failover, and BYOK support. It is aimed at developers and teams migrating existing OpenAI-style workflows or adding routing and trust controls to production traffic.
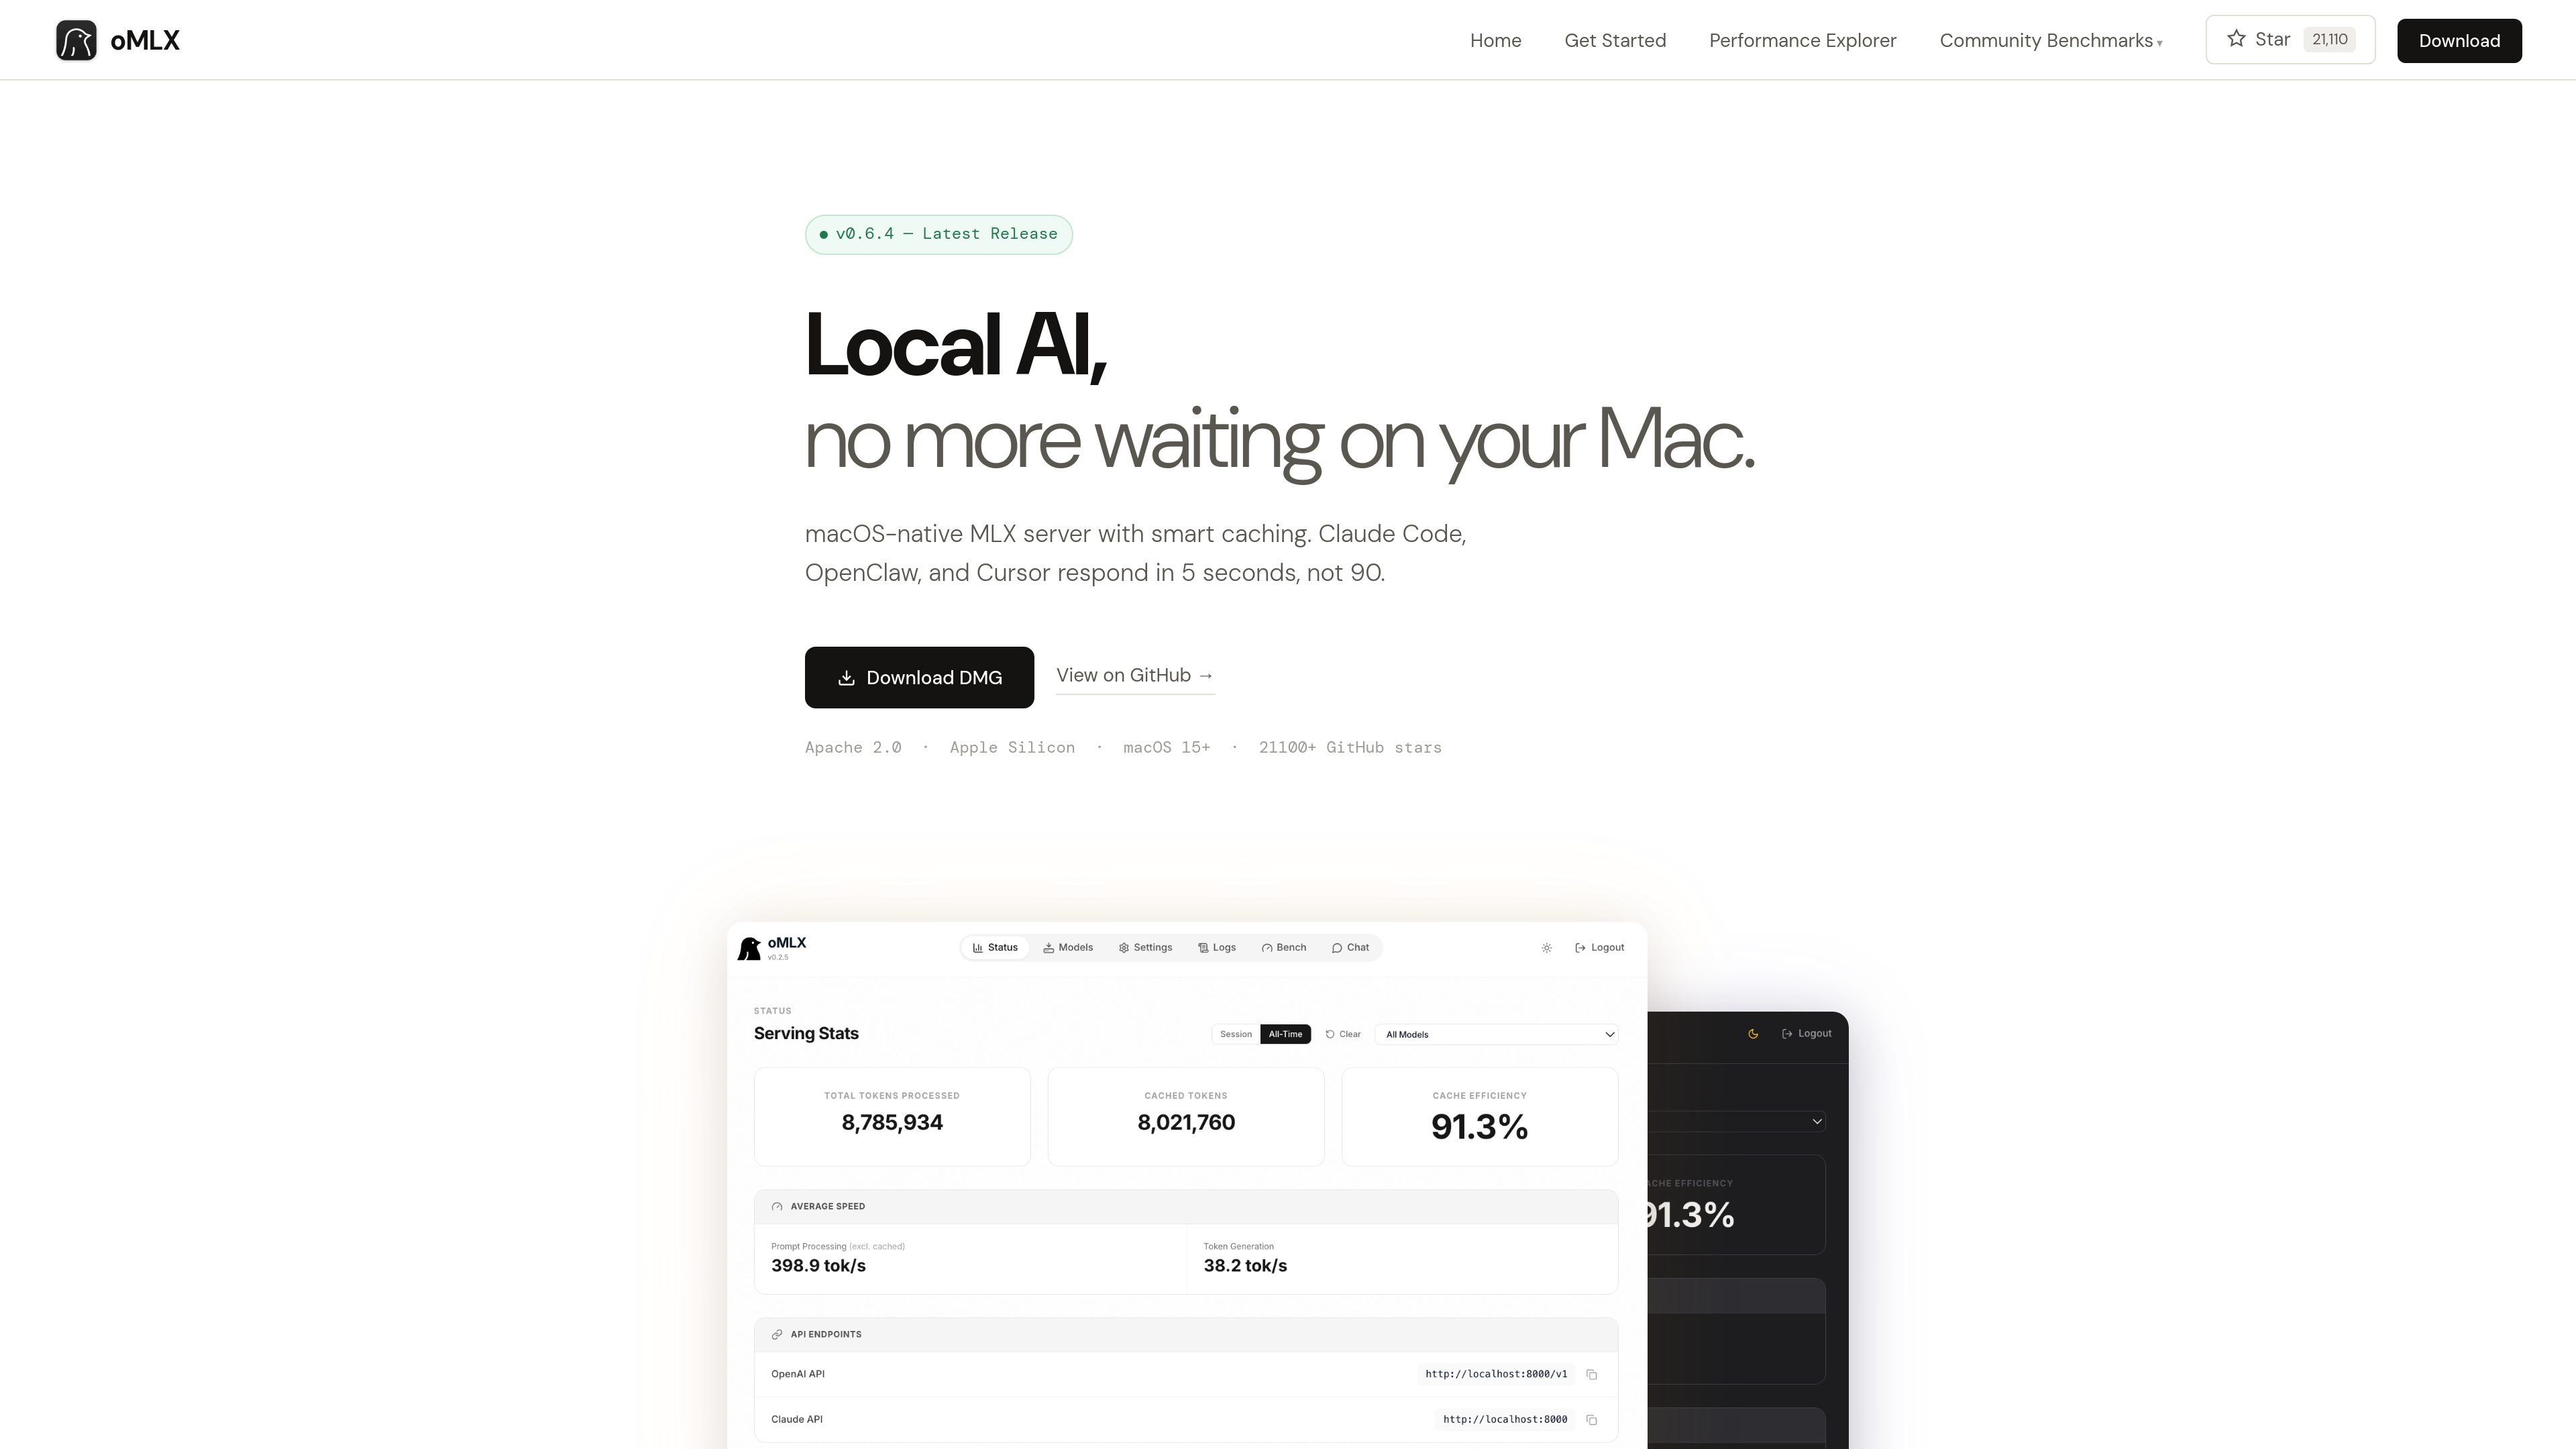
oMLX is a native macOS inference server built on MLX for running local models on Apple Silicon Macs. It supports SSD-backed KV caching, continuous batching, and OpenAI- and Anthropic-compatible endpoints for tools such as Claude Code, OpenClaw, and Cursor.
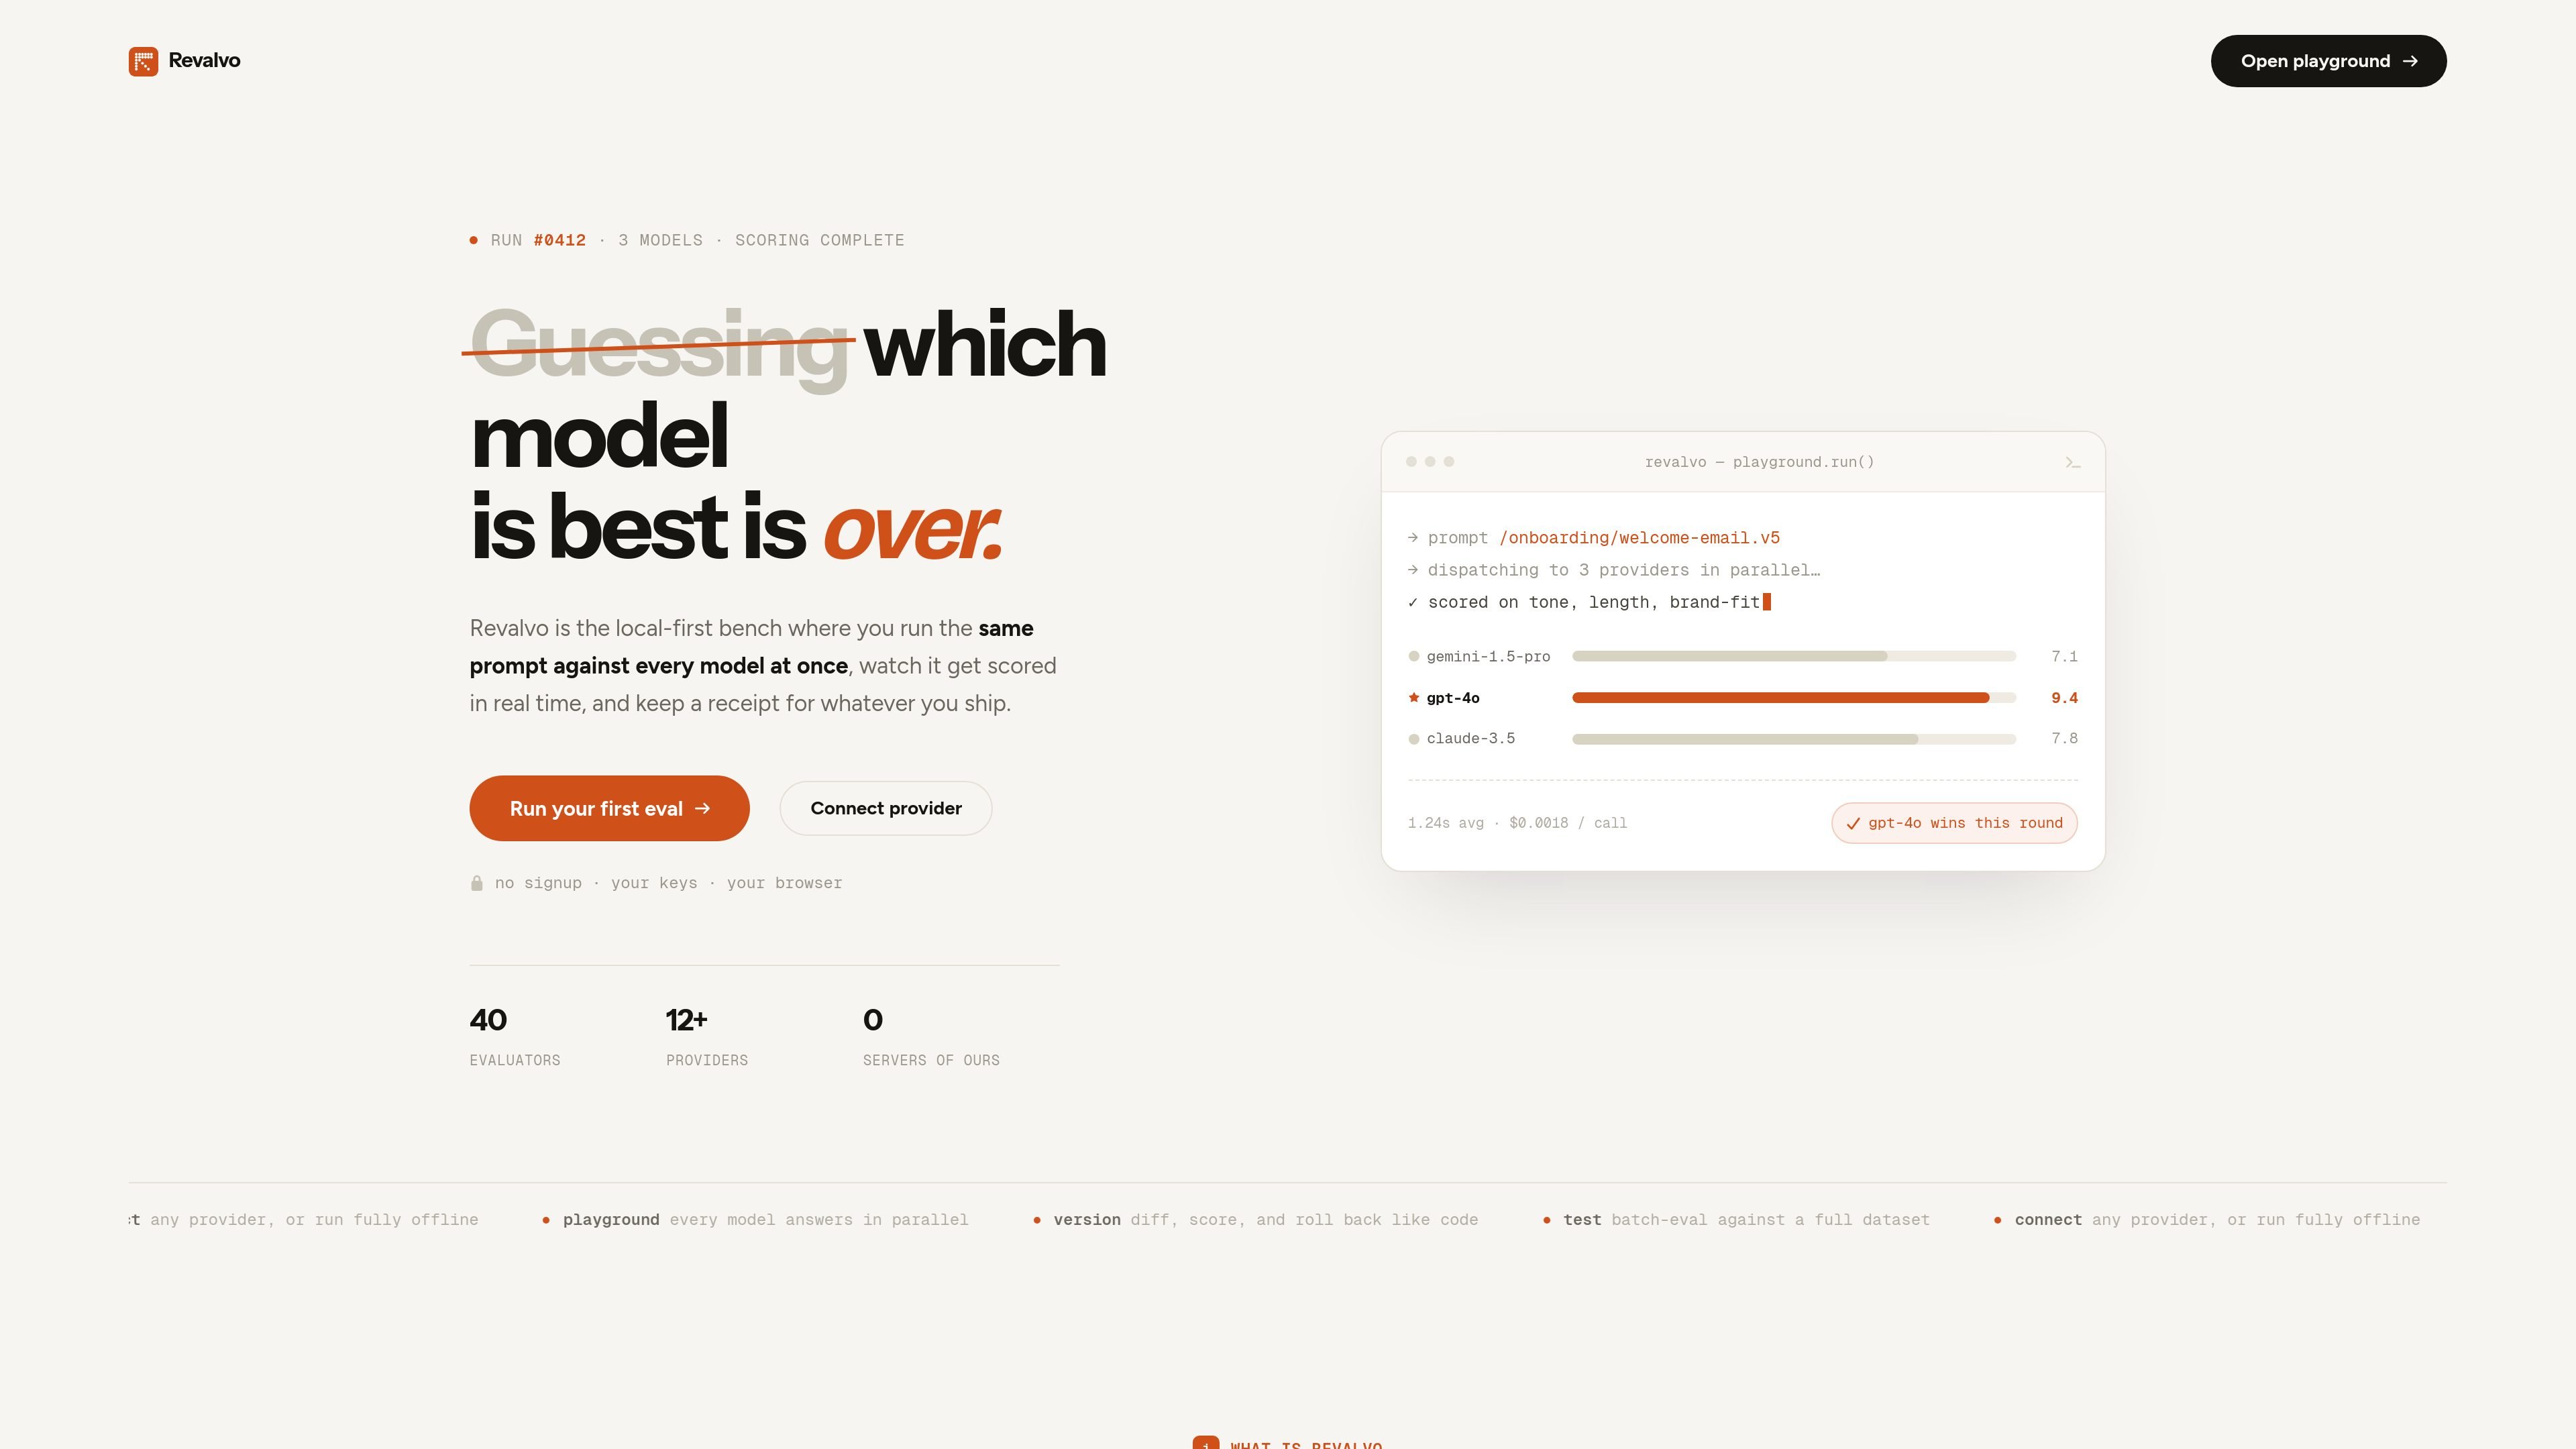
Revalvo is a browser-based, local-first LLM eval workbench for running prompts across multiple models, scoring results, versioning prompts, and batch-testing datasets. It is designed for users who want to compare outputs and keep prompt work in the browser without creating an account.
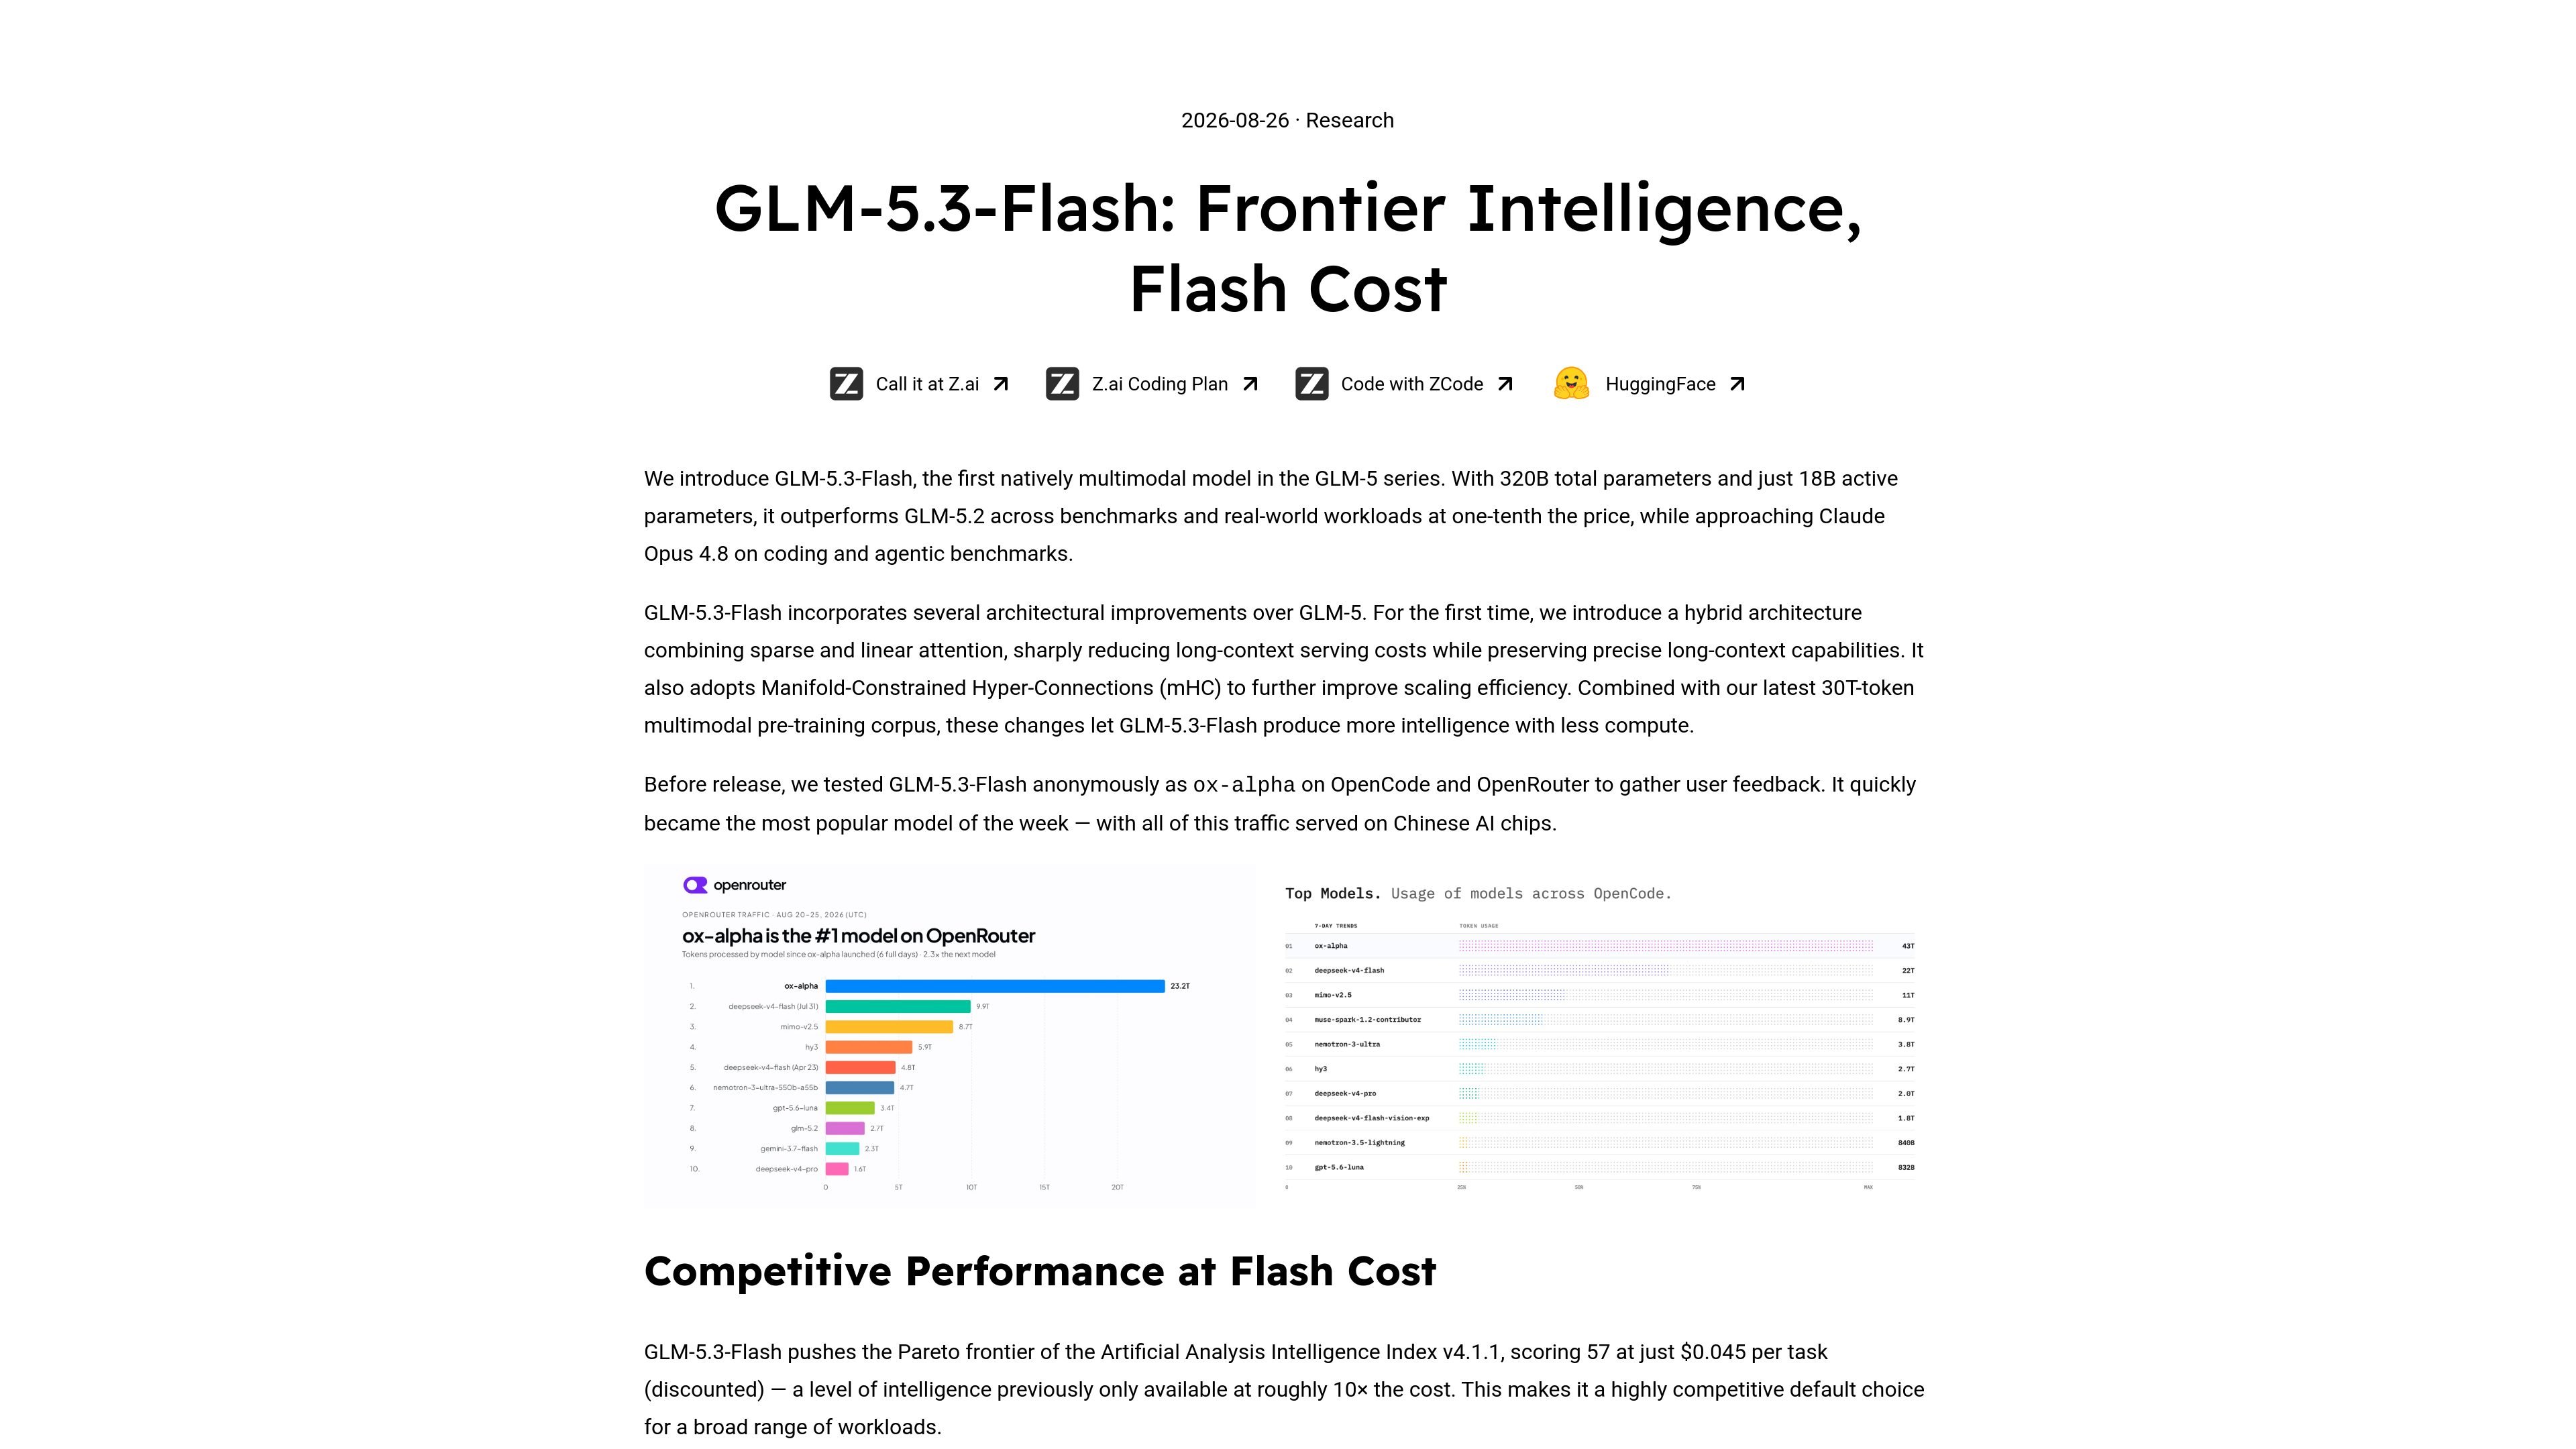

GLM-5.3-Flash is Z.ai’s native multimodal model for coding, agentic workflows, and visually grounded tasks. It is offered through the Z.ai API platform and coding plan, with the release emphasizing lower inference cost and stronger benchmark performance than GLM-5.2.
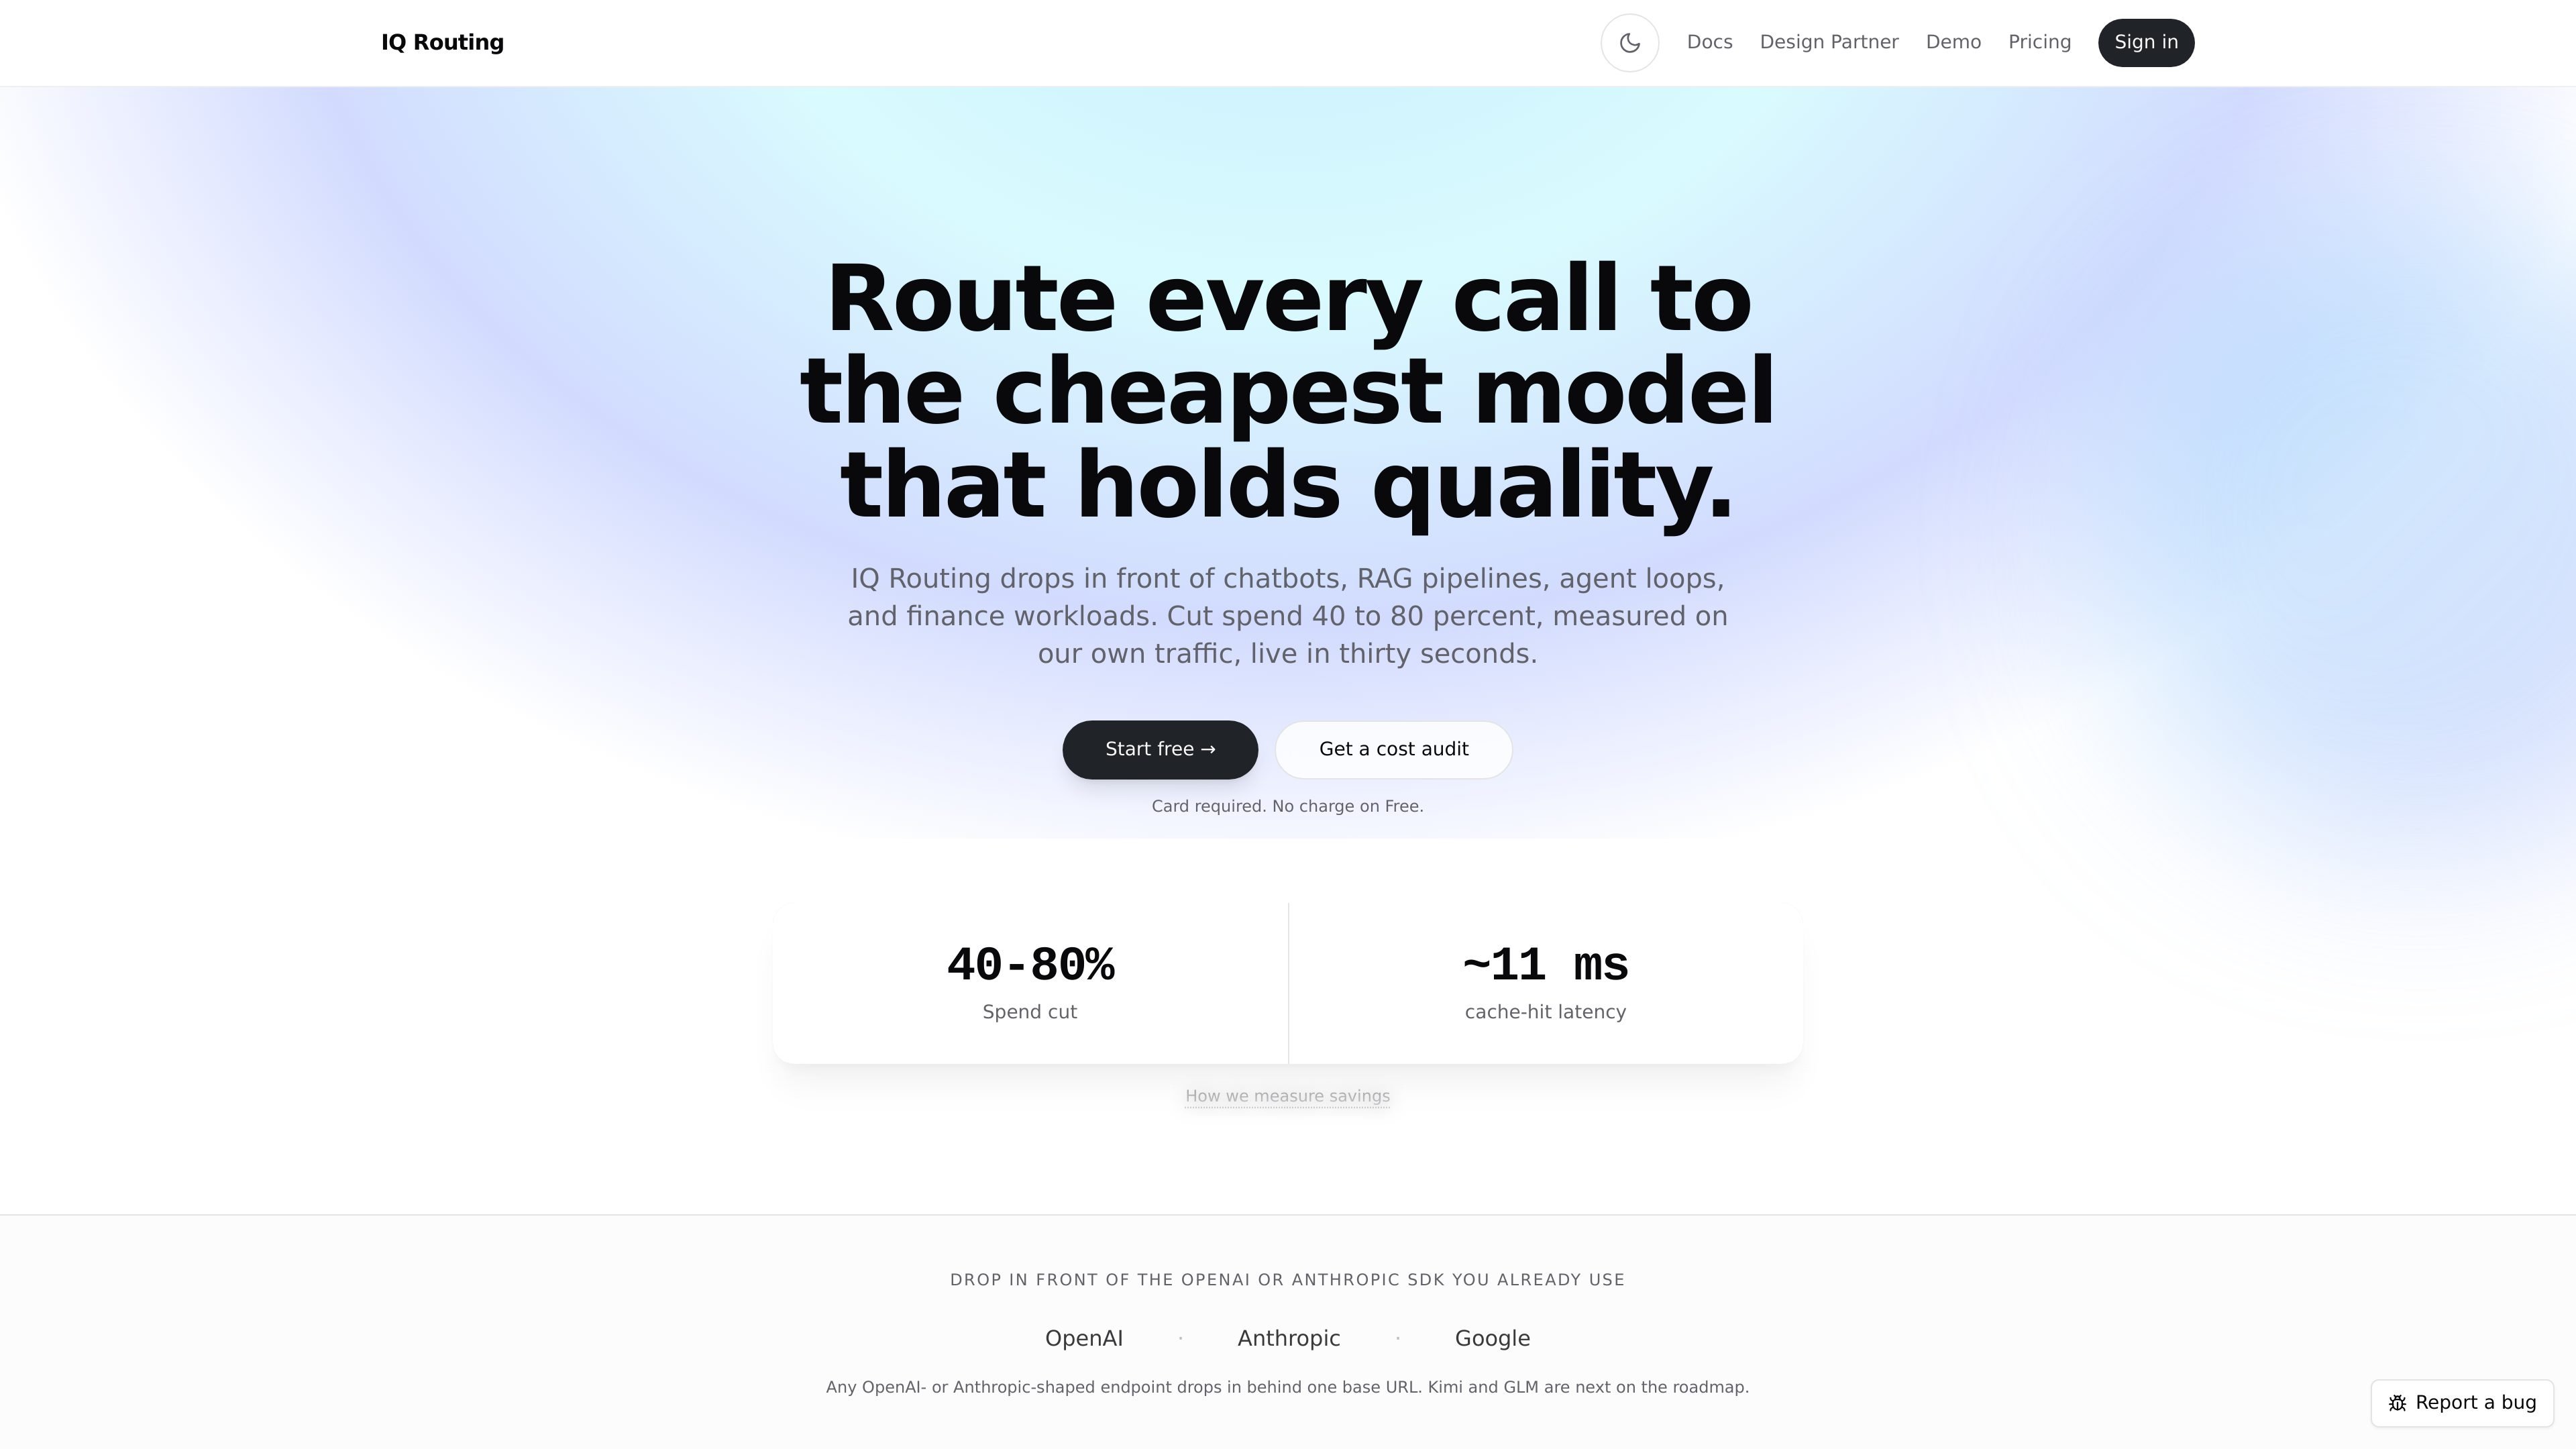

IQ Routing is a model-routing gateway that sends each request to the cheapest model tier that still meets a quality bar. It is built for teams running chatbots, RAG pipelines, agent loops, and finance workloads on OpenAI-, Anthropic-, or Google-shaped endpoints.

Speko is a voice AI router that benchmarks speech models by language and routes STT, LLM, and TTS through one API. It also offers a packaged infrastructure option and an enterprise contract path.
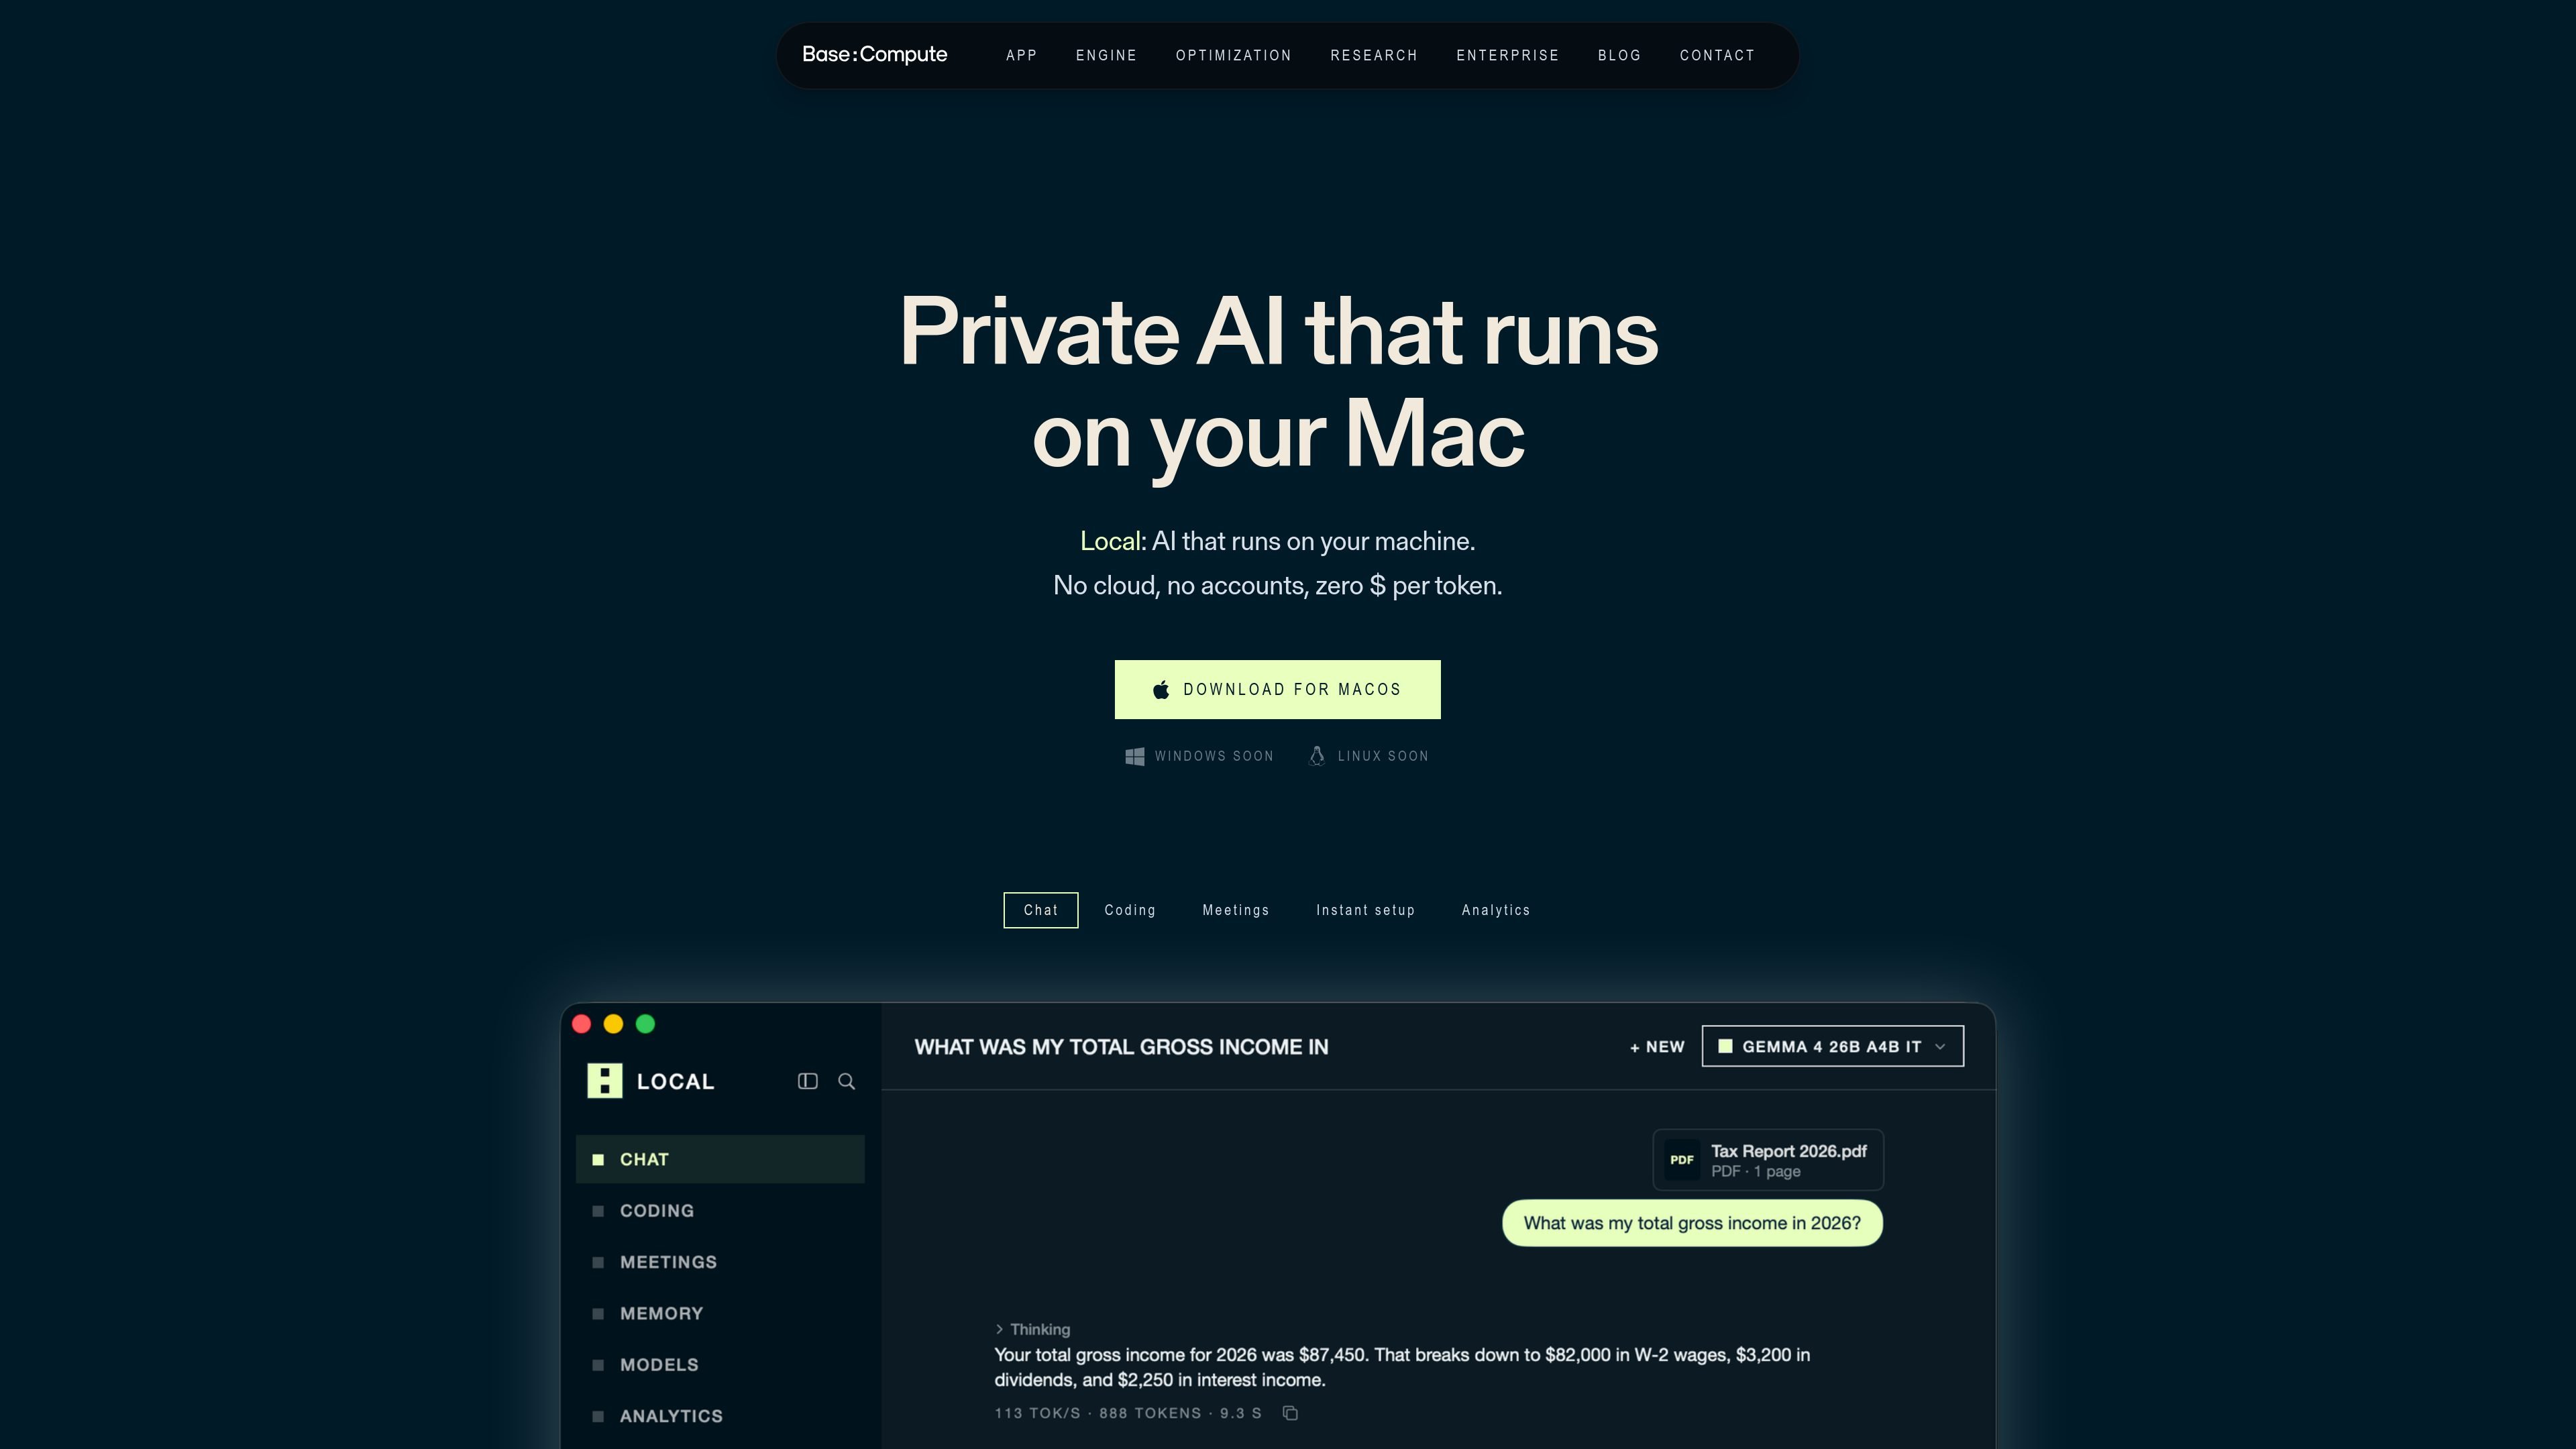
Local is a macOS app that runs AI on your own machine, keeping chat, coding, and meeting workflows on-device. It also recommends models based on your Mac’s chip and memory, with optional cloud model access through your own API key.

Router by Ramp is an AI routing product that gives teams one endpoint and one bill for accessing multiple models. It is designed to lower inference spend while keeping model selection tied to performance needs.

NobodyWho is an on-device inference engine for running LLMs locally and efficiently without API keys or cloud calls. It supports multiple app frameworks and can load GGUF models from Hugging Face or a direct URL.

Grok 4.6 is xAI’s latest Grok model for long-running agent work, coding, research, and interactive or visual project drafting. It is available in Cursor, Grok Build, the API, and partner platforms, with free and paid Grok plans available.

Gemini 3.7 Flash is Google’s Flash-series AI model for coding, agent workflows, web development, and document-heavy knowledge work. It is available to developers, enterprises, and eligible Gemini app subscribers through multiple Google surfaces.

Statewave is an open-source memory runtime for AI agents and LLM apps. It helps teams store durable, structured context with provenance so systems can recall prior events across sessions.
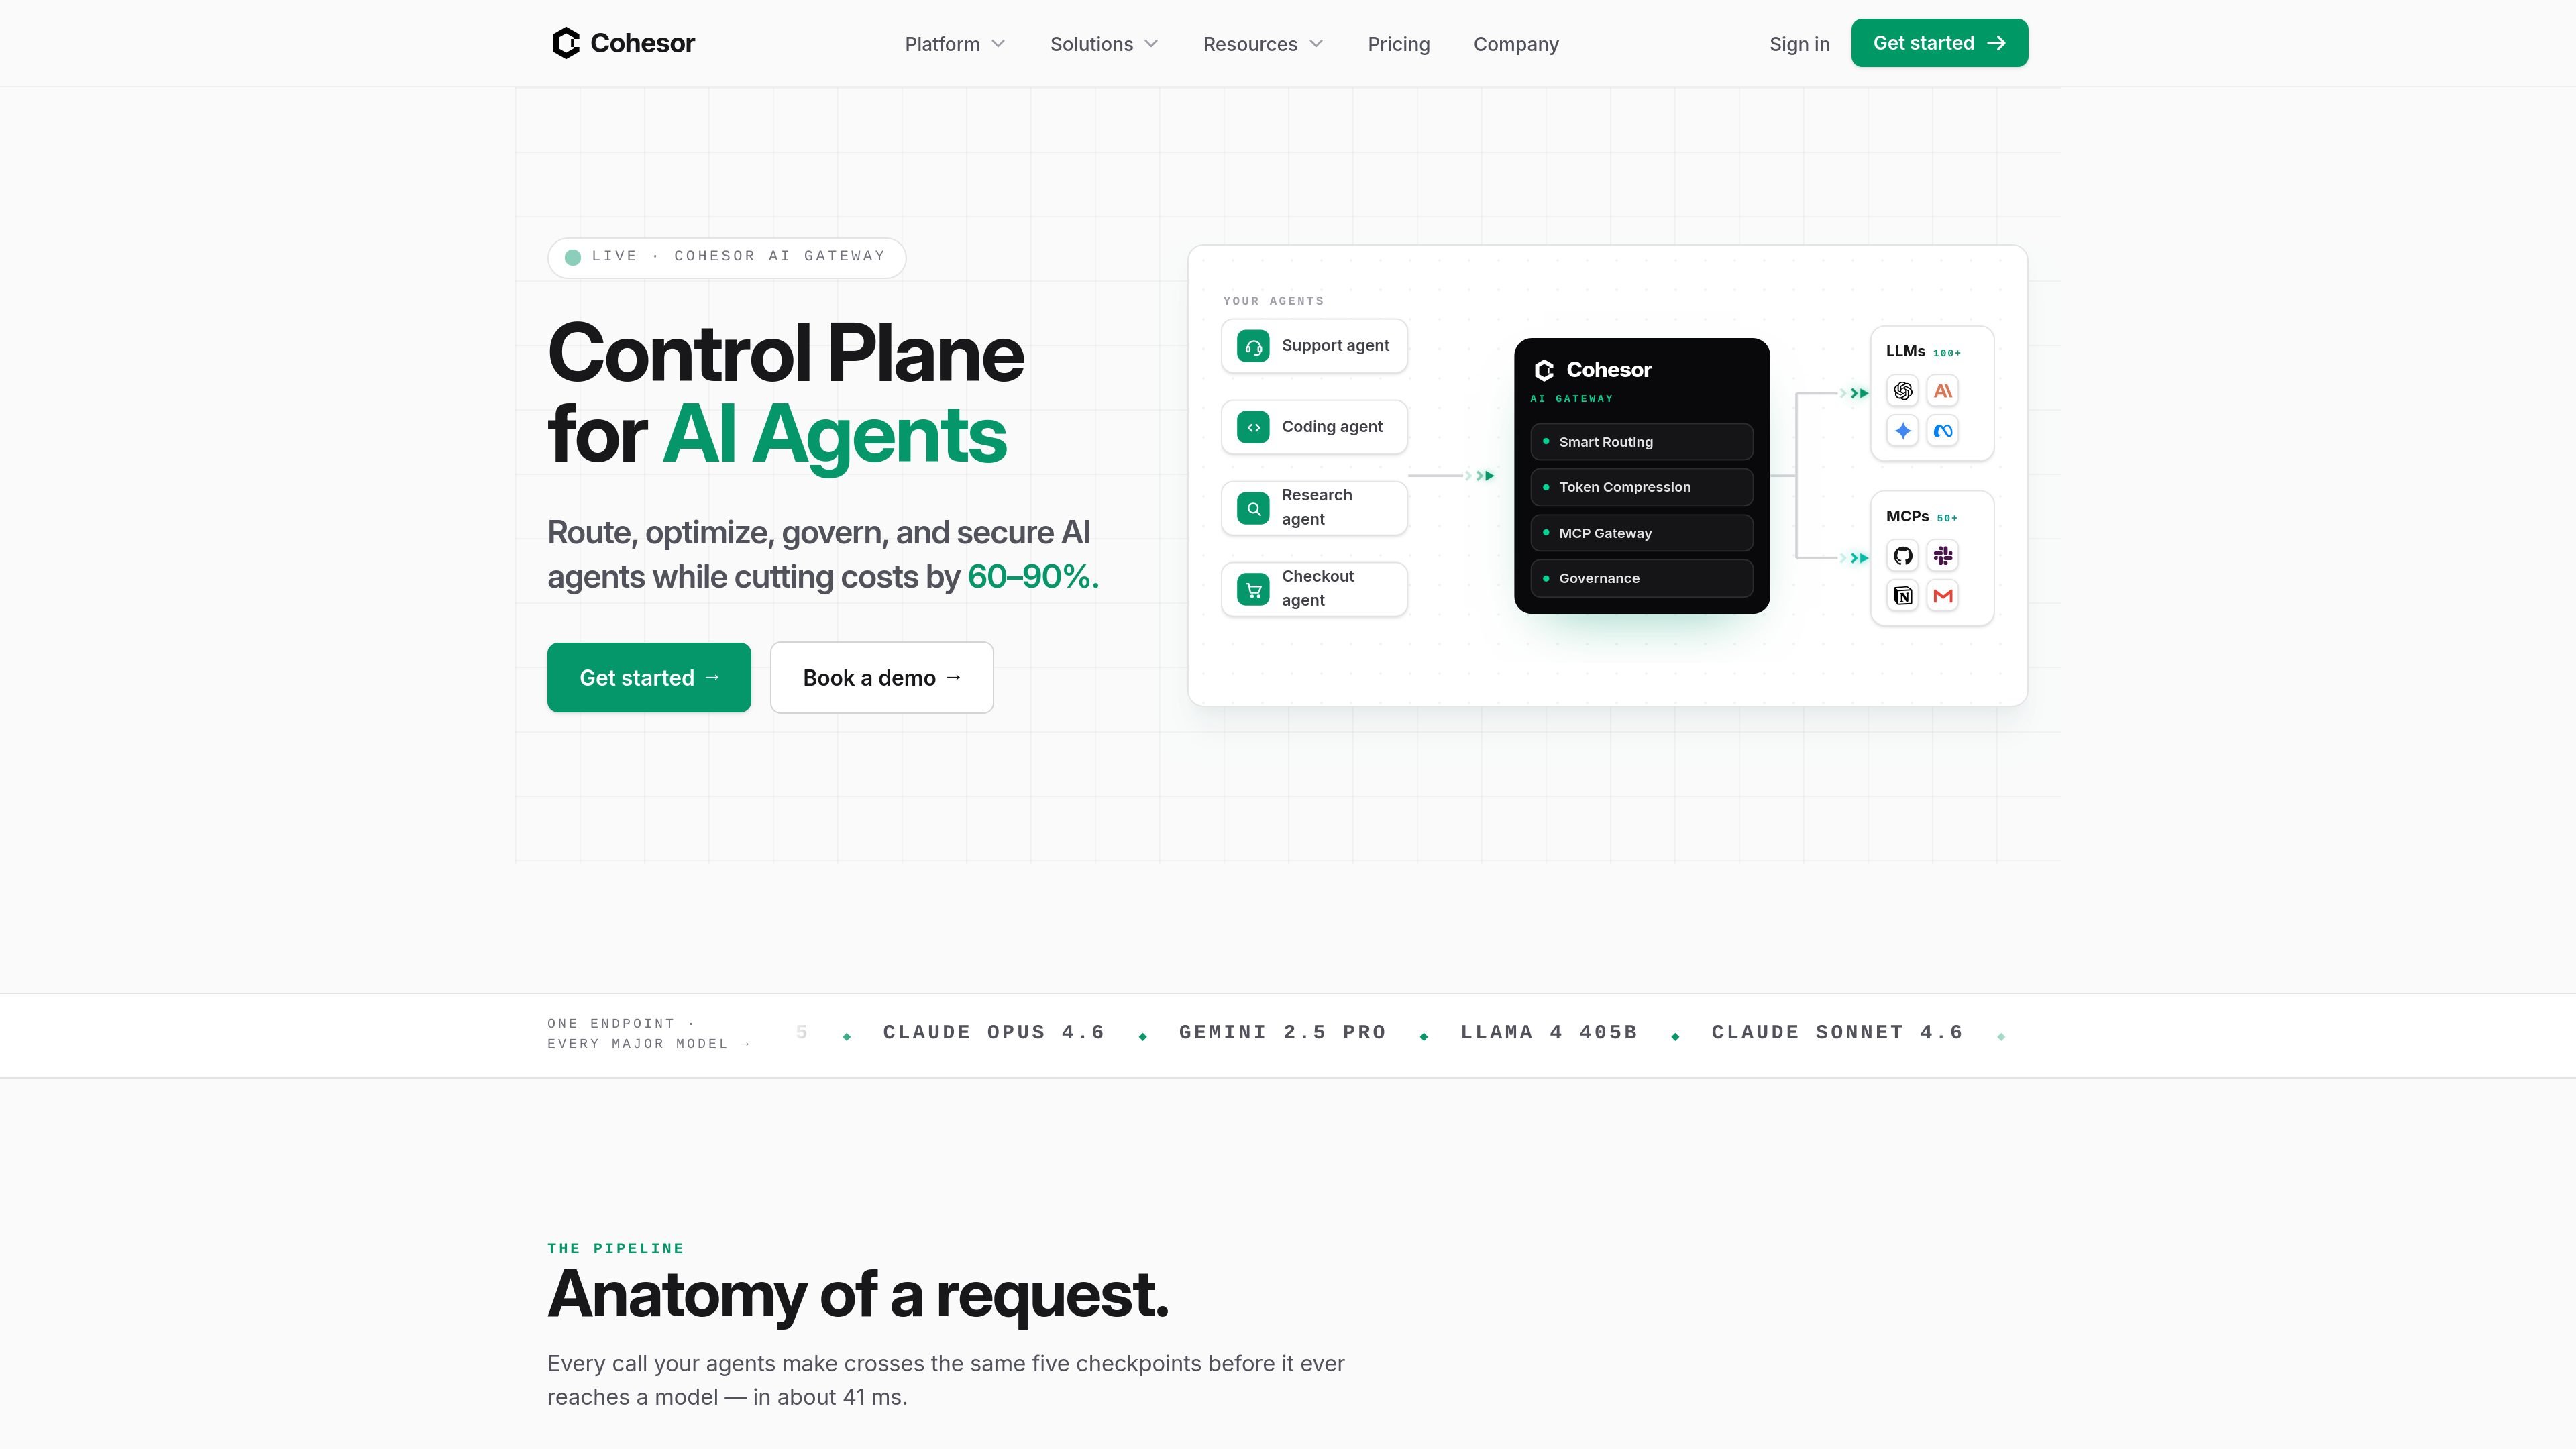

Cohesor is an AI gateway and control plane for agents that routes requests, compresses tokens, brokers MCP tool calls, and enforces policy from one endpoint. It is designed for teams that want to lower model spend and improve visibility without rewriting existing Anthropic- or OpenAI-compatible clients.
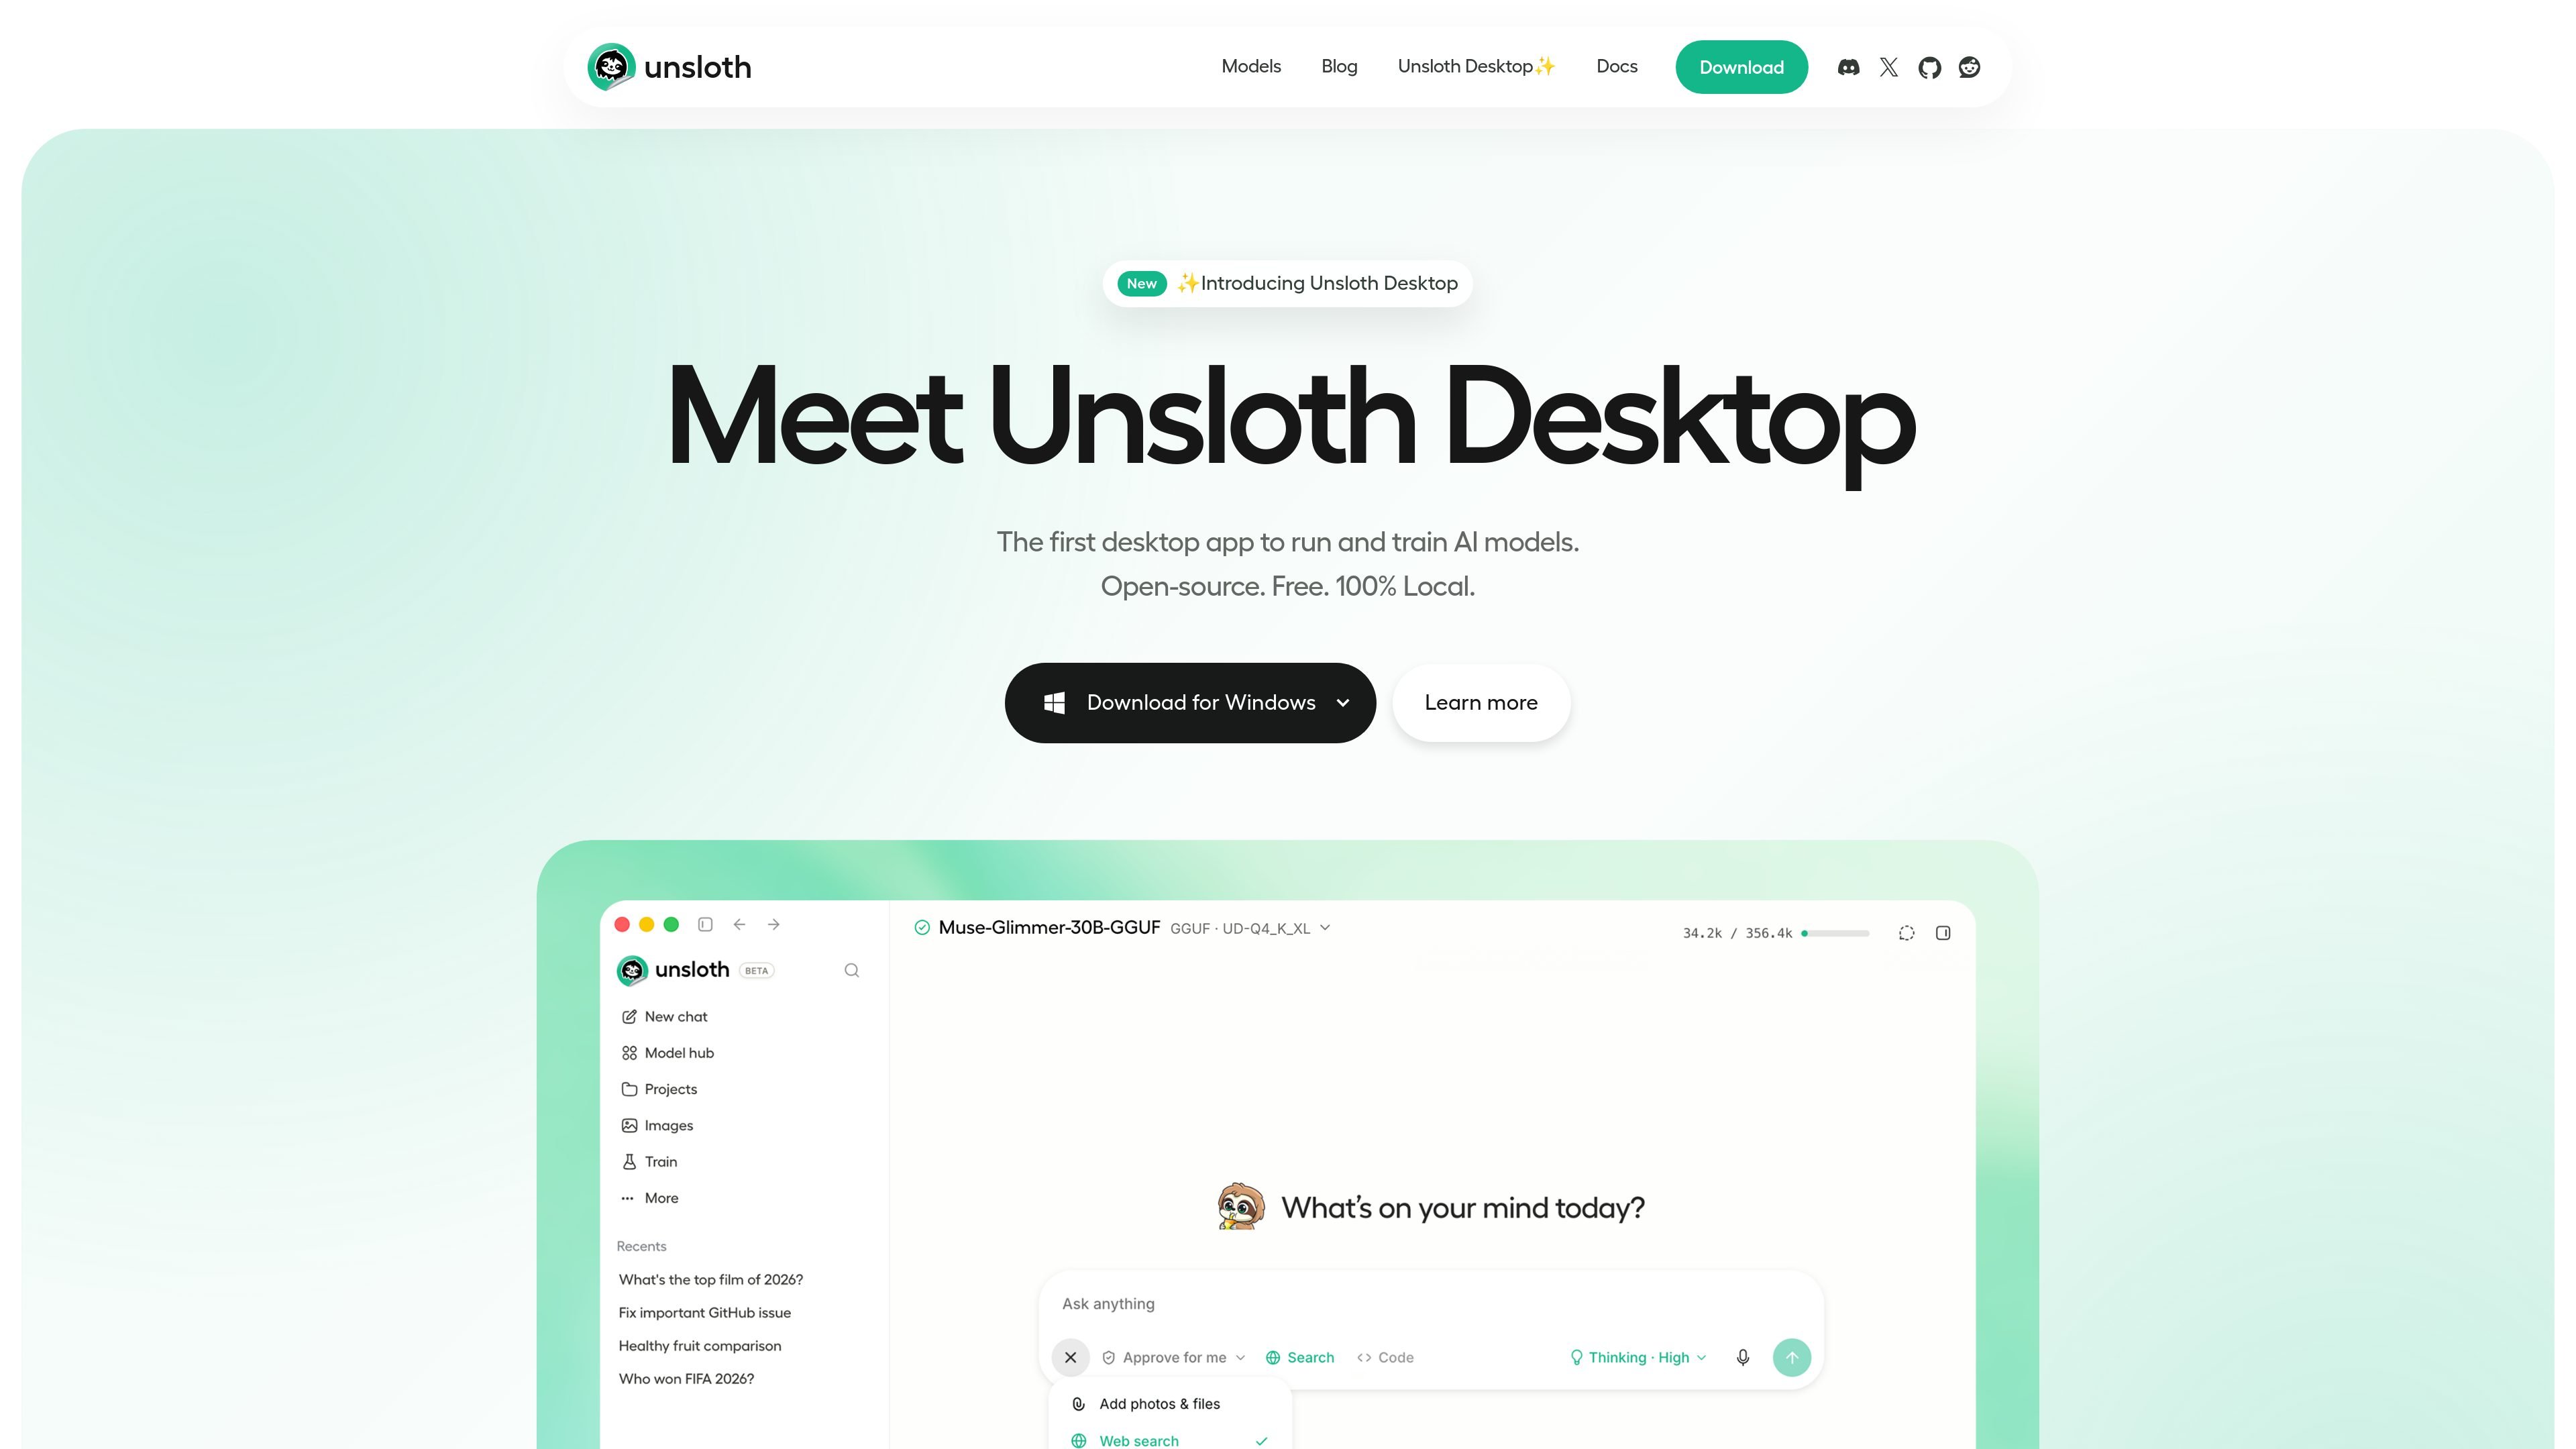
Unsloth is a free, open-source desktop app for running and training AI models on local hardware. It supports macOS, Windows, Linux, and WSL, with tools for model downloads, agent connections, media generation, and private research.

Soup CLI is a command-line tool for LLM fine-tuning and post-training on your own hardware. It supports low-VRAM training via layer streaming, plus data checks, configuration generation, preference optimization, and checkpoint gating.

What's my local AI? is a browser-based tool that detects your hardware locally and recommends which AI models may run on it with Ollama or LM Studio. It is aimed at people who want to choose local models without uploading machine data.
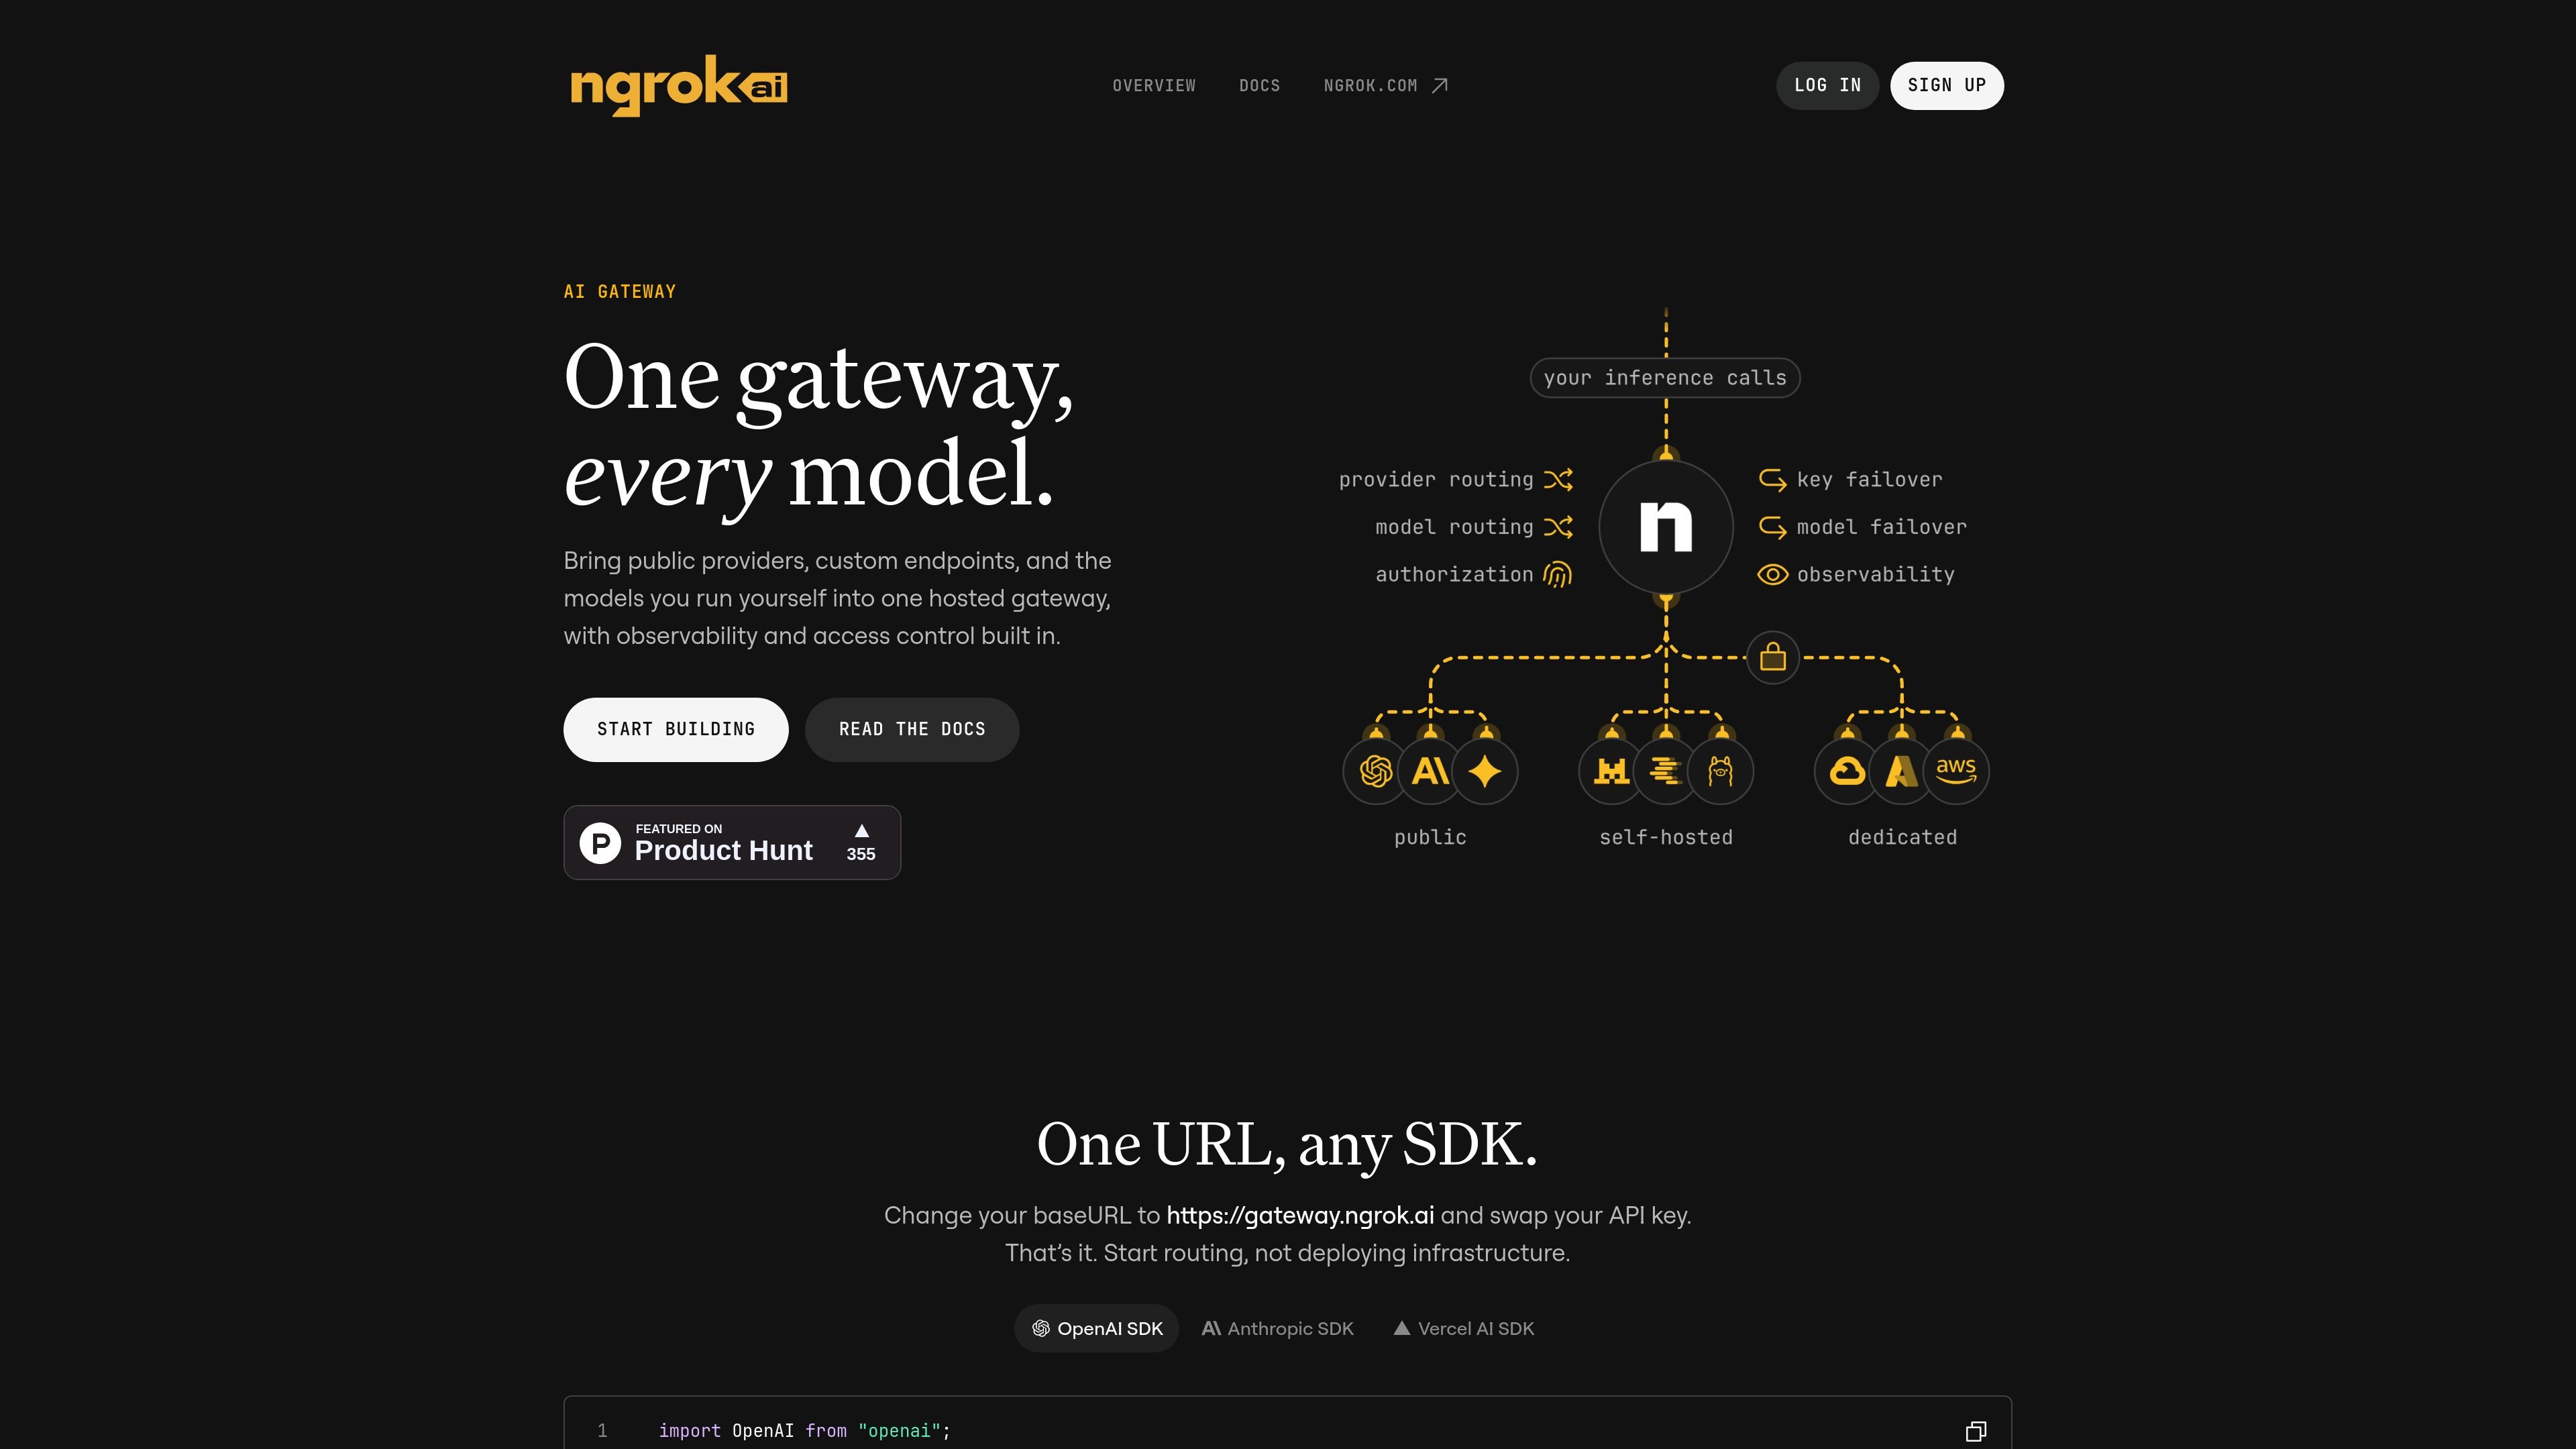

ngrok.ai is a hosted AI gateway that routes, secures, and manages traffic to cloud or local LLMs through a single URL. It helps developers standardize model access, add scoped controls, and monitor usage without rebuilding their app’s infrastructure.

DeepSeek-V4-Flash-0731 is DeepSeek-AI’s official release of the DeepSeek-V4-Flash model on Hugging Face. It is positioned for agentic and long-context workflows, with speculative decoding support and deployment guidance for vLLM, SGLang, and local inference.