
Per-request provider auction
Providers quote a price per token for each model, and the request is sent to the lowest-priced provider that satisfies the rules selected by the customer.
Liquid Inference routes each LLM request to the lowest-priced provider meeting your model, region, speed, and quality rules via compatible APIs.
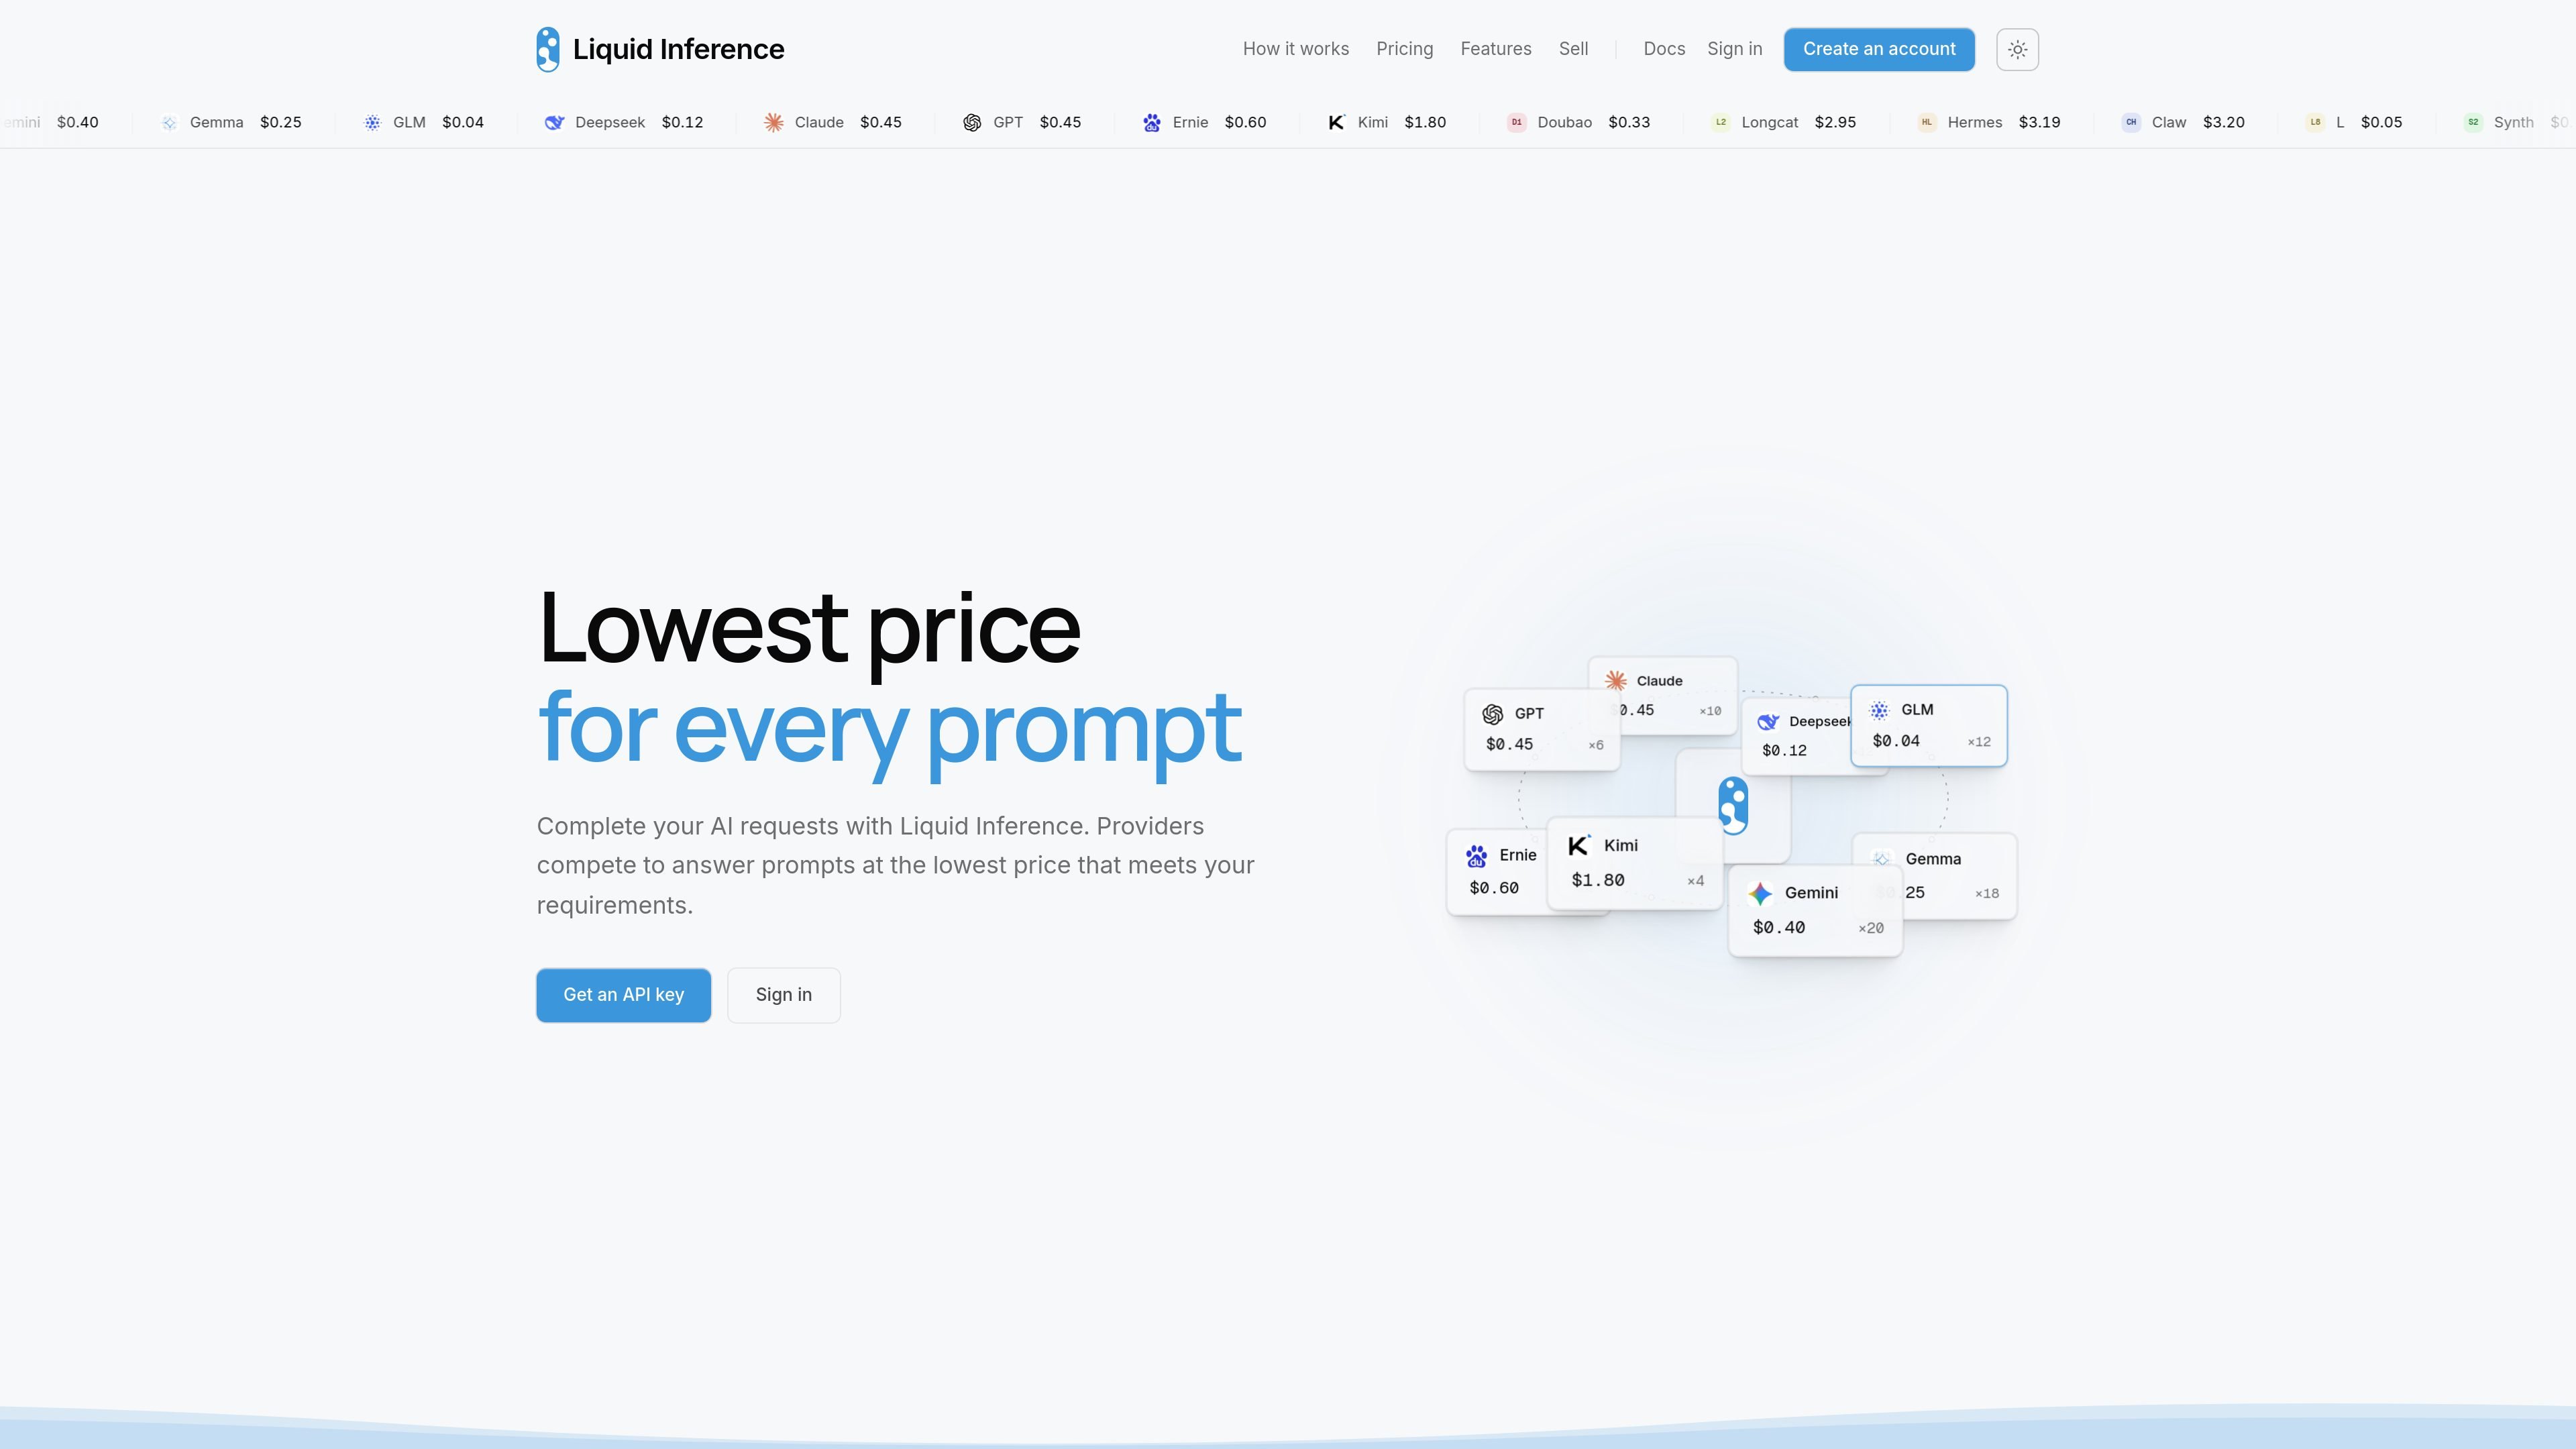
Liquid Inference is an inference router and auction exchange for large language model requests. It lets multiple providers compete on a request, then selects the lowest-priced offer that meets the customer's specified model, region, speed, and minimum-quality requirements.
The service is designed to fit into existing API workflows: its site documents OpenAI Chat Completions and Anthropic Messages through one base URL, with a Liquid Inference API key. It also exposes request cost information, provider quality measurements, and market price history for customers evaluating or managing inference spend.
Providers quote a price per token for each model, and the request is sent to the lowest-priced provider that satisfies the rules selected by the customer.
Customers can specify the model, region, speed, and minimum quality requirements used to determine which providers are eligible.
A price limit is set before generation begins, so the maximum request cost is known before the first token. Billing is based on produced tokens, with input tokens priced separately.
The service offers one base URL for OpenAI Chat Completions and Anthropic Messages, allowing compatible existing clients to change the endpoint and API key rather than rebuild the request workflow.
Liquid Inference says it tests providers regularly with standard benchmarks and publishes the resulting quality measurements for comparison.
Customers can view itemized request costs and download live and historical prices for models, supporting cost review and workload timing.
Teams with an existing OpenAI- or Anthropic-compatible application can test provider competition by changing the API base URL and API key while retaining their client workflow.
Engineering teams can set model, region, speed, and minimum-quality rules for workloads where cost matters but requests still need to meet operational or output requirements.
Operations or finance teams can inspect itemized request charges and use live or historical price information to compare model costs and decide when to send workloads.
AI infrastructure providers can register a deployment, submit it for review, connect an agent, and quote their own prices while controlling load by stopping quotes or changing prices.
Developers using compatible tools such as Claude Code, Codex, Cursor, LiteLLM, LangChain, or SDK-based clients can point supported workflows at the shared router endpoint.
Liquid Inference provides a router endpoint for OpenAI Chat Completions and Anthropic Messages. The site says existing clients can use the service by changing the base URL and supplying a Liquid Inference API key.
For each request, providers quote prices for the selected model. Liquid Inference applies the customer's rules, including model, region, speed, and minimum quality, and routes the request to the cheapest provider that meets them.
The service displays a maximum price for a request before generation begins. Customers are billed for the tokens the request produces, while input tokens are priced separately from output tokens.
The site lists OpenAI-compatible and Anthropic-compatible API workflows, and names clients and tools such as Claude Code, Codex, Cursor, OpenAI SDK, Anthropic SDK, LiteLLM, LangChain, and the Vercel AI SDK. The source does not provide full compatibility or model-coverage documentation.

Grok 4.7 is an xAI model for coding and knowledge work, available via Grok Build, Cursor, the Grok API and more, from $2 per million input tokens.
AakarDev AI helps teams manage AI provider access, project setup, logs, and analytics in one dashboard. BYOK support included.

BookAI allows you to chat with your books using AI by simply providing the title and author.

Skills Janitor is a GitHub-hosted set of slash commands for auditing, tracking, and cleaning up Claude Code and OpenAI Codex skills.

FeelFish is a PC client for AI-assisted novel writing, helping writers plan characters and settings, draft and revise novels, and manage story context.

Benchspan is an AI agent security platform that discovers agents, blocks prompt injection and data exfiltration in real time, and supports pre-launch red teaming.