
Structured domain model
Model a domain as doc_types, entities, and relationships so the brain has a defined structure instead of a flat prompt or ad hoc notes.

Open Index is an open-source structured context layer for AI agents. Build searchable, domain-specific brains agents can read, update, and serve locally or over HTTP.
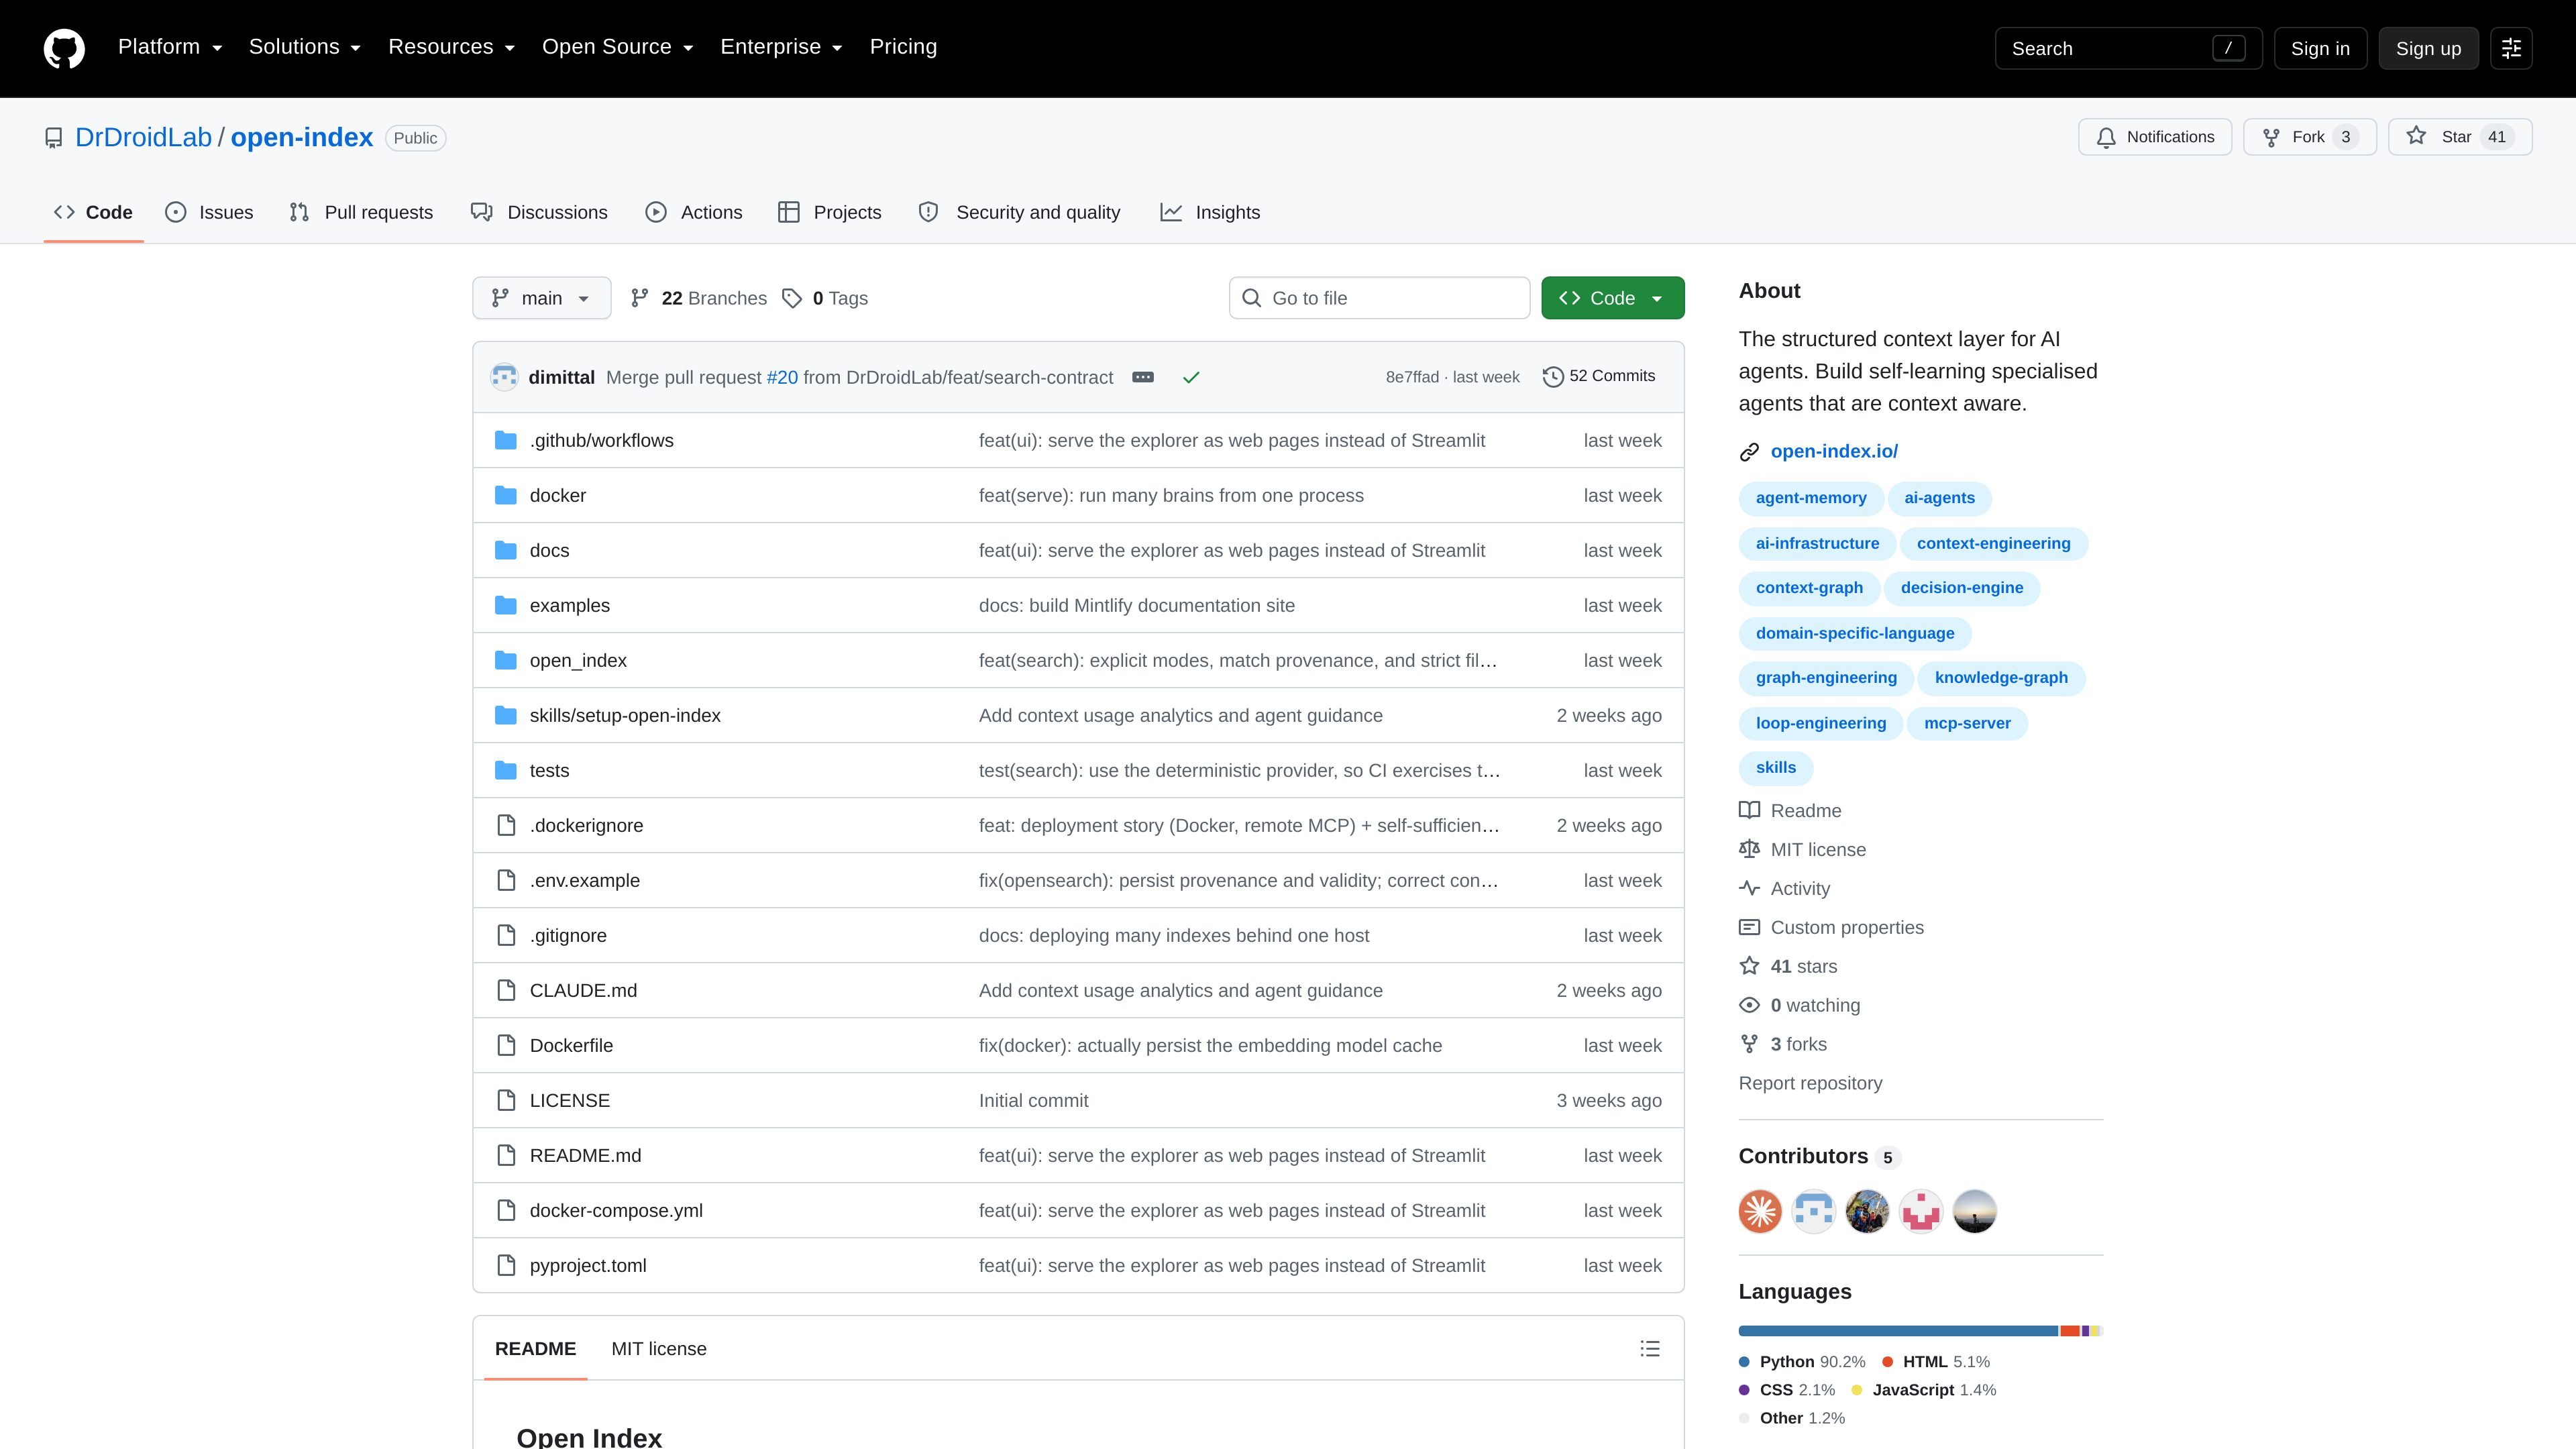
Open Index is an open-source tool for building a structured context layer for AI agents. It lets you define a domain as a set of doc types, entities, and relationships, then stores and searches that data so agents can operate on something more precise than an unstructured prompt or document dump.
The project is designed around a “brain” that can be created locally, served to agents over stdio or HTTP, and kept current through manual editing or connector-driven ingestion. The default setup uses SQLite with FTS5, while OpenSearch is available for remote or multi-writer deployments that need a separate search backend.
Model a domain as doc_types, entities, and relationships so the brain has a defined structure instead of a flat prompt or ad hoc notes.
Search entities from the terminal or through the MCP layer, with support for fuzzy, typo-tolerant search in the SQLite path and native k-NN search with OpenSearch.
Keep different kinds of data in the right place by choosing file-backed or index-backed storage per doc type, which helps separate curated content from connector-fed data.
Sync external data by running connectors, including MCP-based ingestion, and schedule connector runs through the built-in run command.
Expose the brain to agents over stdio or HTTP, with bearer-token auth available for remote HTTP serving and a config command to print the MCP block for agent setup.
Validate schemas, brain settings, and entity files, and provide a UI with How to use, Schema, Explore, Map, Analytics, and Jobs views for inspection.
A support team can model products, issues, segments, and comments so agents can search known problems and keep support knowledge current as new cases arrive.
An infrastructure team can store services, dashboards, runbooks, and alerts in a brain that agents can query while troubleshooting or updating operational context.
A sales or account workflow can map customers, deals, and related records so agents work from a structured pipeline rather than scattered notes.
A solo developer can start a local brain in a repository, index it, and connect Claude Code or another MCP client without hosting a separate service.
Open Index is a context layer for AI agents: it stores domain concepts as structured entities, searches them, and exposes them through an MCP server so agents can read and update the same brain.
The repository shows a local stdio mode, a remote HTTP mode, and a Docker-based deployment path. The deployment guide says local setups are typically used for a single agent on a machine, while remote setups fit teams, cloud agents, or CI that share one brain.
The docs describe read and write as the default MCP mode. Agents can retrieve context with navigation_guidelines(), search_brain(), and get_entity(), and update the brain with put_entity() and create_doc_type().
Yes. The docs say open-index init scaffolds a .mcp.json, CLAUDE.md, and an editing skill as conveniences for Claude Code, and the project also provides a portable Agent Skills file for other runtimes.
The project uses SQLite with FTS5 by default and can switch to OpenSearch for remote or multi-writer setups. The deployment guide notes that SQLite is single-writer, while OpenSearch is the option for several agents writing or for larger semantic search workloads.

garden-md is an open-source Node.js CLI that turns meeting transcripts into a local company wiki, linking entities and preserving the original text.

Goldfish is an AI memory app for macOS that helps you reply, write, summarize, and continue with context already on your Mac. It stores memory locally and writes in your tone.
Lasso is an ecommerce product data platform for enriching catalog records, processing supplier files, generating product content, and tracking competitors. It includes a web app, REST API, SDK, and MCP server.

CreateOS Sandbox is an isolated compute environment for running code and agent workloads in Firecracker micro-VMs with private networking and SDK, CLI, or MCP control.

ArtDeck is a visual reference board app for iPhone, iPad, and Mac. Collect mixed references on one canvas and study them with ToolBox lenses. Offline, optional iCloud sync, one-time purchase.

Codex Plugins bundle reusable skills, app integrations, and MCP servers into workflows you can install in the Codex app or use from Codex CLI.